Category: Agentic AI

  • The Agent Cookbook: 12 Patterns That Keep AI Agents Safe in Production

    Everyone is building agents. Almost nobody ships the safety layer.

    Demos are easy. Production is where agents approve the wrong thing, loop until the invoice arrives, call tools they were never meant to touch, and fail silently at 2 AM. The gap between a demo agent and a production agent is not a better model. It is a set of small, boring, essential patterns around the model.

    So I built them. The Agent Cookbook is an open-source repo of 12 production patterns for agentic AI — each one a small, runnable, copy-paste Python example. No framework. No API keys. Each pattern runs locally in under five minutes.

    Here is the whole cookbook on one page — the 12 patterns do four jobs.
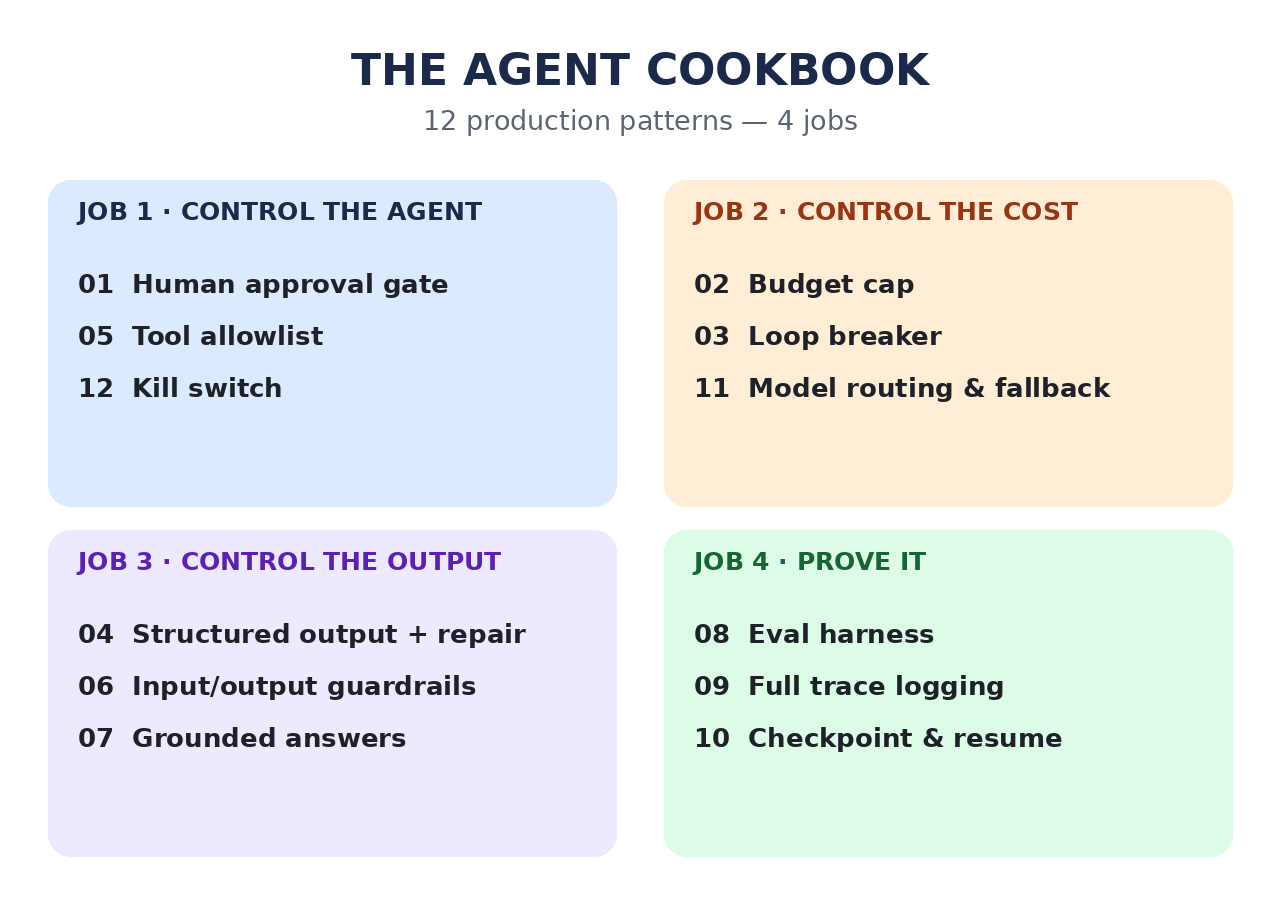
    Diagram: The Agent Cookbook's 12 patterns grouped into four jobs — control what the agent can do, control what it can spend, control what it can say, and prove what it did.

    Job 1: Control what the agent can do

    01 — Human approval gate. The agent proposes; a human disposes. Anything irreversible waits for a yes.
    05 — Tool allowlist. Least privilege for agents: the agent can only call the tools it is explicitly given. Everything else does not exist.
    12 — Kill switch. One flag that stops the agent now — not after the deploy, not after the meeting. Now.

    Job 2: Control what the agent can spend

    02 — Budget cap. A hard ceiling on tokens and cost per run. When the cap is hit, the agent stops, cleanly, with a reason.
    03 — Loop breaker. Agents love loops. This pattern counts, detects the spin, and breaks out before the bill does.
    11 — Model routing & fallback. Cheap model first, strong model when it matters, and a fallback path when the primary model fails.

    Job 3: Control what the agent can say

    04 — Structured output with repair. Demand a schema. When the output does not parse, repair it instead of crashing on it.
    06 — Input/output guardrails. Check what goes in and what comes out. Both directions. Every time.
    07 — Grounded answers. The agent answers from retrieved evidence — and says “I don’t know” when the evidence is not there.

    Job 4: Prove what the agent did

    08 — Eval harness. A small, repeatable test set the agent must pass before any change ships.
    09 — Full trace logging. Every step, tool call, and decision recorded. When someone asks “why did the agent do that?”, you have the receipt.
    10 — Checkpoint & resume. Long runs save state as they go. A crash becomes a pause, not a restart from zero.

    How to use it

    Clone the repo, pick the pattern your agent is missing, and run it — each folder under patterns/ has its own README and a single framework-free Python file:

    github.com/simplyjug/agent-cookbook

    The patterns are deliberately small. Copy one into your codebase, adapt it, and your agent gets a little more production-shaped. Stack all twelve and you have the safety layer most agent projects skip — the layer that decides whether your agent survives its first month in production.

    The repo is MIT licensed. If it saves you from one 2 AM incident, star it so the next engineer finds it — and subscribe below for the deep-dives: I will be taking individual patterns apart, one at a time, here on aiDeeva.

    The Agent Cookbook is maintained by Jugal Shah. Companion reading: The Agentic Architecture Framework — the method these patterns plug into.

  • The AI Engineering Iceberg: What It Really Takes to Ship AI to Production

    Anyone can build an AI demo. Connect an API, write a clever prompt, wrap it in a chat window — by Friday you have something that impresses a room. I’ve watched teams do it in a weekend.

    Then they try to put it in front of real users, and the iceberg shows up.

    Below the waterline of every AI demo sits roughly 90% of the actual engineering: the data pipelines, the retrieval tuning, the evals, the guardrails, the cost controls, the incident response. None of it is visible in the demo. All of it decides whether the thing survives contact with production.

    There’s a popular visual making the rounds — Jean Lee’s AI Engineering Iceberg — that captures this perfectly: a small tip above water (prompts, API calls, chatbots) and a massive submerged body of everything else. What follows is my version of what’s down there, drawn from years of shipping data and AI systems at enterprise scale.

    The visible tip

    Prompt engineering. Calling LLM APIs. Building chatbots.

    This is real work, and it’s where everyone starts. It’s also maybe 10% of a production system. The tip is the part you can learn in a weekend and demo on a Friday. Everything below takes the other 90% of the calendar — and nearly 100% of the budget that matters.

    The tip is also where most AI strategies stop. “We need an LLM strategy” usually means “we built a chatbot.” The organizations that get past this stage are the ones that ask what happens after the demo.

    Below the waterline: data

    Every production AI system I’ve seen fail failed on data first.

    Data pipelines — ingestion, cleaning, chunking, enrichment. The demo reads three PDFs. Production ingests thousands of documents in five formats, half of them scanned, with tables that break every parser you try.

    Retrieval engineering — hybrid search, reranking, metadata filtering. “RAG basics” is chatting with documents. Retrieval engineering is making the right document win, every time, when the corpus is messy and the questions are adversarial. This is where most RAG pilots quietly die: the retrieval looks fine on ten test queries and falls apart on ten thousand real ones.

    If your data foundation was built for dashboards, your agents are standing on a surface designed for human eyes. I wrote about this at length in the AI-ready data field guide — the short version is that data good enough for humans is not automatically good enough for machines.

    Below the waterline: quality

    Model evaluation — quality, accuracy, relevance, task success. The demo has no evals; it has a founder nodding at outputs. Production needs golden datasets, regression suites, and a definition of “good” that survives contact with edge cases.

    Observability — tracing prompts, tools, tokens, failures. When a user reports a wrong answer on Tuesday, you need to replay exactly what the system saw, retrieved, and decided. Without traces, debugging an AI system is archaeology.

    If you can’t measure it, you can’t ship it — you’re just hoping.

    Below the waterline: systems

    Agent orchestration — tools, workflows, memory, multi-agent coordination. The demo calls one model. Production orchestrates dozens of moving parts that fail independently and need to fail gracefully.

    Tool calling — schemas, permissions, retries, validation. Giving an LLM a tool is the tip. Making that tool call reliable, permissioned, idempotent, and auditable is the iceberg.

    Structured outputs — reliable JSON, parsing, schema enforcement. Downstream systems don’t consume vibes. Every handoff between the model and your software needs a contract.

    Reliability engineering — fallbacks, retries, timeouts, error handling. Models go down, rate limits hit, latency spikes. Production AI needs the same resilience discipline as any distributed system, because it is one.

    Below the waterline: operations

    This is the layer nobody demos and everybody pays for.

    Cost and latency optimization — token budgets, smaller models, smart routing, caching, batching, streaming. The pilot costs $200. Production costs $200,000. Nobody budgets for it until the first invoice arrives.

    CI/CD for AI — testing prompts, workflows, models, deployments. Prompts are code now: versioned, reviewed, tested, rolled back.

    Production monitoring — drift, quality degradation, usage, incidents. Models don’t stay good by themselves. Data drifts, user behavior shifts, and yesterday’s eval scores quietly decay.

    Security, governance, and human-in-the-loop — authentication, secrets, prompt-injection defenses, data governance, approvals and escalation workflows. Mapped to something like the NIST AI Risk Management Framework, this is the layer that keeps you out of the news.

    What this means for leaders

    Three implications if you’re funding or hiring for AI:

    Budget for the iceberg, not the tip. If your AI budget covers models and prompts, you’ve budgeted for 10% of the system. The teams that blow up do so in the submerged 90% — usually on data and evals they never planned for.

    Hire for what’s below the waterline. Anyone can demo. In interviews, skip the chatbot questions and ask about the submerged part: how they’d debug wrong answers in production, cut inference cost 10x, design an eval harness, or make AI writes to a CRM safe. The answers reveal who’s shipped and who’s watched tutorials.

    Don’t let the pilot set the architecture. Two-week pilots prove the tip. That’s their job. But plan the production architecture — retrieval, evals, guardrails, cost controls — from day one, or you’ll rebuild everything the pilot validated.

    The demo is the tip

    None of this is an argument against demos. Demos are how you learn, get funding, and build momentum. Just don’t mistake the tip for the iceberg.

    The organizations shipping AI that actually works all learned the same lesson, usually the expensive way: production is the iceberg. Build for what’s below the waterline, and the tip takes care of itself.


    — Jugal

  • The Agentic Enterprise, October 2026: The Framework I Wish I’d Had

    Hi — Jugal here.

    This week I published something I’ve been building toward for years: the Agentic Architecture Framework — a practitioner’s method for architecting AI systems on a real data foundation. If you know TOGAF, you’ll recognize the shape. If you don’t, here’s the one-line version:

    It’s a disciplined way to answer “where does AI earn its keep here?” — and keep answering it as the system grows.

    This edition isn’t a recap of the article. It’s the part I couldn’t fit in it: the deeper cut, the worked example, and something I’m only sharing with you — a self-assessment you can run on your own organization Monday morning.

    The framework in 90 seconds

    Six components:

    1. 12 principles — the rules every AI initiative gets judged against (business value first, data quality as prerequisite, evals before enthusiasm, humans in the loop by design, cost as architecture, and seven more)
    2. The AI Delivery Cycle — six phases plus a preliminary: Vision & Value → Data Foundation

      The deeper cut: what “data readiness” actually looks like


      The phase that kills the most bad AI projects is Phase B — Data Foundation. Not because data teams fail, but because nobody asks for a verdict. So here’s what a real Data Readiness Assessment looks like, worked through on a realistic example.


      Scenario: you want an AI assistant that answers customer questions from your support knowledge base and ticket history.


      The assessment asks five questions per data source:


      1. Quality — Of 50,000 tickets, how many have a correct resolution recorded? (In most orgs: 60–70%. The rest are “closed” with no usable answer.)

      2. Completeness — Do you have the product documentation the answers depend on? Is it current?

      3. Freshness — How stale is the oldest article the assistant might quote? If it’s three years old, the assistant will confidently give wrong answers.

      4. Lineage — Can you trace an answer back to the ticket or article it came from? If not, you can’t fix bad outputs.

      5. Access & rights — Does the assistant have legal access to all of it? Support tickets often contain customer PII that changes what you’re allowed to do.


      The verdict format is binary per source: GO or NO-GO — with conditions. Example: “Ticket history: CONDITIONAL GO — usable after filtering to tickets with verified resolutions (est. 65% of corpus). Knowledge base: NO-GO — 40% of articles outdated; remediation required before training.”


      That verdict, written down and signed off, is worth more than any model evaluation. Because a brilliant model on unready data is just a faster way to be wrong.


      Subscriber exclusive: the maturity self-assessment


      Run this on your organization. Be honest — no one sees the score but you.


      Level 1 — Exploring. AI curiosity, no production systems. You’re here if: the AI conversation is mostly conference talks and vendor demos.


      Level 2 — Experimenting. Pilots and demos exist. You’re here if: you can name three pilots, but none has a production date.


      Level 3 — Piloting. First


      Try this week


      Pick one AI initiative — just one — and score it against three principles:


      1. Can you name its business outcome in one sentence? (Principle 1)

      2. Has anyone issued a written data-readiness verdict? (Principle 2)

      3. Does it have an eval harness that could catch a regression tomorrow? (Principle 3)


      If the answer to any of these is no, you don’t have an AI project yet. You have homework. That’s fine — now you know what it is.


      What’s next


      Next month: governance that accelerates — what the NIST AI Risk Management Framework looks like running inside a real AI system, not a compliance deck. If this edition resonated, that one’s for you.


      As always, reply to this email — I read every one.


      — Jugal


      The Agentic Enterprise is a monthly newsletter on production AI, agentic systems, and enterprise data architecture. Browse the archive · aideeva.com


      production AI workloads. You’re here if: something is live, and governance/HITL is the bottleneck.


      Level 4 — Scaling. Multiple AI systems in production. You’re here if: cost control and reuse are your main problems — congratulations, those are good problems.


      Level 5 — Leading. AI is a managed capability with feedback loops, mature evals, governed expansion. You’re here if: you can run the full delivery cycle in your sleep.


      The uncomfortable pattern: most enterprises score themselves at 2 and plan like they’re at 4. If that’s you, the fix isn’t more ambition — it’s Phase B and Phase D done properly, before anything else.


      → Intelligence Architecture → Evaluation → Governance & Deployment → Operate & Evolve

    3. A content framework — what you actually produce in each phase (not shelfware: signed-off deliverables like the Data Readiness Assessment and the Evaluation Plan)
    4. Three reference architectures — RAG, agent, and eval-harness blueprints you tailor instead of reinventing
    5. Governance mapped to NIST AI RMF — Govern, Map, Measure, Manage, woven through the cycle instead of bolted on after
    6. A 5-level maturity model — from Exploring to Leading, so you can locate yourself honestly

    Read the full article here: The Agentic Architecture Framework

    And if you’re the one who has to explain AI to a board: I also published the executive companion this week — How CIOs and CTOs Should Approach AI.

    That verdict, written down and signed off, is worth more than any model evaluation. Because a brilliant model on unready data is just a faster way to be wrong.

  • The Agentic Architecture Framework: A TOGAF-Style Method for AI & Data

    Enterprise architecture has a trusted method for designing technology change: TOGAF and its Architecture Development Method (ADM). But TOGAF was built for a world of deterministic systems — applications with known inputs, predictable outputs, and release cycles you could plan on a Gantt chart.

    AI systems don’t behave that way. They are probabilistic. They learn, drift, hallucinate, and compound cost silently in multi-step loops. The data they depend on is rarely ready. And the governance models built for traditional software either block AI entirely or wave it through unexamined.

    This article proposes the Agentic Architecture Framework — a practitioner’s method for architecting AI systems on a real data foundation. If you know TOGAF, you already know its shape: principles, a development method, a content framework, reference architectures, and governance. What’s different is what it confronts: data readiness, evaluation, model economics, and human judgment as first-class architectural concerns.

    This isn’t a standard. It’s a field method — drawn from shipping production AI and data platforms at scale — for anyone who has to answer the question: where does AI actually earn its keep here, and how do we build it so it keeps earning it?

    Why TOGAF alone isn’t enough for AI

    TOGAF’s ADM is excellent at what it was designed for: aligning business, data, application, and technology architecture through a disciplined, iterative cycle. But apply it directly to an agentic AI initiative and four gaps appear:

    1. Data readiness is assumed, not assessed. TOGAF’s Phase C covers data architecture, but AI needs something stricter: a verdict on whether the data is fit for machine consumption — quality, lineage, freshness, access, and bias.
    2. Evaluation has no home. Traditional architecture assumes you can specify behavior. AI behavior is emergent. Without a dedicated evaluation discipline — eval harnesses, red-teaming, offline-to-online validation — you’re shipping hope.
    3. Cost is not an architecture concern. TOGAF plans migration cost; it doesn’t account for token spend compounding across agent loops at 3 AM. In A
    4. Governance is a gate, not a loop. Phase G governs implementation, but AI systems need continuous governance — drift detection, feedback loops, and human-in-the-loop placement that evolves as the system learns.

    Most AI failures are data
    failures wearing an AI costume.

    In AI, cost is architecture.

    The Agentic Architecture Framework keeps TOGAF’s skeleton and rebuilds the muscle for AI.

    The framework at a glance

    Six components, mirroring the structure architects already know:

    1. Architecture Principles — the 12 rules every AI initiative is judged against.
    2. The AI Delivery Cycle — the method itself: Preliminary + six phases (A–F), iterative, not waterfall.
    3. The Content Framework — what you produce in each phase (artifacts and deliverables).
    4. Reference Architectures — reusable blueprints: the RAG blueprint, the agent blueprint, the eval harness blueprint.
    5. Governance — mapped directly to the NIST AI Risk Management Framework (Govern, Map, Measure, Manage).
    6. The Maturity Model — five levels, from Exploring to Leading, so you can locate any organization honestly.

    Component 1: The 12 principles

    Principles are the framework’s conscience. Every design decision should be traceable to one of these:

    1. Business value first, models second. No AI initiative exists without a named business outcome and an ROI thesis.
    2. Data quality is an AI prerequisite, not a data problem. If the data isn’t fit, the AI isn’t ready. Say so early.
    3. Evaluation before enthusiasm. No model, agent, or pipeline reaches production without an eval harness that can catch regressions.
    4. Humans in the loop by design. Place human judgment where the cost of error is highest — deliberately, not as an afterthought.
    5. Cost as an architecture concern. Token spend, compute, and data pipeline cost are designed in, with budgets per workflow.
    6. Deterministic where possible, probabilistic where valuable. Don’t pay for an agent to do what a rule, a lookup, or a smaller model does better.
    7. Lineage is non-negotiable. Every AI output should be traceable to the data and model version that produced it.
    8. Governance that accelerates. Guardrails ship with the system — as code, as evals, as contracts — never as a committee that meets after launch.
    9. Start narrow, earn the right to expand. One workflow, done well, beats five pilots that never reach production.
    10. Security and privacy by construction. Data access, PII handling, and model exposure are architectural inputs, not audit findings.
    11. Observability from day one. If you can’t see what the system did and why, you can’t operate it.
    12. Learn in production. Feedback loops, drift detection, and retraining aren’t maintenance — they’re the system working as designed.

    Component 2: The AI Delivery Cycle

    The method. Iterative, tailorable, and familiar to anyone who’s run an ADM cycle. Requirements management runs continuously through the center — same as TOGAF.

    Preliminary — Principles & Posture. Establish the AI principles (above), define risk appetite, stand up the governance scaffolding, and tailor the framework to the organization. Maps to NIST AI RMF Govern.

    Phase A — Vision & Value. Define the business outcome in plain language. Where does AI earn its keep here? Produce the AI Vision: the outcome, the ROI thesis, the explicitly-named non-goals. Get stakeholder sign-off before a single model is evaluated.

    Phase B — Data Foundation. Assess data readiness brutally: quality, completeness, freshness, lineage, access rights, and bias. Remediate or descope. Output: the Data Readiness Assessment — a go/no-go verdict per data source. This phase kills more bad AI projects than any other, and that’s its job.

    Phase C — Intelligence Architecture. Design the AI itself: model selection and routing, retrieval architecture, agent decomposition, tool use, and the deterministic-vs-probabilistic split. Build-vs-buy decisions live here. Output: the Intelligence Architecture with cost projections per workflow.

    Phase D — Evaluation. Build the eval harness before production: offline benchmarks, golden datasets, red-teaming, and the promotion criteria for online testing. Define what “good” means numerically — and what triggers a rollback. Output: the Evaluation Plan with pass/fail thresholds.

    Phase E — Governance & Deployment. Map risks (NIST AI RMF Map), measure them (Measure), and put controls in place (Manage). Place human-in-the-loop checkpoints where error cost is highest. Deploy in stages behind the eval harness. Output: the Risk Register, the HITL design, and the staged rollout plan.

    Phase F — Operate & Evolve. Run it like a production system: cost monitoring against the budgets set in Phase C, drift detection, feedback loops feeding back into evals, and a defined change process for model updates. Output: the Operations Runbook — and the input to the next cycle.

    Then cycle again. AI systems are never “done”; each cycle deepens the data foundation, sharpens the evals, and expands scope only where value is proven.


    Component 3: The Content Framework

    Every phase produces artifacts (working products) and deliverables (signed-off outputs). The core set:

    PhaseKey deliverableSupporting artifacts
    PreliminaryAI Principles sign-offRisk appetite statement, governance charter
    A — Vision & ValueAI VisionROI thesis, non-goals list, stakeholder map
    B — Data FoundationData Readiness AssessmentData quality scorecard, lineage map, access matrix
    C — Intelligence ArchitectureIntelligence ArchitectureModel routing table, cost projections, build-vs-buy analysis
    D — EvaluationEvaluation PlanGolden datasets, red-team findings, promotion criteria
    E — Governance & DeploymentRisk Register + rollout planHITL design, control mappings, rollback procedures
    F — Operate & EvolveOperations RunbookCost dashboards, drift reports, feedback-loop specs

    A deliverable is reviewed and signed off. An artifact is lived in. Confuse the two and you get shelfware.


    Component 4: Reference architectures

    Don’t redesign what repeats. The framework ships with three starting blueprints, tailored per engagement:

    • The RAG blueprint. Ingestion → chunking → embeddings → vector store → retrieval → generation → eval. With the data-readiness gates from Phase B baked into ingestion, and the eval harness from Phase D wrapped around retrieval quality.
    • The agent blueprint. Planner → tools → memory → human checkpoints → output validation. With loop budgets (max steps, max cost per run), deterministic fallbacks, and HITL placement per Principle 4.
    • The eval harness blueprint. Golden dataset → offline eval → shadow mode → canary → production monitoring. The promotion ladder every AI system climbs, with rollback criteria at each rung.

    Component 5: Governance — the NIST AI RMF mapping

    Governance in this framework isn’t a separate track; it’s woven through the cycle, mapped to the NIST AI Risk Management Framework’s four functions:

    • Govern → Preliminary phase. Culture, accountability, risk appetite, and the principles themselves.
    • Map → Phases A–C. Context, categorization, and risk identification as the vision, data, and architecture take shape.
    • Measure → Phase D. Evaluation, red-teaming, and quantified risk — the numbers behind the verdicts.
    • Manage → Phases E–F. Controls deployed, risks tracked, feedback loops running in production.

    If your organization already runs a NIST AI RMF program, this framework slots into it. If it doesn’t, the framework gives you the program.


    Component 6: The Maturity Model

    Five levels. Be honest about where you are — the framework meets you there:

    1. Exploring. AI curiosity, no production systems. Focus: Preliminary + Phase A. Pick one outcome.
    2. Experimenting. Pilots and demos exist. Focus: Phase B + D. Kill what the data can’t support; eval what survives.
    3. Piloting. First production AI workloads. Focus: Phase E. Governance and HITL are the bottleneck — fix them.
    4. Scaling. Multiple AI systems in production. Focus: Phase F + reference architectures. Cost control and reuse separate winners here.
    5. Leading. AI is a managed capability with feedback loops, mature evals, and governed expansion. Focus: cycle speed — how fast can you run the Delivery Cycle well?

    Most enterprises sit at 2. Most AI strategies assume they’re at 4. The maturity assessment exists to close that gap before it closes your budget.

    How to use it

    1. Start with the maturity assessment. One workshop, honest scoring, no vanity.
    2. Run Preliminary once — principles and posture are enterprise-level, not per-project.
    3. Run the cycle per initiative — Phases A through F, tailored. A narrow internal tool gets a light pass; a customer-facing agent gets the full treatment.
    4. Build the reference architectures as you go. Your second RAG system should be 70% reuse.
    5. Let Phase F feed Phase A. The learnings from operations are the most valuable input to the next vision.

    Closing

    TOGAF gave enterprise architecture a shared language for the deterministic era. The agentic era needs its own — one where data readiness is a verdict, evaluation is a discipline, cost is designed in, and governance ships with the system instead of chasing it.

    That’s what this framework is for. It’s a starting point, deliberately: tailor it, argue with it, and let production teach you the rest.

    The best framework is the one your teams actually run — cycle after cycle, until “where does AI earn its keep?” is a question you can answer with evidence.


    Jugal Shah writes about production AI, agentic systems, and enterprise data architecture at aideeva.com, where he publishes The Agentic Enterprise newsletter.

  • Agentic AI Boot Camp: A Hands-On Journey

    I just finished an intensive, hands-on boot camp on agentic AI and it exceeded my expectations. Over the course of the program I moved from curiosity to practical capability — building small, testable agents, understanding safety tradeoffs, and shipping reproducible experiments. If you’re curious what a focused, project-driven AI boot camp looks like, here’s a recap you can post on your blog.

    Introduction

    • This boot camp blends foundational theory with practical labs, giving learners immediate experience deploying agentic systems. It’s ideal for fast learners who want both conceptual clarity and tangible projects to show in a portfolio.

    What we covered

    • Foundations: Core concepts in LLMs, prompt engineering, chain-of-thought reasoning, and behavior design for agents.
    • Safety & Ethics: Practical safety checks, guardrails, and how to think about misuse and mitigation strategies when agents act autonomously.
    • Data & Ingestion: Techniques for sourcing, cleaning, chunking, and deduplicating data for memory and retrieval.
    • Modeling & Fine-Tuning: When to fine-tune vs prompt-engineer, lightweight fine-tuning workflows, and evaluation best practices.
    • Agent Design & Orchestration: Composing tools, planning loops, memory strategies, and how to design agent workflows that are reliable and testable.
    • Deployment: Minimal reproducible deployments, observability basics, and integrating telemetry and metrics.

    Highlights & Projects

    • Capstone Project: Each participant built a small agent that solved a real task — for example, a PDF assistant that extracts structured answers, or an agentic pipeline that iteratively refines a draft using retrieval-augmented feedback loops.
    • Hands-on Labs: Weekly labs focused on concrete skills: creating ingestion pipelines, implementing semantic deduplication, writing evaluation suites, and automating tests for agents.
    • Safety-first Exercises: Threat modeling sessions where we enumerated possible misuse, then implemented simple mitigations (rate limits, input sanitization, and layered human-in-the-loop checks).
    • Reproducibility: Every lab included reproducible artifacts — scripts, small datasets, and automated tests — so the work can be re-run, explained in interviews, or extended later.

    Key takeaways

    • Agents are composition-first. Real capability comes from connecting models to reliable tools, data, and state (memory).
    • Small, iterated experiments beat big, brittle prototypes. Start with a minimal loop, measure, then extend.
    • Safety and evaluation are not optional. The simplest automatic behaviors can cause failure modes; build tests and monitors early.
    • Clear documentation and reproducible code make your learning visible to others — and make it easier to iterate later.

    Github Repo : https://github.com/simplyjug/AgenticAIBootCamp