Tag: llm

  • The 9 Types of RAG, Explained: Pick the Right Architecture (and Survive the Interview)

    Every RAG system that fails in production fails the same quiet way. The demo worked. The model was fine. Then real users arrived with real questions — misspelled product codes, questions that span four documents, questions the knowledge base simply cannot answer — and the system started producing confident, fluent, wrong answers.

    Nine times out of ten, the problem is not the model. It is the architecture choice. Somebody picked the simplest possible retrieval design, shipped it, and never revisited the decision when the questions outgrew it.

    That is what this guide is for. There are nine RAG architectures worth knowing. They are not nine competing products — they are nine answers to nine different failure modes. By the end, you should be able to do three things: look at a use case and pick the right type, explain why in plain language, and hold your own when an interviewer starts pushing on the trade-offs.

    One rule before we start, and it is the rule every experienced builder I know follows: start with the simplest architecture that could work, and add complexity only when a specific, observed failure demands it. Every layer you add buys accuracy with latency, cost, and moving parts. Spend that budget only where the failures actually are.

    First, the vocabulary (because interviews are lost here)

    Most RAG explanations drown in jargon. Let us fix that first, because every architecture below is built from these same blocks.

    Embedding. A piece of text converted into a list of numbers (a vector) that captures its meaning. Texts with similar meanings get similar numbers. This is how a system can know that “how do I reset my password” and “forgot my login credentials” are asking the same thing, even though they share almost no words.

    Chunking. Splitting documents into smaller pieces before storing them. Embeddings work on chunks, not whole documents — a 200-page manual embedded as one blob matches everything and nothing. Chunk size is a genuine design decision: too small and you lose context, too large and you dilute the signal.

    Vector database. A database built to store embeddings and find the nearest ones to a query, fast. When people say “semantic search,” this is the machinery underneath it.

    Top-K. How many chunks you pull back from the search. Top-K of 5 means “give me the 5 closest chunks.” More is not better — every irrelevant chunk you hand the model is an invitation to wander.

    Reranking. A second, slower, more careful scoring pass. The vector search retrieves, say, 50 candidate chunks quickly and approximately; a reranker (often a cross-encoder model that reads the question and each chunk together) reorders them by true relevance and keeps the best few. Cheap retrieval for recall, expensive reranking for precision.

    BM25. The classic keyword search algorithm — the technology behind decades of search engines. It matches actual words, weighted by rarity. Terrible at meaning, unbeatable at exact strings: error codes, part numbers, names, SKUs.

    Dense vs. sparse retrieval. Dense = embedding-based (meaning). Sparse = keyword-based, like BM25 (exact words). Remember this pair; Hybrid RAG is just the two of them holding hands.

    Knowledge graph. Information stored as entities and relationships — Customer → placed → Order → contains → Product — instead of as text chunks. You query it by traversal: following the links.

    Grounding / faithfulness. Whether the answer is actually supported by the retrieved material, as opposed to the model improvising. The central quality question of every RAG system.

    Hallucination. The model generating something fluent and false. In RAG, hallucination usually means the model answered beyond — or against — the context it was given.

    Context window. How much text the model can consider at once, measured in tokens. Modern models offer 128K tokens and far beyond — which is what makes Long-Context RAG (type 9) possible at all.

    With that in hand, the nine types will read easily.


    1. Naive RAG — the baseline everything else improves on

    How it works. Documents are chunked, embedded, and stored in a vector database. A user question is embedded with the same model, the database returns the Top-K most similar chunks, those chunks are pasted into the prompt, and the LLM writes an answer from them. Four moving parts. You can build it in an afternoon.
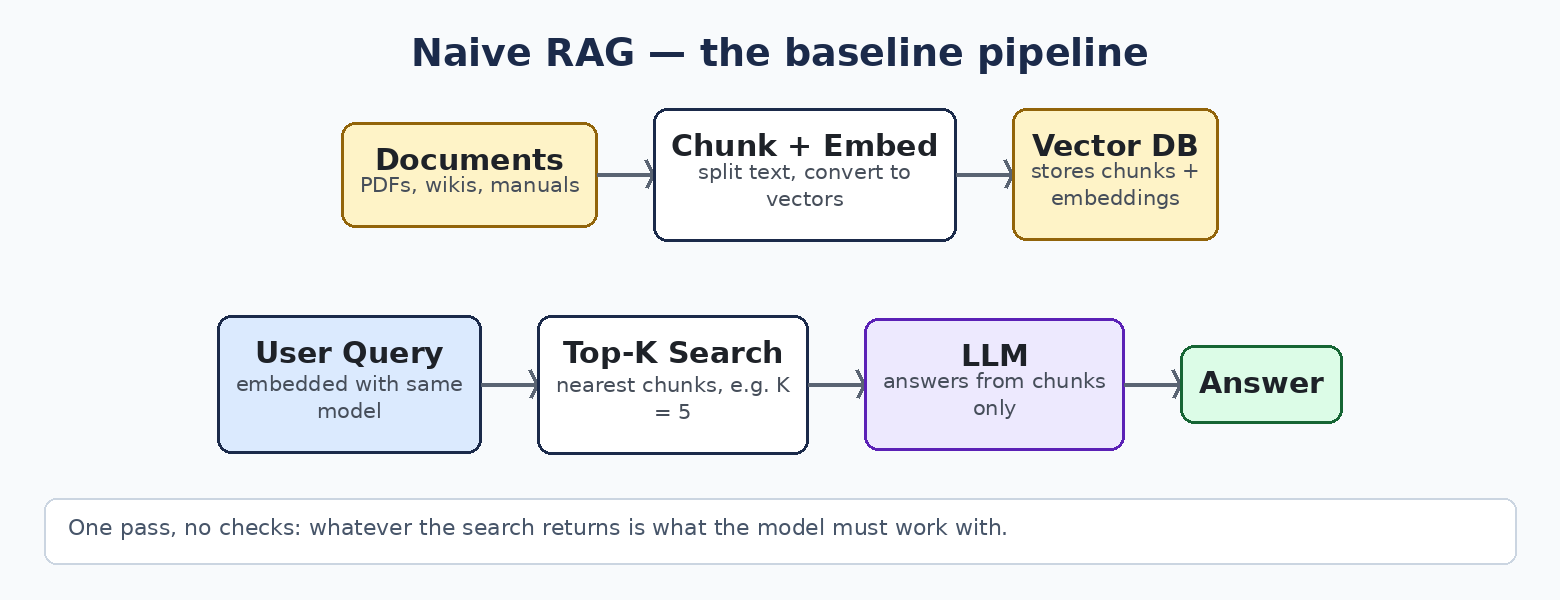
    Naive RAG diagram

    When it earns its place. Internal document Q&A over a modest, well-behaved corpus. A proof of concept. Anywhere the questions are simple, the documents are the single source of truth, and “mostly right” is acceptable while you learn.

    Where it breaks. Retrieval quality is the whole game, and naive retrieval is weak: chunk boundaries cut answers in half, the closest chunk by embedding is often not the chunk that answers the question, and there is no mechanism to notice failure. It retrieves once, blindly, and the model must make the best of whatever came back.

    Say it in the interview. “Naive RAG is my starting point for any retrieval problem — it is the baseline you measure everything else against. I move beyond it the moment I can name the specific way retrieval is failing, because each advanced pattern exists to fix a particular failure.”

    2. Advanced RAG — fixing retrieval before and after the search

    How it works. Advanced RAG keeps the naive skeleton and wraps it with effort on both sides of the search. Before retrieval: the user’s question is rewritten (expanded, clarified, or split into sub-questions), because users ask badly and embeddings punish vague queries. After retrieval: results are filtered by metadata and reranked, so the model sees the best few chunks rather than the merely closest ones.
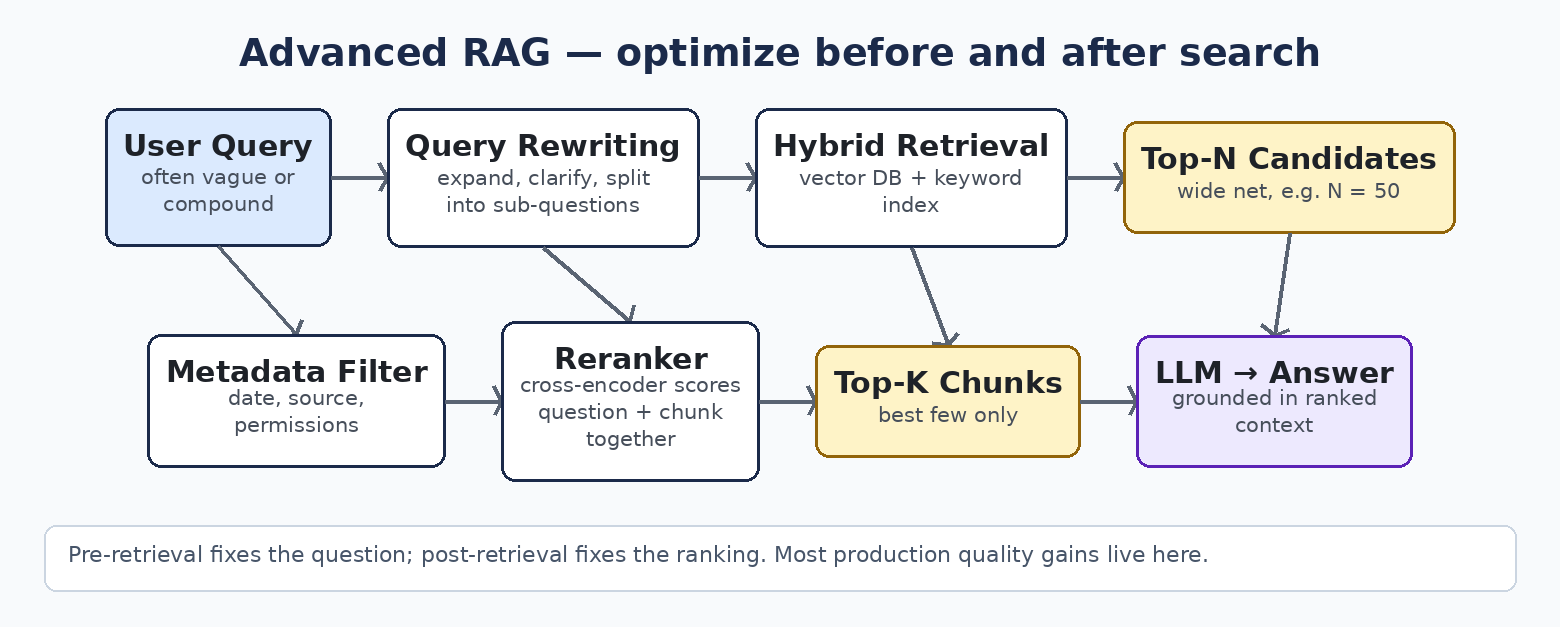
    Advanced RAG diagram

    When it earns its place. When your naive system retrieves almost the right material — relevant documents exist, but the wrong passages surface. Complex or domain-specific corpora, where vocabulary is precise and questions are not. This is the single most common upgrade in production systems, because most RAG quality problems are retrieval problems wearing a disguise.

    Where it breaks. Every added stage is latency and a tuning surface. A bad query rewrite can drag retrieval further from the answer than the original question would have. You now have knobs — rewrite strategy, filter logic, reranker choice, Top-K at each stage — and knobs demand evaluation, or you are tuning by vibes.

    Say it in the interview. “Advanced RAG is pre-retrieval and post-retrieval optimization around the same core loop. Query rewriting fixes the question, reranking fixes the ranking. In my experience it is where the largest quality gains per dollar live.”

    3. Modular RAG — RAG as interchangeable parts

    How it works. Instead of one fixed pipeline, the system is decomposed into modules — a query module, a retrieval module, a reranking module, a generation module — each swappable, each potentially backed by different sources: a vector database here, a document store there, an API or a SQL database alongside. Different queries can be routed through different combinations.
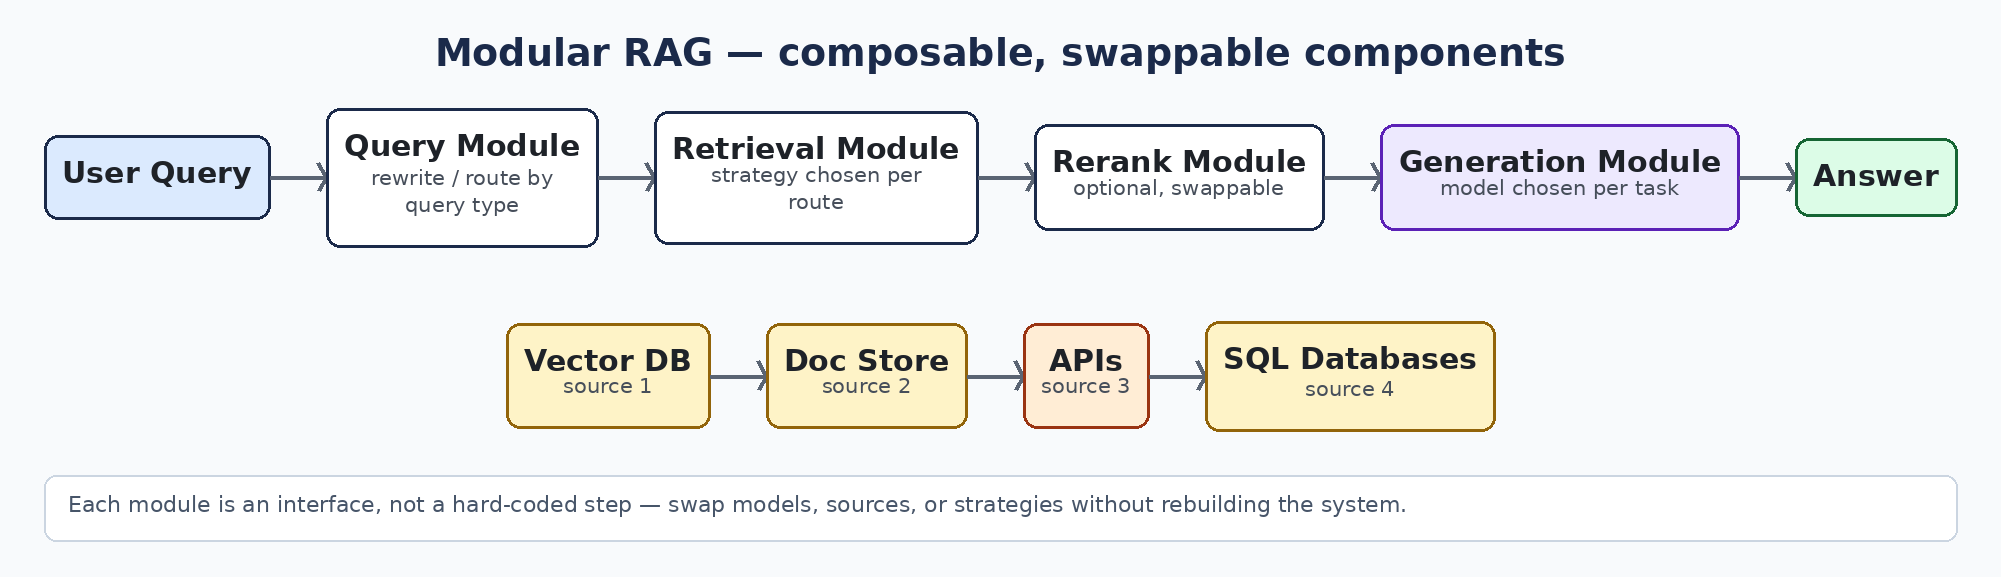
    Modular RAG diagram

    When it earns its place. Platforms, not features. When one team serves many use cases, when you need to experiment with components without rebuilding the system, or when different query types genuinely need different strategies. Modular RAG is less an architecture you choose on day one and more the shape a maturing system grows into.

    Where it breaks. Abstraction is not free. You are now maintaining an orchestration layer, versioning components, and debugging interactions between parts that each look fine alone. For a single use case, it is engineering effort spent on flexibility you may never use.

    Say it in the interview. “Modular RAG treats retrieval as composable services rather than a fixed pipeline. I reach for it when the system serves multiple use cases or sources — and I am honest that for one use case, it is over-engineering.”

    4. Hybrid RAG — meaning and exact words, together

    How it works. Run two retrievals in parallel: dense retrieval (embeddings) for meaning, and sparse retrieval (BM25) for exact keyword match. Merge the two result lists — typically with a fusion technique like Reciprocal Rank Fusion — then rerank the merged set and generate as usual.
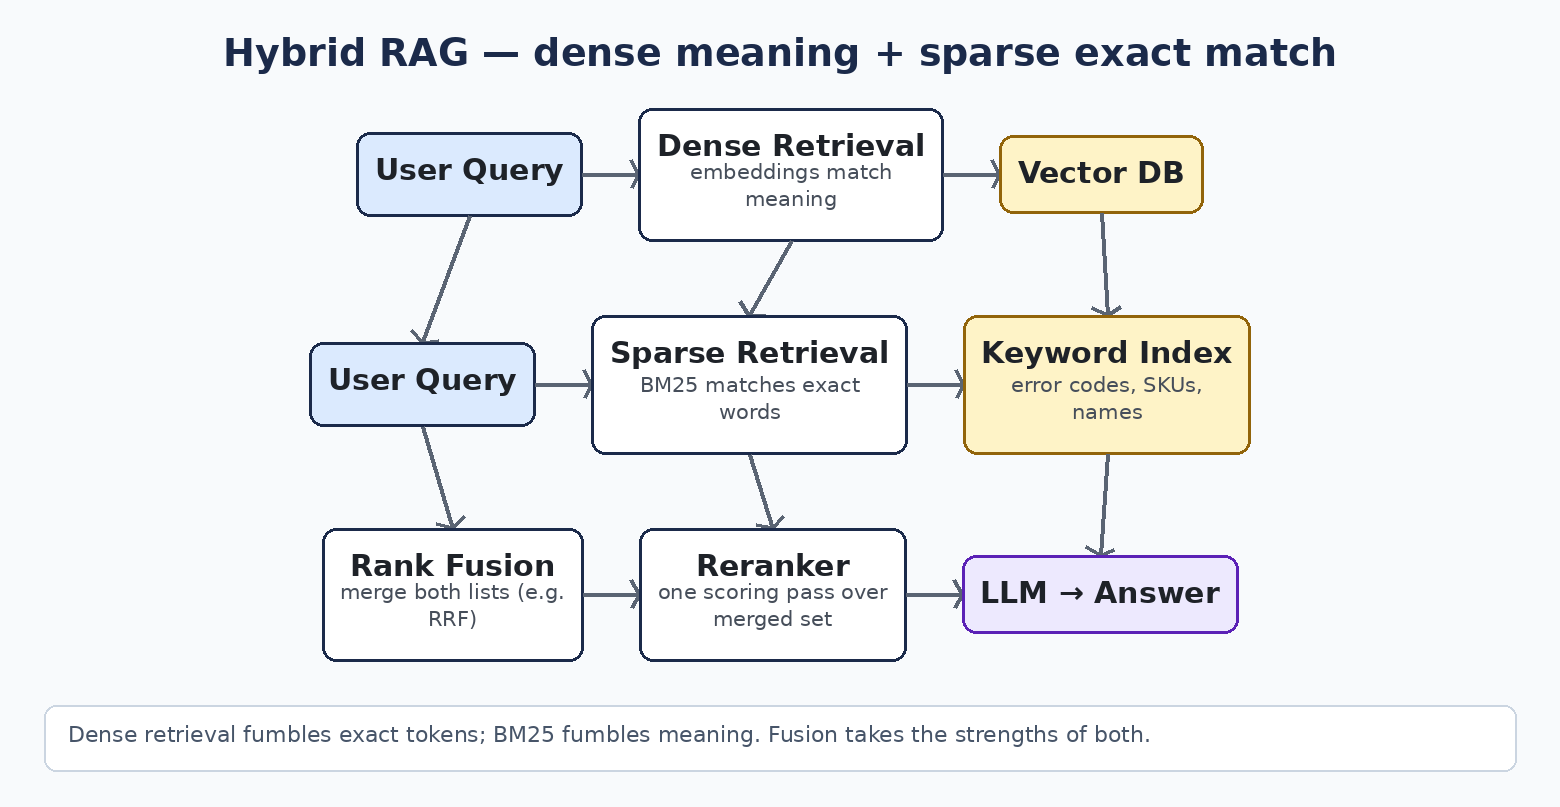
    Hybrid RAG diagram

    When it earns its place. Anywhere exact strings carry meaning: error codes, product IDs, drug names, legal clauses, ticker symbols. Semantic search is famously blind here — an embedding will happily return text about a similar error code. BM25 will not. Real enterprise corpora are full of such strings, which is why hybrid is the quiet default in serious production systems.

    Where it breaks. Two indexes to build, keep in sync, and tune. The fusion weighting between dense and sparse results is corpus-dependent, and the merged candidate set is bigger, so reranking cost rises.

    Say it in the interview. “Embeddings match meaning but fumble exact tokens — SKUs, error codes, names. BM25 is the opposite. Hybrid retrieval runs both and fuses the rankings, and in enterprise data, where exact identifiers matter, it is usually my production default.”

    5. Graph RAG — when the answer lives in the relationships

    How it works. Instead of (or alongside) chunking text, you extract entities and their relationships into a knowledge graph. A question is answered by identifying the entities it mentions and traversing the graph — following relationships across nodes — then handing the connected subgraph to the model as context.
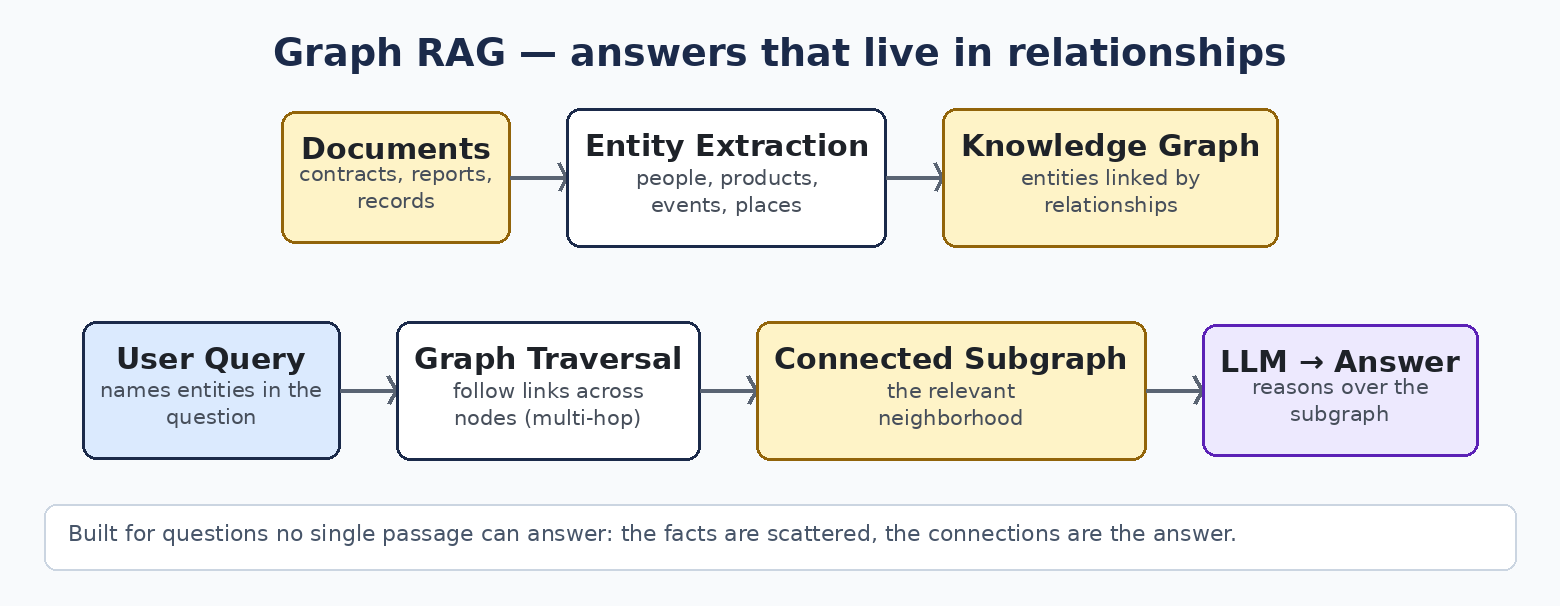
    Graph RAG diagram

    When it earns its place. Multi-hop questions: “Which suppliers provide components for the products that failed inspection last quarter?” No single document contains that answer; it exists only in the connections. Also for thematic questions over a whole corpus — “what are the main risk themes across these 500 reports?” — where chunk retrieval returns fragments but a graph can summarize structure.

    Where it breaks. Somebody has to build and maintain the graph. Entity extraction is imperfect, relationships drift as data changes, and graph construction over a large corpus is a project in itself. If your questions are simple lookups, you have bought a very expensive way to avoid a vector search.

    Say it in the interview. “Graph RAG answers questions whose answers live in relationships, not in any single passage. The cost is graph construction and upkeep, so I justify it with genuinely multi-hop questions — and I can point to the queries that chunk retrieval structurally cannot answer.”

    6. Agentic RAG — retrieval that thinks in loops

    How it works. An AI agent — typically with a planning step — decides what to retrieve, from where, and whether it has enough. It can search documents, query a vector store, call web search, hit APIs, or run SQL, then reason about the results and loop: refine, search again, or answer. Retrieval stops being a single function call and becomes a decision process.
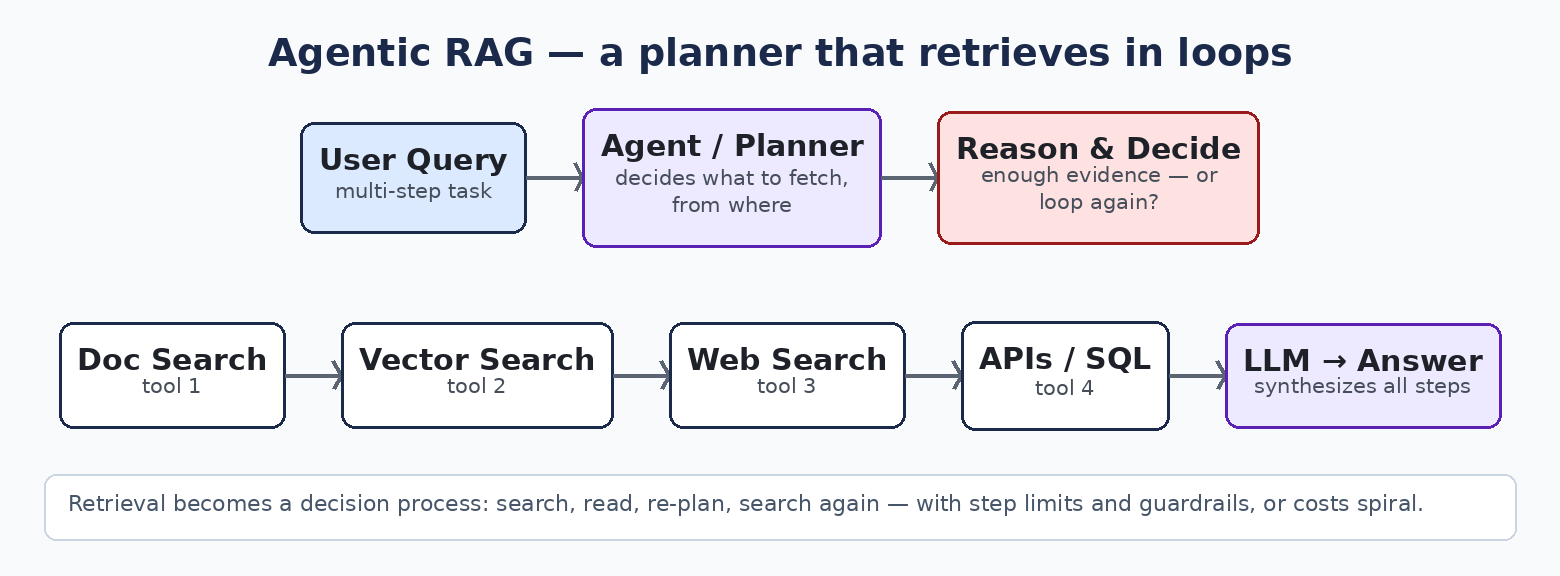
    Agentic RAG diagram

    When it earns its place. Questions that need multiple steps and multiple sources: research tasks, investigations, anything where step two depends on what step one found. Also when the right source varies by question — no fixed pipeline can route as flexibly as an agent that reads the question and chooses.

    Where it breaks. Everything compounds: latency (each loop is model calls), cost (same), and evaluation complexity (the path differs every run, so “why did it fail” becomes a forensic question). Agents also fail in agent ways — loops that never converge, tools called with malformed inputs, confident plans built on a misread first result. Guardrails and step limits are not optional.

    Say it in the interview. “Agentic RAG replaces the fixed pipeline with a planner that chooses sources and iterates. It is the most capable pattern and the most expensive to run and evaluate, so I use it when the task genuinely requires multi-step reasoning over multiple sources — not as a default.”

    7. Corrective RAG (CRAG) — retrieval that grades itself

    How it works. After retrieval, a lightweight evaluator scores the retrieved material for relevance before generation. Good context goes straight to the model. Poor context triggers corrective action — the query is refined and retrieval runs again, possibly against an alternative source such as web search. The system checks its own homework before answering. (From the CRAG paper, Yan et al., 2024.)
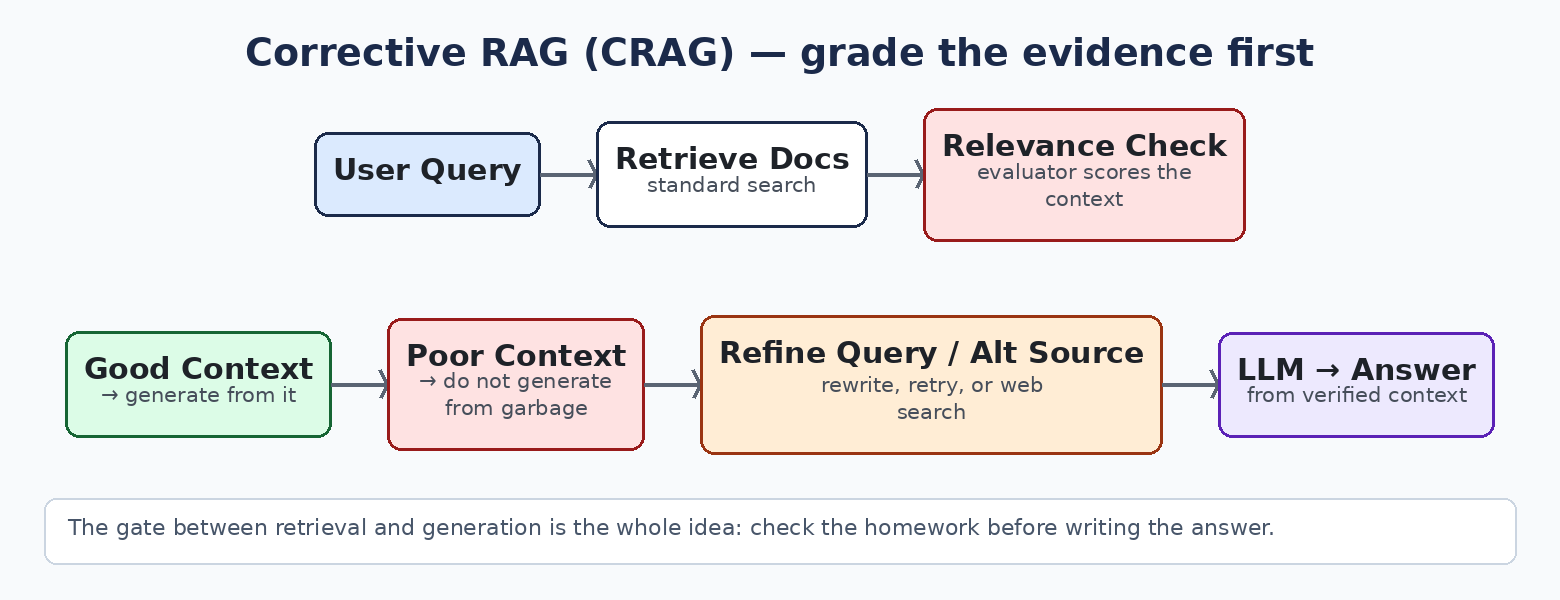
    Corrective RAG diagram

    When it earns its place. When retrieval quality varies — mixed corpora, uneven document quality, questions that sometimes fall outside the knowledge base entirely. Also anywhere a wrong answer is expensive: if the context is bad, CRAG’s fallback beats generating from garbage and hoping.

    Where it breaks. The evaluator is itself a model with errors; a relevance check that wrongly rejects good context adds cost and latency for nothing. The fallback path (web search, say) introduces its own trust questions. More components, more evaluation logic to validate.

    Say it in the interview. “CRAG adds a relevance gate between retrieval and generation: score the context, and if it is poor, correct — rewrite the query, try another source — instead of generating from bad evidence. It is the pattern I choose when retrieval quality is uneven and wrong answers are costly.”

    8. Self-RAG — the model decides whether to retrieve, then grades its own answer

    How it works. Self-RAG (Asai et al., 2023) trains the model itself to control the process. The model first decides whether retrieval is even needed for this question. If it retrieves, it generates while critiquing its own output with special “reflection tokens” — judging whether passages support the answer and whether the answer is useful — and can retrieve again if its confidence is low.
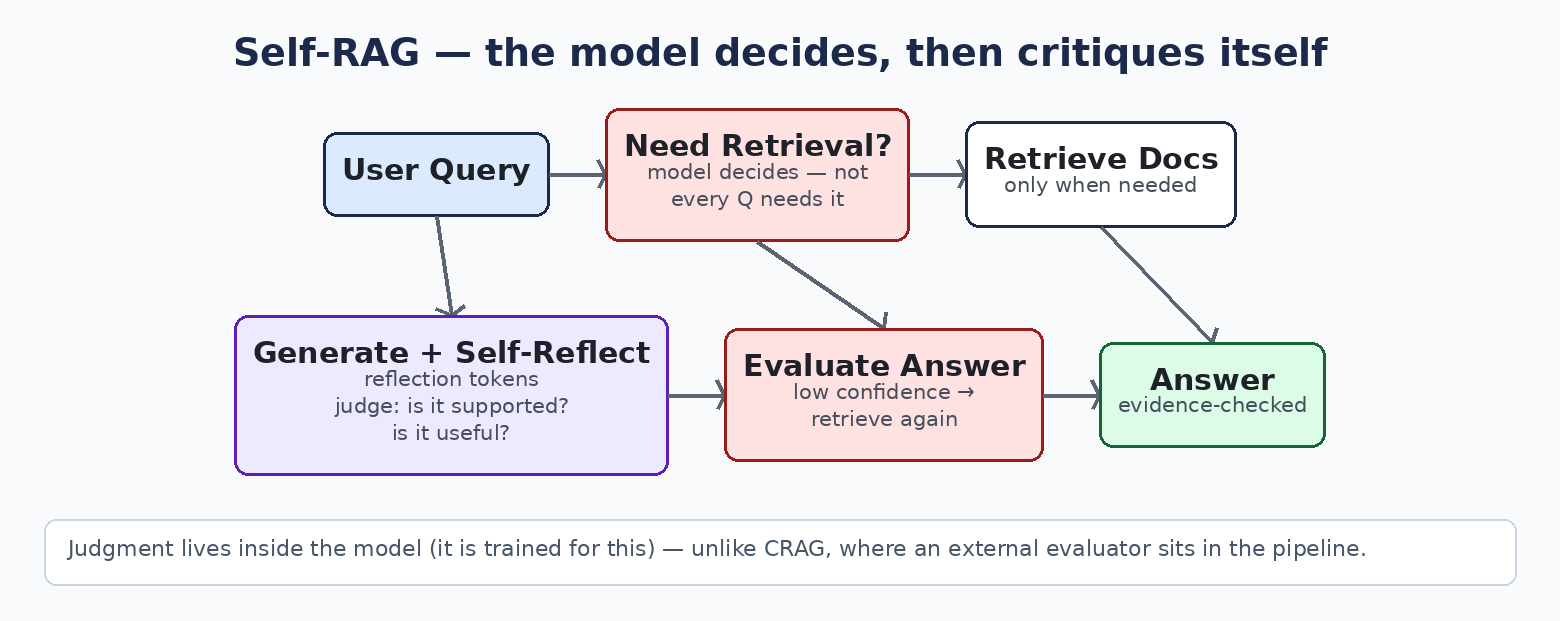
    Self-RAG diagram

    When it earns its place. Mixed workloads: many questions the model can answer from its own knowledge, some that demand evidence. Retrieving for every question wastes cost and can actively hurt — irrelevant context drags good answers down. Self-RAG also shines where you want evidence-grounded generation with explicit self-checking built in, rather than bolted on.

    Where it breaks. It requires a model trained (or fine-tuned) for the reflection-token scheme — you cannot bolt Self-RAG onto an arbitrary off-the-shelf model the way you can with CRAG. The extra critique steps cost tokens and time, and the quality of the whole loop depends on that specialized training.

    Say it in the interview. “Self-RAG puts the control inside the model: it learns when to retrieve and how to critique its own generations using reflection tokens. The distinction from CRAG is where the judgment lives — in the model’s training versus an external evaluator in the pipeline.”

    9. Long-Context RAG — when the window got big enough to skip the funnel

    How it works. Modern models accept enormous inputs — 128K tokens and well beyond. Long-context RAG retrieves generously (large sections, or entire documents) and lets the model’s attention do the fine-grained work that chunking and reranking used to do. The retrieval funnel gets wider and shallower.
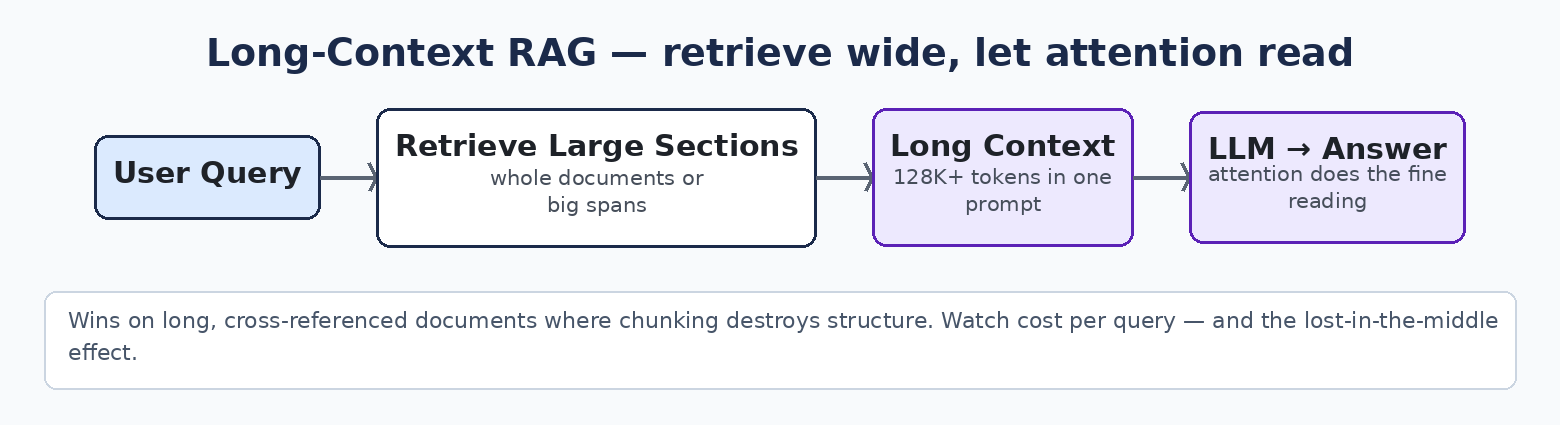
    Long-context RAG diagram

    When it earns its place. Long, interconnected documents where answers span sections — contracts, clinical guidelines, regulatory filings — and chunking destroys exactly the cross-references that matter. Also small-to-medium corpora where “just put the relevant documents in the prompt” is honestly feasible.

    Where it breaks. Inference cost scales with input, and a fat context on every query gets expensive fast. And a hard truth from practice: more context is not automatically better accuracy. Models can lose material in the middle of very long inputs, and irrelevant bulk dilutes attention. Retrieval still earns its keep as a cost and focus mechanism — long context changes the trade-off, it does not repeal it.

    Say it in the interview. “Long-context models let me retrieve coarsely and let attention do the fine work. It wins on interconnected documents, but I watch cost per query and the lost-in-the-middle effect — bigger context is a trade-off, not a free upgrade.”


    The decision guide

    Start from the problem, not the pattern:

    Your situationStart withBecause
    Simple document Q&A, small corpus, proving valueNaive RAGFastest path to a working baseline
    Retrieval returns almost-right passagesAdvanced RAGRewriting + reranking fix the ranking, cheaply
    Exact codes, IDs, names matter alongside meaningHybrid RAGDense misses exact tokens; BM25 misses meaning; you need both
    Questions connect entities across documentsGraph RAGThe answer is in the relationships, not any single passage
    Multi-step questions spanning several sources/toolsAgentic RAGA planner can route and iterate; a fixed pipeline cannot
    Retrieval quality is uneven; wrong answers are expensiveCorrective RAGGrade the evidence before you generate from it
    Mixed workload; many questions need no retrievalSelf-RAGThe model learns when retrieval helps and when it hurts
    Long, cross-referenced documents; modest corpusLong-Context RAGChunking destroys the structure the answers depend on
    Multiple use cases on one platformModular RAGComposable parts beat one pipeline per use case

    And the sentence that ties it together, in any interview room: these patterns compose. A production system might be modular in structure, hybrid in retrieval, corrective at the gate, and agentic for its hardest query class. The nine types are a vocabulary for decisions, not a multiple-choice question with one right answer.

    FAQs

    Q: Is RAG better than fine-tuning?

    They solve different problems. Fine-tuning changes how the model behaves — tone, format, task skill. RAG changes what the model knows at answer time. If your problem is “the model doesn’t know our current data,” that is RAG. If it is “the model doesn’t follow our format,” that is fine-tuning. Serious systems often use both, and reaching for fine-tuning to inject facts is the classic beginner mistake — facts change, and retraining is a slow way to update them.

    Q: What chunk size should I use?

    There is no universal number, which is exactly why interviewers ask. Reasonable defaults are a few hundred tokens with some overlap between chunks, but the honest answer is: it depends on the document structure and the questions, and you decide by evaluating retrieval quality on real queries, not by folklore. Structure-aware chunking (splitting on headings, keeping tables intact) usually beats any magic number.

    Q: How do I know if my RAG system is actually good?

    Evaluate the two halves separately. Retrieval: are the right chunks coming back (recall and ranking quality against a set of real questions with known answers)? Generation: is the answer faithful to the retrieved context, and does it actually address the question? Teams that only eyeball final answers cannot tell which half is failing — and it is usually retrieval.

    Q: Vector database — which one should I pick?

    For most teams, the honest answer is: the one that fits your existing stack and scale, because at moderate scale they are more alike than different. The decision matters more at very large scale, with heavy metadata filtering, or with hybrid search requirements. In an interview, talk about the criteria — scale, filtering, hybrid support, operational burden — not brand loyalty.

    Q: Doesn’t long context make RAG obsolete?

    No — it reprices it. Stuffing everything into the prompt costs more per query, slows responses, and can reduce accuracy when relevant material sits buried mid-context. Retrieval remains how you control cost and focus attention. What long context changes is granularity: you can retrieve documents instead of fragments and let the model read widely within a selected set.

    Q: When should I NOT use RAG at all?

    When the knowledge is tiny and static (put it in the prompt), when the task needs no external facts (pure reasoning or transformation), and when the real problem is structured transactions — if the user needs the current account balance, that is a database query or a tool call, not a document search.

    Q: How do I stop a RAG system from answering questions it has no evidence for?

    Teach it to abstain. Instruct the model to answer only from context and to say so when the context is insufficient, evaluate faithfulness, and consider a corrective pattern (CRAG) that detects poor retrieval before generation. A system that says “I don’t have that in the knowledge base” is worth ten that improvise.

    Q: What’s the difference between CRAG and Self-RAG?

    Where the judgment lives. CRAG puts an external evaluator in the pipeline — any model can sit behind it. Self-RAG builds the judgment into the model itself through training with reflection tokens. CRAG is easier to adopt; Self-RAG is more integrated but requires the specialized model.

    Interview rapid-fire

    “Walk me through how you’d design a RAG system for [our documents].”

    Start with the naive baseline and say so. Then ask (or state assumptions) about corpus size, question types, exact-match needs, and cost of a wrong answer — and let those answers pull in advanced, hybrid, or corrective patterns one at a time, naming the failure each addition fixes. This structure — baseline, then failure-driven upgrades — is the strongest signal you can send.

    “Our RAG system hallucinates. What do you check first?”

    Whether the retrieved context contained the answer at all. Most “hallucination” in RAG is retrieval failure followed by the model filling the gap. Check retrieval quality on the failing questions before touching prompts or models.

    “Why not just use a bigger model?”

    A bigger model reasons better over the context it is given; it does not fix being given the wrong context, and it multiplies cost across every query. Architecture first, model size second.

    “How would you cut our RAG costs?”

    Retrieve less but better (reranking lets you shrink Top-K), cache frequent queries and embeddings, route simple questions to smaller models, and reserve agentic or long-context patterns for the query classes that demonstrably need them.

    The one-sentence version

    RAG is not a product you install; it is a set of decisions about how evidence reaches the model — and the right architecture is the simplest one whose failure modes you have actually observed and priced.

    Start simple. Measure. Add exactly the complexity your failures demand. That sentence will carry you through most interviews — and, not coincidentally, most production systems too.

    If this helped, subscribe to The Agentic Enterprise below — one practical AI architecture breakdown a month, written from production experience, no hype. And if you are preparing for interviews, the free GenAI Interview Question Bank on the Free Toolkits page goes deeper.

  • Have You Ever Thought About Vibe Coding Your Own Database Engine?

    DATABASE ENGINEERING   /   AI-ASSISTED DEVELOPMENT

    From a college project written in C to architecting a relational database engine with AI.

    Jugal Shah   |   Database & AI Architect   |   aiDeeva

    What if you could build your own database engine?

    During my college days, I built a simple invoice management system using C, linked lists, and doubly linked lists. It allowed users to add, delete, update, and retrieve invoice records.

    At the time, implementing these basic data operations from scratch was an exciting engineering challenge. I had to think about how records were organized, how memory was managed, and how different operations interacted with the underlying data structures.

    Looking back, that project sparked my curiosity about how database systems work internally.

    THEN VS. NOW

    💻

    College Days

    C programming, linked lists, manual memory management, and basic record operations.

    🤖

    Today

    AI coding agents, modern programming languages, and the opportunity to explore complete database architectures.

    Fast-forward to today.

    We now have AI coding assistants capable of generating code, explaining complex algorithms, helping design software architectures, and accelerating development in ways that were difficult to imagine during my college days.

    And that got me thinking:

    “If I could build a basic invoice management system using C and linked lists back then, what could I build today with modern programming languages, database engineering principles, and AI as my engineering copilot?”

    Could I build my own relational database engine?

    Not another application running on PostgreSQL or SQLite.

    An actual database engine that manages its own storage, processes SQL queries, maintains indexes, handles transactions, and recovers from failures.

    That’s the engineering challenge I want to explore through aiDeeva.

    01. What Does It Really Take to Build a Database Engine?

    When most developers think about a database, they think about SQL.

    Consider a simple example:

    CREATE TABLE customers (
        customer_id INTEGER PRIMARY KEY,
        customer_name VARCHAR(100),
        email VARCHAR(255)
    );
    
    INSERT INTO customers
    VALUES (
        1,
        'Jugal',
        'jugal@example.com'
    );
    
    SELECT *
    FROM customers
    WHERE customer_id = 1;

    Three simple SQL statements.

    But behind those statements is an entire execution infrastructure.

    When you execute an INSERT, the database must validate the statement, locate the table, identify the appropriate storage pages, write the record, update indexes, and maintain transactional consistency.

    When you execute a SELECT, the database must parse the SQL, resolve table and column references, determine an execution strategy, retrieve data, and return the result.

    And when the system crashes, the database must recover without losing acknowledged committed transactions.

    These are not simply programming tasks. They are architectural responsibilities.

    Inside a Relational Database Engine

    APPLICATIONS & SQL CLIENTS
    SQL Queries · Connections · Result Sets
    ↓
    SQL QUERY ENGINE
    Parser → Binder → Planner → Executor
    ↓

    DATABASE KERNEL

    Transaction Manager
    Buffer Pool Manager
    Index Manager
    Catalog Manager
    ↓
    STORAGE ENGINE
    Pages · Records · Files
    RECOVERY ENGINE
    WAL · Checkpoints
    ↓
    PERSISTENT STORAGE
    Data Files · Index Files · Transaction Logs

    Conceptual single-node database architecture. Transaction, storage, buffer, and recovery components cooperate across subsystem boundaries.

    Our goal is to build these components incrementally, using AI to accelerate implementation while retaining architectural control.

    02. Introducing aiDeevaDB: Our Database Engineering Experiment

    Before writing code, we need to define what we are actually building.

    For this engineering experiment, let’s call our database aiDeevaDB.

    CONCEPTUAL ENGINEERING PROJECT

    aiDeevaDB

    An AI-assisted, single-node SQL relational database built from first principles.

    Initial Design Objectives

    • Persistent row-oriented storage
    • A defined subset of SQL
    • B+ Tree indexing
    • Transaction processing and crash recovery
    • A basic query planner and executor
    • Single-node deployment

    Why start with a single-node database?

    Because distribution introduces an entirely different category of engineering challenges.

    Before solving consensus, replication, and distributed transaction coordination, we need to demonstrate that our database can reliably store and retrieve information on one machine.

    Our initial success criterion is straightforward:

    Create a table, insert records, restart the database, execute queries, and verify that committed data remains consistent.

    Then progressively introduce indexing, concurrent transactions, recovery, and query optimization.

    03. The Engineering Roadmap: Seven Stages to a Relational Database

    Building a database should be treated as a sequence of engineering milestones, not a single enormous AI prompt.

    The aiDeevaDB Development Roadmap

    STAGE 01

    Storage Foundation

    Build a disk manager, fixed-size pages, record layouts, and persistent table storage.

    Milestone: Records survive a database restart.

    STAGE 02

    Memory Management

    Introduce a buffer pool, page pinning, dirty-page tracking, and a replacement policy.

    Milestone: Frequently accessed pages are cached safely.

    STAGE 03

    Indexes and Access Paths

    Implement persistent B+ Tree indexes, node splits, point lookups, and range scans.

    Milestone: Queries can locate records without scanning every page.

    STAGE 04

    SQL Processing

    Build a SQL parser, catalog, binder, logical planner, and execution operators.

    Milestone: The engine accepts a defined subset of SQL.

    STAGE 05

    Transactions and Concurrency

    Implement transaction lifecycle management, isolation, locking, and rollback.

    Milestone: Concurrent operations preserve defined consistency guarantees.

    STAGE 06

    Durability and Recovery

    Integrate write-ahead logging, commit durability, checkpoints, and crash recovery.

    Milestone: Committed transactions survive supported crash scenarios.

    STAGE 07

    Optimization and Validation

    Add statistics, plan selection, benchmarks, fault injection, and regression tests.

    Milestone: Correctness and performance are measured against explicit targets.

    The roadmap describes our learning and development sequence, not seven completely independent components.

    Storage, transactions, indexing, and recovery must eventually operate together through well-defined interfaces and protocols.

    04. Where AI Changes the Development Process

    Traditionally, building a database engine requires engineers to implement and validate each subsystem manually.

    AI coding agents introduce a different development model.

    An architect can define the subsystem, establish its interfaces, specify its invariants, and ask an AI agent to propose an implementation.

    AI can generate code, write tests, explain design alternatives, and help investigate failures.

    However, AI-generated code is not automatically correct, particularly in low-level systems where subtle concurrency or durability defects may only appear under unusual conditions.

    The architect remains responsible for the system’s guarantees.

    The AI-Assisted Engineering Loop

    1. ARCHITECT DEFINES THE CONTRACT
    Requirements · Interfaces · Invariants
    ↓
    2. AI GENERATES IMPLEMENTATION
    Code · Unit Tests · Documentation
    ↓
    3. ENGINEERING VALIDATION
    Correctness · Concurrency · Failure Testing
    ↓
    4. REVIEW AND REFINE
    Fix Defects · Revisit Assumptions · Optimize

    ↻ Repeat until the acceptance criteria pass.

    An Example: Building the Buffer Pool Manager

    A generic prompt might say:

    “Build a database cache that stores 100 pages in memory.”

    An architectural prompt should go further.

    AI ENGINEERING PROMPT

    Build a buffer pool manager for a single-node relational database.

    Implement a fixed-capacity page cache with page identifiers, pin counts, dirty-page tracking, and an LRU replacement policy.

    Define how concurrent requests access cached pages and how the manager coordinates with persistent storage.

    Ensure that pinned pages cannot be evicted and that dirty-page flushing respects the write-ahead logging durability protocol once recovery support is integrated.

    Generate unit tests for page loading, eviction, concurrent access, and I/O failures.

    The difference is not simply a longer prompt.

    It is the explicit definition of system behavior, failure conditions, and correctness requirements.

    That is where architectural expertise becomes essential.

    05. The Real Challenge: A Database Must Be Correct When Things Go Wrong

    A database that successfully executes SQL under normal conditions is only the beginning.

    What happens if the application crashes halfway through a transaction?

    What happens when two transactions update the same record?

    What happens when an index node splits while another operation is reading the index?

    What happens when a storage write fails?

    These questions separate a database demonstration from a reliable database system.

    The Four ACID Guarantees

    A — Atomicity

    A transaction either commits its intended changes or has no lasting effect.

    C — Consistency

    Transactions preserve the database’s defined integrity constraints and invariants.

    I — Isolation

    Concurrent transactions interact according to the database’s documented isolation guarantees.

    D — Durability

    Acknowledged committed transactions survive failures within the database’s stated durability model.

    These guarantees require coordination across multiple database subsystems.

    Write-ahead logging alone does not guarantee ACID. Neither does using a memory-safe programming language.

    The complete transaction, storage, concurrency, and recovery protocols must work together.

    For aiDeevaDB, every major engineering milestone should include tests that deliberately attempt to violate the guarantees the system claims to provide.

    06. What Would a Working aiDeevaDB Actually Look Like?

    Imagine opening a terminal and connecting to the database engine we have built.

    The following is an illustrative target for our future implementation, not a demonstration of an already completed database.

    aideevadb> CREATE TABLE products (
        id INTEGER PRIMARY KEY,
        name VARCHAR(100),
        price DECIMAL(10,2)
    );
    
    OK. Table created.
    
    aideevadb> INSERT INTO products
    VALUES (101, 'AI Server', 2499.00);
    
    OK. 1 row inserted.
    
    aideevadb> SELECT id, name, price
    FROM products
    WHERE id = 101;
    
    +-----+-----------+---------+
    | id  | name      | price   |
    +-----+-----------+---------+
    | 101 | AI Server | 2499.00 |
    +-----+-----------+---------+
    
    1 row returned.

    The interface may look simple, but the system behind it is not.

    The SQL parser recognizes the statement. The catalog resolves the table and columns. The planner selects an access path. The executor retrieves the relevant record through the storage and indexing subsystems.

    The transaction manager and recovery infrastructure coordinate to maintain the database’s defined consistency and durability guarantees.

    At this point, we have more than an AI-generated script.

    We have the foundation of a relational database engine.

    07. Where This Journey Could Lead: AI-Native Database Engineering

    Building a database from scratch is an engineering challenge in its own right.

    But the longer-term opportunity is exploring how AI can improve the way database systems are developed, operated, and optimized.

    Imagine an AI-assisted database engineering platform that can examine query workloads, analyze execution plans, recommend indexing strategies, investigate performance regressions, and propose storage optimizations.

    A Possible AI-Native Database Architecture

    APPLICATIONS & SQL WORKLOADS
    ↓
    RELATIONAL DATABASE ENGINE
    SQL · Transactions · Storage · Recovery
    ↕
    OBSERVABILITY & WORKLOAD INTELLIGENCE
    Query Plans · Statistics · Latency · Resource Metrics
    ↕
    AI ENGINEERING & OPTIMIZATION LAYER
    Workload Analysis · Recommendations · Diagnostics
    ↓
    VALIDATION & CONTROLLED EXECUTION
    Policy Checks · Benchmarks · Human Approval · Rollback

    Conceptual AI-native extension of aiDeevaDB. AI proposes improvements while deterministic database components retain responsibility for execution and correctness.

    This is an important distinction.

    An LLM should not be responsible for deciding whether a transaction is committed or whether a storage page is durable.

    Those decisions belong to deterministic, verifiable database protocols.

    AI can instead assist with higher-level analysis, engineering recommendations, and optimization workflows.

    That separation allows us to explore AI-native database capabilities without abandoning the reliability principles that database systems depend on.

    08. Can You Really Build a Database Engine With Vibe Coding?

    Yes, AI-assisted development can help you build an educational database engine from scratch.

    But there is a significant difference between generating a functional prototype and engineering a database that can safely support production workloads.

    A prototype can demonstrate storage, SQL execution, and indexing with a limited feature set.

    A production database requires considerably more work: comprehensive failure handling, concurrency correctness, recovery validation, operational tooling, security, performance engineering, and sustained testing.

    AI can accelerate parts of that work.

    It does not eliminate the need for database engineering expertise.

    The real opportunity is not replacing database engineers with prompts. It is enabling engineers to explore more ambitious architectures, validate ideas faster, and spend more time on the design decisions that matter.

    Final Thoughts

    We are entering a period where AI-assisted development makes complex systems engineering more accessible.

    Database engines, compilers, operating systems, and distributed platforms are no longer projects that engineers must approach entirely through manual implementation.

    But accessibility should not be confused with simplicity.

    The real engineering challenge is not getting AI to generate thousands of lines of code.

    It is designing a system whose components work together correctly, defining the guarantees it must uphold, and validating those guarantees under realistic operating conditions.

    That is the journey I want to explore through aiDeevaDB.

    From the first persistent storage page to a functioning SQL engine, and eventually toward AI-assisted database optimization.

    The question is no longer just whether AI can help us write a database engine. It is how we can use AI to build better database systems while preserving the engineering discipline that makes them trustworthy.

    COMING NEXT ON AIDEEVA

    What Happens When a Database Writes a Record to Disk?

    In the next article, we’ll explore database page layouts, row storage, record identifiers, buffer pools, and how to begin implementing a persistent storage engine with AI-assisted development.

    ABOUT THE AUTHOR

    Jugal Shah

    Database & AI Architect | aiDeeva

    Jugal Shah works across enterprise database modernization, cloud data platforms, and AI architecture. His experience includes PostgreSQL, SQL Server, Teradata, Snowflake, Amazon Redshift, and Databricks.

    Through aiDeeva, he explores the intersection of database engineering, enterprise architecture, and AI-assisted software development.

    Interested in database engine development, enterprise database modernization, or AI-native data infrastructure? Connect with Jugal to discuss architecture, engineering, and collaboration opportunities.

  • Beyond the AI Hype: The 3 Breakthroughs Needed to Reach Next-Gen Intelligence

    Every week, the tech world gets flooded with headlines about new model releases, benchmark scores, and trillion-parameter claims. But if you look past the marketing noise, a deeper question emerges: What is actually holding AI back from making its next giant leap?

    If we want AI systems that don’t just chat, but actively solve massive real-world problems—like discovering new materials, writing complex software from scratch, or solving open scientific challenges—scaling up today’s technology isn’t enough.

    Here are the three big engineering shifts that will define the next decade of artificial intelligence.

    1. Smarter Computing: Doing More with Less Energy

    Building massive AI models is becoming insanely expensive. Training a single frontier model can take tens of millions of dollars and enough electricity to power a small city.

    To solve this, researchers are turning to an architecture called Mixture-of-Experts (MoE).

    Think of a traditional AI model like a single, massive dictionary where every single page gets flipped every time you ask a question. An MoE model works more like a hospital: instead of forcing every doctor to examine every patient, a central “router” directs your question straight to the exact specialist needed.

    Why this matters: By only activating a small “specialist” fraction of the brain per request, we get ultra-smart responses at a fraction of the energy cost. The future isn’t just about bigger models—it’s about radically more efficient routing.

    2. Dynamic Memory: Fixing AI’s Short-Term Attention Span

    Have you ever noticed that an AI chat gets confused or forgets instructions during long conversations? That happens because today’s models process information using a method that gets exponentially slower and more memory-heavy the more text you give it.

    Right now, an AI has to re-read its entire conversation history every single time it generates a new word.

    To fix this, engineers are building new hybrid memory systems. Instead of re-reading everything from scratch, future models will continuously condense key facts into an active “working memory”—much like how human brains store useful context while letting background noise fade away.

    Why this matters: This will allow AI agents to work alongside us for days or weeks on complex projects without slowing down, hallucinating, or forgetting past decisions.

    3. Self-Verification: Teaching AI to Double-Check Its Own Work

    Today’s AI operates on instant prediction: it guesses the very next word based on probability. But real human thinking doesn’t work that way. When a doctor diagnoses an illness or a engineer designs a bridge, they don’t just speak the first thought that pops into their head—they test their ideas, look for flaws, and correct their mistakes before making a decision.

    The next big shift is internal self-verification.

    Instead of spitting out an instant answer, future AI models will:

    1. Brainstorm multiple possible paths to a solution.
    2. Check each step against a logic compiler or code tester.
    3. Automatically backtrack and try a different route if it detects an error.

    Jargon Buster: Frequently Asked Questions

    If you’re new to the deeper technical side of AI, here is a quick breakdown of terms you’ll hear often:

    What is a “Parameter”?

    Think of parameters as the “knobs” or “connections” inside an AI’s brain. The more parameters a model has, the more capacity it has to learn complex patterns. A 1-trillion parameter model has 1 trillion internal connections tuned during training.

    What is a “Mixture-of-Experts” (MoE)?

    An AI design technique where a giant model is broken into multiple smaller sub-networks (“experts”). A smart router sends your query only to the relevant experts, saving huge amounts of computing power.

    What is a “Hallucination”?

    When an AI model confidently presents false, fabricated, or illogical information as absolute fact. This happens because the model is predicting words based on language patterns rather than verifying actual ground truth.

    What is “Self-Verification”?

    A setup where an AI model uses external tools (like code interpreters, math checkers, or internal scoring models) to double-check its own logic step-by-step before showing you the final output.

  • What Is a Graph Database—and Why Does It Matter in the Age of AI?

    From Connected Data to Intelligent Action — Part 1

    Enterprises do not suffer from a shortage of data. They suffer from a shortage of connected understanding.

    Customer information may live in a CRM. Product information may be stored in an ERP system. Contracts may exist as documents. Operational events may arrive through streaming platforms. Application metadata, infrastructure dependencies, security policies and support incidents may all reside in different systems.

    Each system may work correctly on its own. The real difficulty begins when we need to understand how everything is connected.

    Consider a seemingly simple question:

    If this database cluster fails, which applications, business services and customers will be affected?

    Answering it may require connecting information across several systems:

    Database Cluster → Database → Application → Business Service → Customer

    A traditional database can store all these records. However, following a large and constantly changing network of relationships can require many joins, mapping tables and complex queries.

    This is the type of problem a graph database is designed to address.

    What is a graph database?

    A graph database stores and queries data based on relationships.

    Instead of viewing information primarily as rows and columns, it represents the world using three basic elements:

    • Nodes represent entities such as people, customers, applications, devices or products.
    • Relationships describe how those entities are connected.
    • Properties provide additional information about nodes and relationships.

    Imagine a professional network:

    (Jugal)-[:HAS_SKILL]->(Artificial Intelligence)
    (Jugal)-[:WORKS_FOR]->(Company A)
    (Company A)-[:SERVES]->(Customer B)
    (Customer B)-[:USES]->(AWS)

    In this model:

    • Jugal, Company A, Customer B and AWS are nodes.
    • HAS_SKILL, WORKS_FOR, SERVES and USES are relationships.
    • Each node or relationship can contain properties such as role, location, experience level or start date.

    The graph does more than store individual facts. It preserves the paths that connect those facts.

    That distinction becomes important when the business question is not just, “What information do we have?” but also, “How is this information related?”

    A familiar example: LinkedIn

    LinkedIn is a natural way to understand graphs.

    A relational view might contain separate tables for:

    • People
    • Companies
    • Employment
    • Skills
    • Education
    • Connections

    To discover how two people are connected, a relational database may need to join several tables repeatedly.

    A graph model represents those connections directly:

    Person → WORKS_AT → Company
    Person → HAS_SKILL → Skill
    Person → KNOWS → Person
    Person → STUDIED_AT → University

    Now we can ask relationship-oriented questions:

    • Who in my network works at a particular company?
    • Which people have both cloud and artificial intelligence experience?
    • How am I connected to a specific technology leader?
    • Which skills are common among people holding a particular role?
    • Who can introduce me to someone in a target organization?

    The relationships are not reconstructed only when the query runs. They are fundamental parts of the data model.

    Graph database versus relational database

    Relational databases remain essential. They are mature, reliable and exceptionally good for structured transactions, financial records, order processing and many reporting workloads.

    Graph databases are not intended to replace them everywhere.

    The difference is primarily about the nature of the question.

    Relational databaseGraph database
    Organizes data into tablesOrganizes data into nodes and relationships
    Uses primary and foreign keysStores relationships directly
    Commonly uses SQLOften uses Cypher, Gremlin or SPARQL
    Excellent for structured transactionsExcellent for connected-data exploration
    Joins connect records during a queryTraversals follow stored relationships
    Best when the record is centralBest when the connection is central

    Suppose we need to retrieve a customer using a customer ID. A relational database is an excellent choice.

    Now suppose we need to determine every infrastructure component, application, business capability, contract and customer connected to a failed network device within five levels of dependency. That is naturally a graph problem.

    The correct architectural question is therefore not:

    “Are graph databases better than relational databases?”

    It is:

    “Does the business problem depend heavily on navigating relationships?”

    How graph traversal works

    A graph query begins with one or more nodes and follows relationships to find connected information. This process is called traversal.

    For example, imagine the following enterprise dependencies:

    Router-101
    → SUPPORTS → Network Service
    → USED_BY → Customer Application
    → SUPPORTS → Business Process
    → SERVES → Customer

    If Router-101 fails, a graph traversal can follow these relationships to calculate the potential business impact.

    In Neo4j’s Cypher query language, a simplified query could look like this:

    MATCH path =
    (device:Device {name: "Router-101"})
    -[:SUPPORTS|USED_BY*1..5]->
    (customer:Customer)
    RETURN path

    The query starts from a device and follows selected relationships through as many as five levels to find affected customers.

    The important point is not the syntax. It is the way the query expresses the question. It describes a pattern of relationships that closely resembles how a person explains the business problem.

    Why graph databases can traverse relationships efficiently

    In a traditional relational model, relationships are generally represented through matching key values. The database uses joins and indexes to connect related records.

    Native graph databases can store relationships as direct connections between records. This design is commonly associated with index-free adjacency.

    In simple terms, once the database finds a node, it can follow its connections without repeatedly searching the entire dataset to rediscover every relationship.

    This can be especially valuable for:

    • Deep dependency analysis
    • Multi-hop queries
    • Shortest-path calculations
    • Highly interconnected datasets
    • Frequently changing relationships

    However, “graph” does not automatically mean “faster.”

    Performance still depends on:

    • The graph data model
    • Query design
    • Starting-node selectivity
    • Indexes and constraints
    • Relationship direction
    • Number of traversed paths
    • Data distribution
    • Whether the graph is centralized or distributed

    An architect must evaluate the complete workload rather than selecting a graph database simply because the data contains relationships. Almost every database contains relationships; graph technology becomes valuable when traversing those relationships is central to the workload.

    Where graph databases create business value

    1. Fraud detection

    Fraud is rarely visible in one transaction.

    The suspicious pattern may appear only after connecting:

    Account → Device → IP Address → Transaction → Merchant

    Several accounts may share a device, address, telephone number or payment instrument. A graph can reveal hidden rings that are difficult to recognize when each transaction is evaluated independently.

    2. Recommendation engines

    A recommendation can be generated by following relationships among users, products, interests and behavior:

    Customer → PURCHASED → Product
    Customer → VIEWED → Product
    Product → BELONGS_TO → Category

    The system can recommend products based on patterns across connected customers and items.

    3. Identity and access management

    Enterprise access is often inherited through complicated relationships:

    Employee → MEMBER_OF → Group
    Group → HAS_ROLE → Role
    Role → CAN_ACCESS → Application

    A graph can help answer:

    • Why does this user have access?
    • Which permissions were inherited?
    • What would be affected if this role were removed?
    • Are there unexpected paths to a sensitive resource?

    4. Infrastructure and data lineage

    Modern technology environments contain thousands of interconnected assets:

    Dashboard → KPI → Data Product → Table
    Table → Pipeline → Source System
    Application → Database → Cluster → Region

    Graph traversal helps teams understand upstream dependencies, downstream impact, ownership and lineage.

    5. Network and incident management

    A technical incident becomes a business problem when it affects services and customers.

    A graph can connect:

    Alert → Device → Network Service → Application
    Application → Business Capability → Customer

    This enables operations teams to move from “Which component failed?” to “What is the business impact, and what should we prioritize?”

    Graph databases and knowledge graphs are not the same

    These terms are often used interchangeably, but they describe different ideas.

    A graph database is a technology for storing and querying connected data.

    A knowledge graph uses a graph structure to represent real-world entities, business concepts and their meaning.

    A graph database might store:

    Customer A → PURCHASED → Product B

    A knowledge graph may add broader context:

    Product B → BELONGS_TO → Medical Equipment
    Medical Equipment → GOVERNED_BY → Safety Policy
    Safety Policy → APPLIES_IN → United States

    The technology stores the connections. The knowledge model helps the organization understand what those connections mean.

    This distinction becomes extremely important for generative AI.

    Why graphs matter for generative AI

    Large language models are powerful at understanding and generating language, but enterprise questions often require precise knowledge of entities and relationships.

    Imagine asking an AI assistant:

    “Which customers could be affected by the current database incident, what contractual service levels apply, and which remediation actions are permitted?”

    The answer may depend on relationships across:

    • Monitoring events
    • Infrastructure dependencies
    • Applications
    • Customer contracts
    • Service-level agreements
    • Operating procedures
    • Security policies

    Vector search can retrieve documents containing similar language. A graph can follow explicit relationships between the actual entities involved.

    These technologies are complementary:

    • Vector search helps find semantically similar information.
    • Graph traversal helps find explicitly connected information.
    • Generative AI explains the result in natural language.
    • Governance and policy controls determine what information and actions are allowed.

    This combination is one of the foundations of GraphRAG and enterprise agentic AI—but a graph alone still does not provide complete business understanding.

    For that, we need semantics and ontology.

    The architectural lesson

    The biggest value of a graph database is not its visual representation. Attractive diagrams can help people explore the data, but visualization is not the primary architectural reason to adopt graph technology.

    Its real value is the ability to treat relationships as first-class information.

    A relational database is often the right choice when transactions and individual records are the center of the workload.

    A graph database becomes compelling when the system must continuously discover:

    • What is connected?
    • How is it connected?
    • How far does the impact travel?
    • Which path explains the result?
    • What hidden pattern exists across multiple relationships?

    The decision should always begin with the business question and access pattern—not with a product preference.

    What comes next?

    Understanding graph databases gives us the foundation, but graph systems do not all represent information in the same way.

    Two important graph models are:

    • RDF — Resource Description Framework
    • LPG — Labeled Property Graph

    RDF is widely associated with semantic interoperability, knowledge graphs and ontologies. LPG is widely used for intuitive application modeling and high-performance relationship traversal.

    In the next article, I will compare RDF and LPG using the same enterprise scenario and explain how the choice affects modeling, querying, reasoning and AI architecture.

    The larger journey is only beginning:

    Connected Data → Knowledge Graph → Ontology → Generative AI → Governed Intelligent Action

    The question for technology leaders is no longer simply, “Where is our data?”

    It is:

    “Can our systems understand how that data is connected—and why those connections matter?”

  • Agentic AI Boot Camp: A Hands-On Journey

    I just finished an intensive, hands-on boot camp on agentic AI and it exceeded my expectations. Over the course of the program I moved from curiosity to practical capability — building small, testable agents, understanding safety tradeoffs, and shipping reproducible experiments. If you’re curious what a focused, project-driven AI boot camp looks like, here’s a recap you can post on your blog.

    Introduction

    • This boot camp blends foundational theory with practical labs, giving learners immediate experience deploying agentic systems. It’s ideal for fast learners who want both conceptual clarity and tangible projects to show in a portfolio.

    What we covered

    • Foundations: Core concepts in LLMs, prompt engineering, chain-of-thought reasoning, and behavior design for agents.
    • Safety & Ethics: Practical safety checks, guardrails, and how to think about misuse and mitigation strategies when agents act autonomously.
    • Data & Ingestion: Techniques for sourcing, cleaning, chunking, and deduplicating data for memory and retrieval.
    • Modeling & Fine-Tuning: When to fine-tune vs prompt-engineer, lightweight fine-tuning workflows, and evaluation best practices.
    • Agent Design & Orchestration: Composing tools, planning loops, memory strategies, and how to design agent workflows that are reliable and testable.
    • Deployment: Minimal reproducible deployments, observability basics, and integrating telemetry and metrics.

    Highlights & Projects

    • Capstone Project: Each participant built a small agent that solved a real task — for example, a PDF assistant that extracts structured answers, or an agentic pipeline that iteratively refines a draft using retrieval-augmented feedback loops.
    • Hands-on Labs: Weekly labs focused on concrete skills: creating ingestion pipelines, implementing semantic deduplication, writing evaluation suites, and automating tests for agents.
    • Safety-first Exercises: Threat modeling sessions where we enumerated possible misuse, then implemented simple mitigations (rate limits, input sanitization, and layered human-in-the-loop checks).
    • Reproducibility: Every lab included reproducible artifacts — scripts, small datasets, and automated tests — so the work can be re-run, explained in interviews, or extended later.

    Key takeaways

    • Agents are composition-first. Real capability comes from connecting models to reliable tools, data, and state (memory).
    • Small, iterated experiments beat big, brittle prototypes. Start with a minimal loop, measure, then extend.
    • Safety and evaluation are not optional. The simplest automatic behaviors can cause failure modes; build tests and monitors early.
    • Clear documentation and reproducible code make your learning visible to others — and make it easier to iterate later.

    Github Repo : https://github.com/simplyjug/AgenticAIBootCamp