Every RAG system that fails in production fails the same quiet way. The demo worked. The model was fine. Then real users arrived with real questions — misspelled product codes, questions that span four documents, questions the knowledge base simply cannot answer — and the system started producing confident, fluent, wrong answers.
Nine times out of ten, the problem is not the model. It is the architecture choice. Somebody picked the simplest possible retrieval design, shipped it, and never revisited the decision when the questions outgrew it.
That is what this guide is for. There are nine RAG architectures worth knowing. They are not nine competing products — they are nine answers to nine different failure modes. By the end, you should be able to do three things: look at a use case and pick the right type, explain why in plain language, and hold your own when an interviewer starts pushing on the trade-offs.
One rule before we start, and it is the rule every experienced builder I know follows: start with the simplest architecture that could work, and add complexity only when a specific, observed failure demands it. Every layer you add buys accuracy with latency, cost, and moving parts. Spend that budget only where the failures actually are.
First, the vocabulary (because interviews are lost here)
Most RAG explanations drown in jargon. Let us fix that first, because every architecture below is built from these same blocks.
Embedding. A piece of text converted into a list of numbers (a vector) that captures its meaning. Texts with similar meanings get similar numbers. This is how a system can know that “how do I reset my password” and “forgot my login credentials” are asking the same thing, even though they share almost no words.
Chunking. Splitting documents into smaller pieces before storing them. Embeddings work on chunks, not whole documents — a 200-page manual embedded as one blob matches everything and nothing. Chunk size is a genuine design decision: too small and you lose context, too large and you dilute the signal.
Vector database. A database built to store embeddings and find the nearest ones to a query, fast. When people say “semantic search,” this is the machinery underneath it.
Top-K. How many chunks you pull back from the search. Top-K of 5 means “give me the 5 closest chunks.” More is not better — every irrelevant chunk you hand the model is an invitation to wander.
Reranking. A second, slower, more careful scoring pass. The vector search retrieves, say, 50 candidate chunks quickly and approximately; a reranker (often a cross-encoder model that reads the question and each chunk together) reorders them by true relevance and keeps the best few. Cheap retrieval for recall, expensive reranking for precision.
BM25. The classic keyword search algorithm — the technology behind decades of search engines. It matches actual words, weighted by rarity. Terrible at meaning, unbeatable at exact strings: error codes, part numbers, names, SKUs.
Dense vs. sparse retrieval. Dense = embedding-based (meaning). Sparse = keyword-based, like BM25 (exact words). Remember this pair; Hybrid RAG is just the two of them holding hands.
Knowledge graph. Information stored as entities and relationships — Customer → placed → Order → contains → Product — instead of as text chunks. You query it by traversal: following the links.
Grounding / faithfulness. Whether the answer is actually supported by the retrieved material, as opposed to the model improvising. The central quality question of every RAG system.
Hallucination. The model generating something fluent and false. In RAG, hallucination usually means the model answered beyond — or against — the context it was given.
Context window. How much text the model can consider at once, measured in tokens. Modern models offer 128K tokens and far beyond — which is what makes Long-Context RAG (type 9) possible at all.
With that in hand, the nine types will read easily.
1. Naive RAG — the baseline everything else improves on
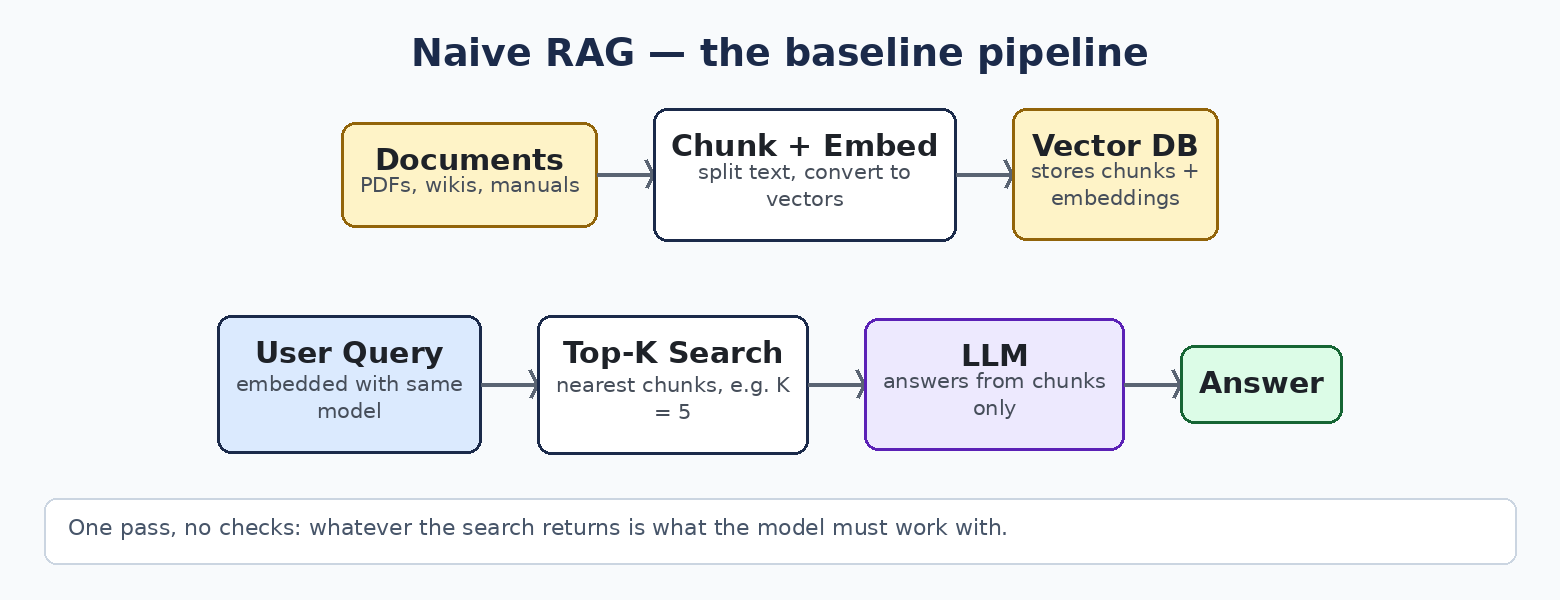
How it works. Documents are chunked, embedded, and stored in a vector database. A user question is embedded with the same model, the database returns the Top-K most similar chunks, those chunks are pasted into the prompt, and the LLM writes an answer from them. Four moving parts. You can build it in an afternoon.
When it earns its place. Internal document Q&A over a modest, well-behaved corpus. A proof of concept. Anywhere the questions are simple, the documents are the single source of truth, and “mostly right” is acceptable while you learn.
Where it breaks. Retrieval quality is the whole game, and naive retrieval is weak: chunk boundaries cut answers in half, the closest chunk by embedding is often not the chunk that answers the question, and there is no mechanism to notice failure. It retrieves once, blindly, and the model must make the best of whatever came back.
Say it in the interview. “Naive RAG is my starting point for any retrieval problem — it is the baseline you measure everything else against. I move beyond it the moment I can name the specific way retrieval is failing, because each advanced pattern exists to fix a particular failure.”
2. Advanced RAG — fixing retrieval before and after the search
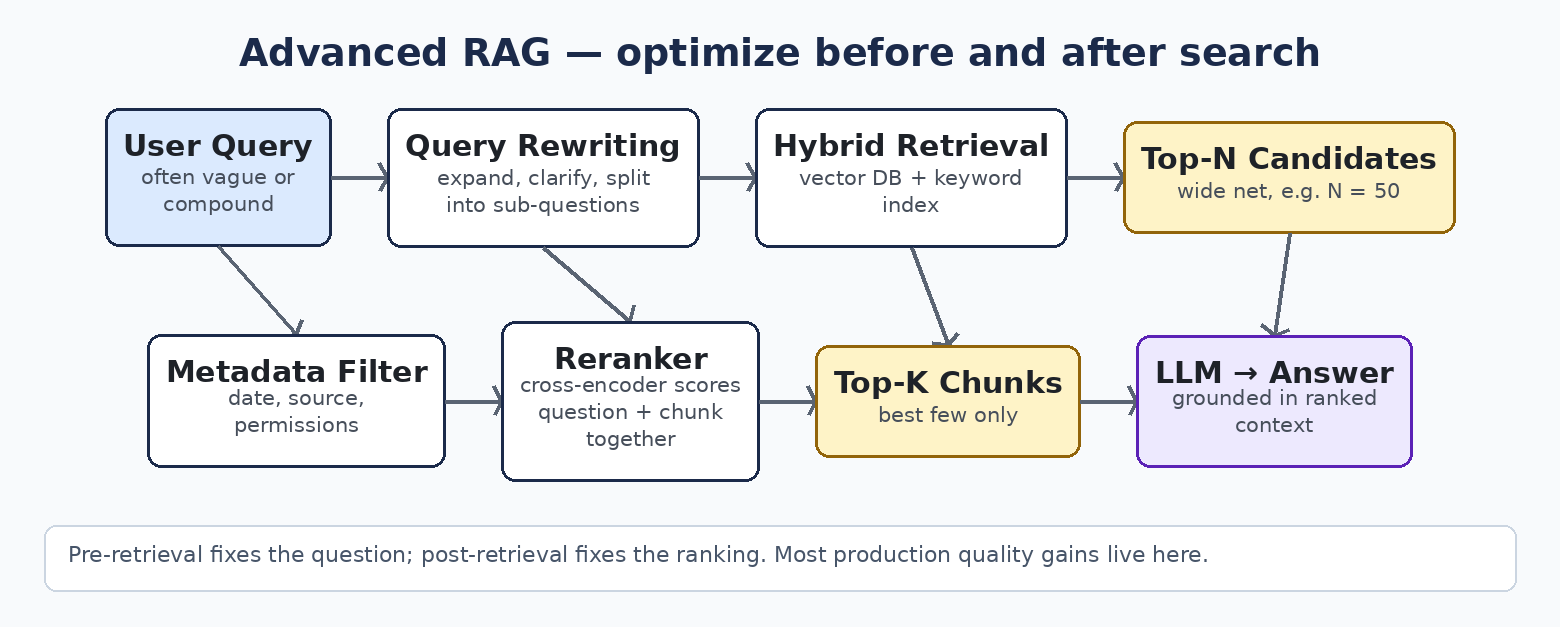
How it works. Advanced RAG keeps the naive skeleton and wraps it with effort on both sides of the search. Before retrieval: the user’s question is rewritten (expanded, clarified, or split into sub-questions), because users ask badly and embeddings punish vague queries. After retrieval: results are filtered by metadata and reranked, so the model sees the best few chunks rather than the merely closest ones.
When it earns its place. When your naive system retrieves almost the right material — relevant documents exist, but the wrong passages surface. Complex or domain-specific corpora, where vocabulary is precise and questions are not. This is the single most common upgrade in production systems, because most RAG quality problems are retrieval problems wearing a disguise.
Where it breaks. Every added stage is latency and a tuning surface. A bad query rewrite can drag retrieval further from the answer than the original question would have. You now have knobs — rewrite strategy, filter logic, reranker choice, Top-K at each stage — and knobs demand evaluation, or you are tuning by vibes.
Say it in the interview. “Advanced RAG is pre-retrieval and post-retrieval optimization around the same core loop. Query rewriting fixes the question, reranking fixes the ranking. In my experience it is where the largest quality gains per dollar live.”
3. Modular RAG — RAG as interchangeable parts
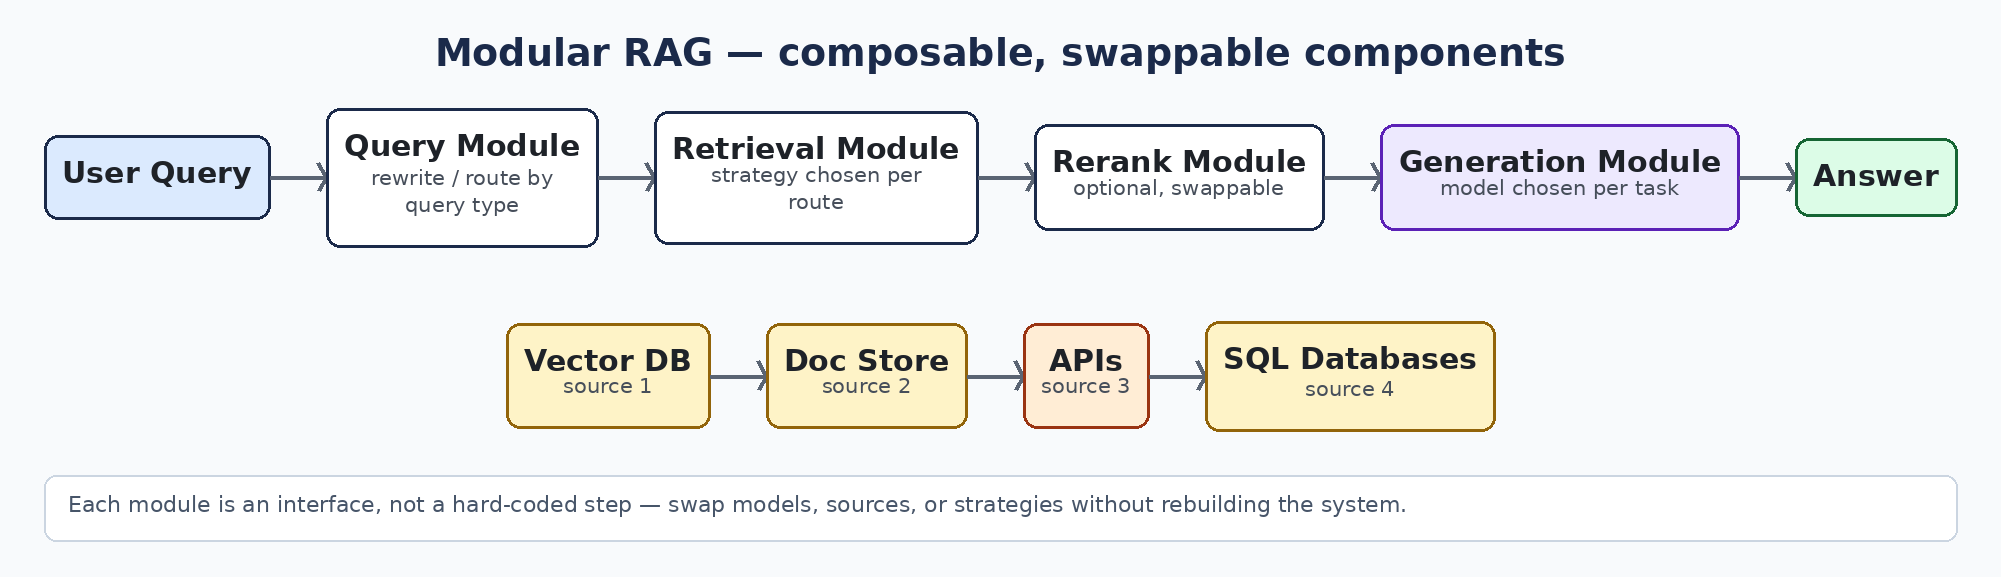
How it works. Instead of one fixed pipeline, the system is decomposed into modules — a query module, a retrieval module, a reranking module, a generation module — each swappable, each potentially backed by different sources: a vector database here, a document store there, an API or a SQL database alongside. Different queries can be routed through different combinations.
When it earns its place. Platforms, not features. When one team serves many use cases, when you need to experiment with components without rebuilding the system, or when different query types genuinely need different strategies. Modular RAG is less an architecture you choose on day one and more the shape a maturing system grows into.
Where it breaks. Abstraction is not free. You are now maintaining an orchestration layer, versioning components, and debugging interactions between parts that each look fine alone. For a single use case, it is engineering effort spent on flexibility you may never use.
Say it in the interview. “Modular RAG treats retrieval as composable services rather than a fixed pipeline. I reach for it when the system serves multiple use cases or sources — and I am honest that for one use case, it is over-engineering.”
4. Hybrid RAG — meaning and exact words, together
How it works. Run two retrievals in parallel: dense retrieval (embeddings) for meaning, and sparse retrieval (BM25) for exact keyword match. Merge the two result lists — typically with a fusion technique like Reciprocal Rank Fusion — then rerank the merged set and generate as usual.
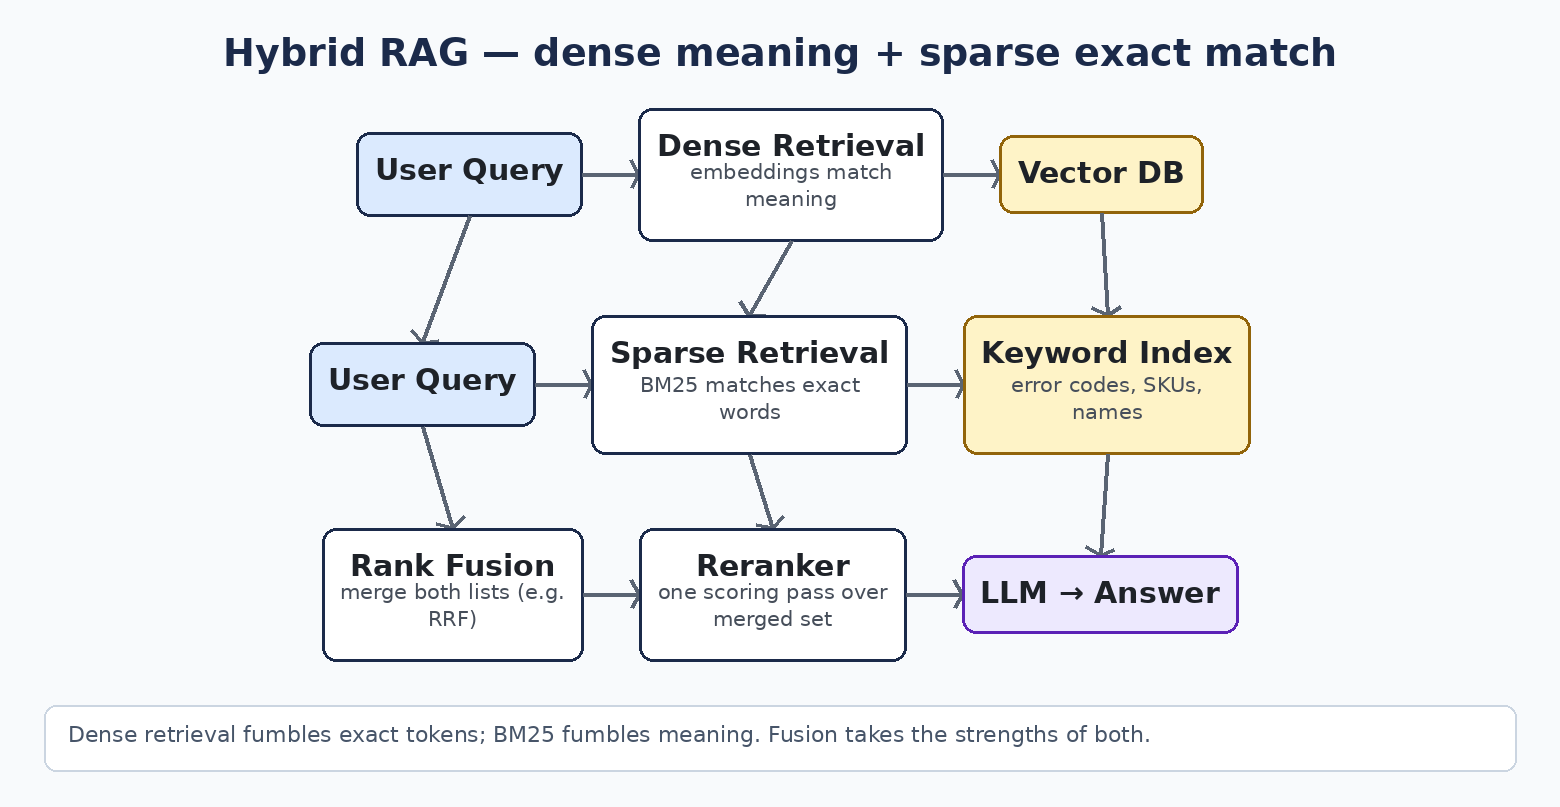
When it earns its place. Anywhere exact strings carry meaning: error codes, product IDs, drug names, legal clauses, ticker symbols. Semantic search is famously blind here — an embedding will happily return text about a similar error code. BM25 will not. Real enterprise corpora are full of such strings, which is why hybrid is the quiet default in serious production systems.
Where it breaks. Two indexes to build, keep in sync, and tune. The fusion weighting between dense and sparse results is corpus-dependent, and the merged candidate set is bigger, so reranking cost rises.
Say it in the interview. “Embeddings match meaning but fumble exact tokens — SKUs, error codes, names. BM25 is the opposite. Hybrid retrieval runs both and fuses the rankings, and in enterprise data, where exact identifiers matter, it is usually my production default.”
5. Graph RAG — when the answer lives in the relationships
How it works. Instead of (or alongside) chunking text, you extract entities and their relationships into a knowledge graph. A question is answered by identifying the entities it mentions and traversing the graph — following relationships across nodes — then handing the connected subgraph to the model as context.
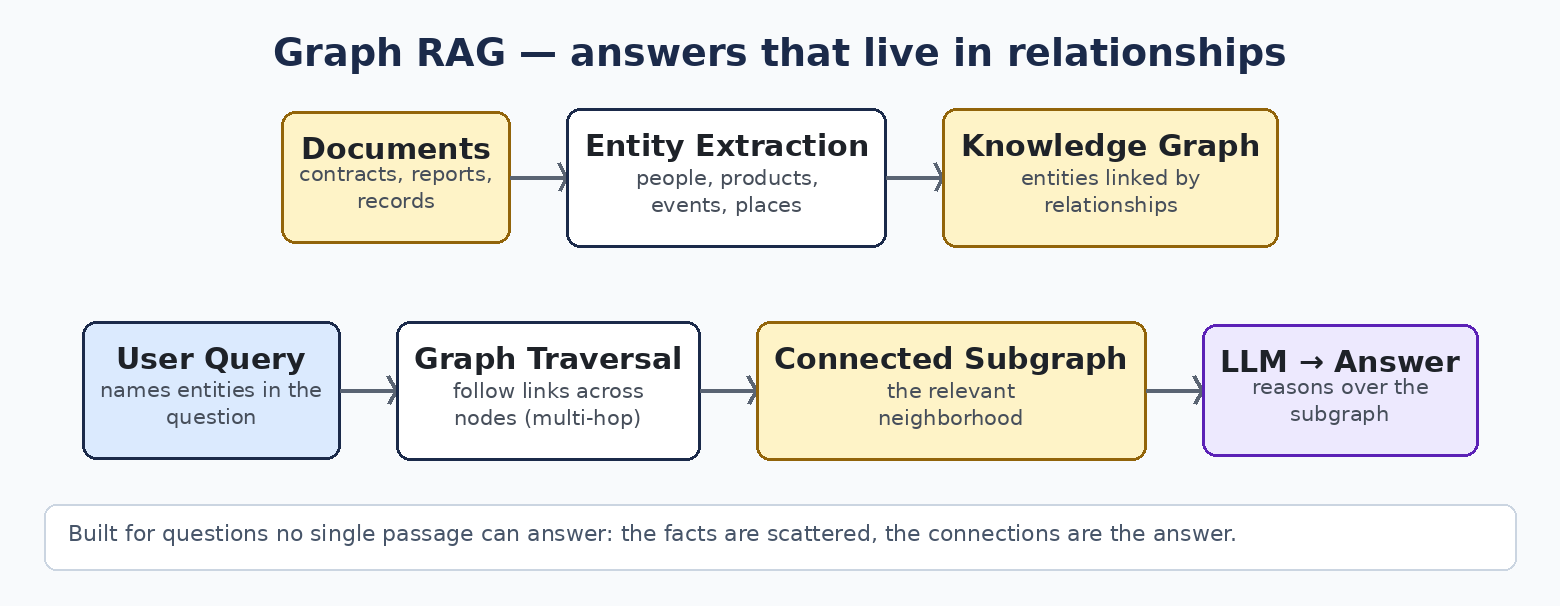
When it earns its place. Multi-hop questions: “Which suppliers provide components for the products that failed inspection last quarter?” No single document contains that answer; it exists only in the connections. Also for thematic questions over a whole corpus — “what are the main risk themes across these 500 reports?” — where chunk retrieval returns fragments but a graph can summarize structure.
Where it breaks. Somebody has to build and maintain the graph. Entity extraction is imperfect, relationships drift as data changes, and graph construction over a large corpus is a project in itself. If your questions are simple lookups, you have bought a very expensive way to avoid a vector search.
Say it in the interview. “Graph RAG answers questions whose answers live in relationships, not in any single passage. The cost is graph construction and upkeep, so I justify it with genuinely multi-hop questions — and I can point to the queries that chunk retrieval structurally cannot answer.”
6. Agentic RAG — retrieval that thinks in loops
How it works. An AI agent — typically with a planning step — decides what to retrieve, from where, and whether it has enough. It can search documents, query a vector store, call web search, hit APIs, or run SQL, then reason about the results and loop: refine, search again, or answer. Retrieval stops being a single function call and becomes a decision process.
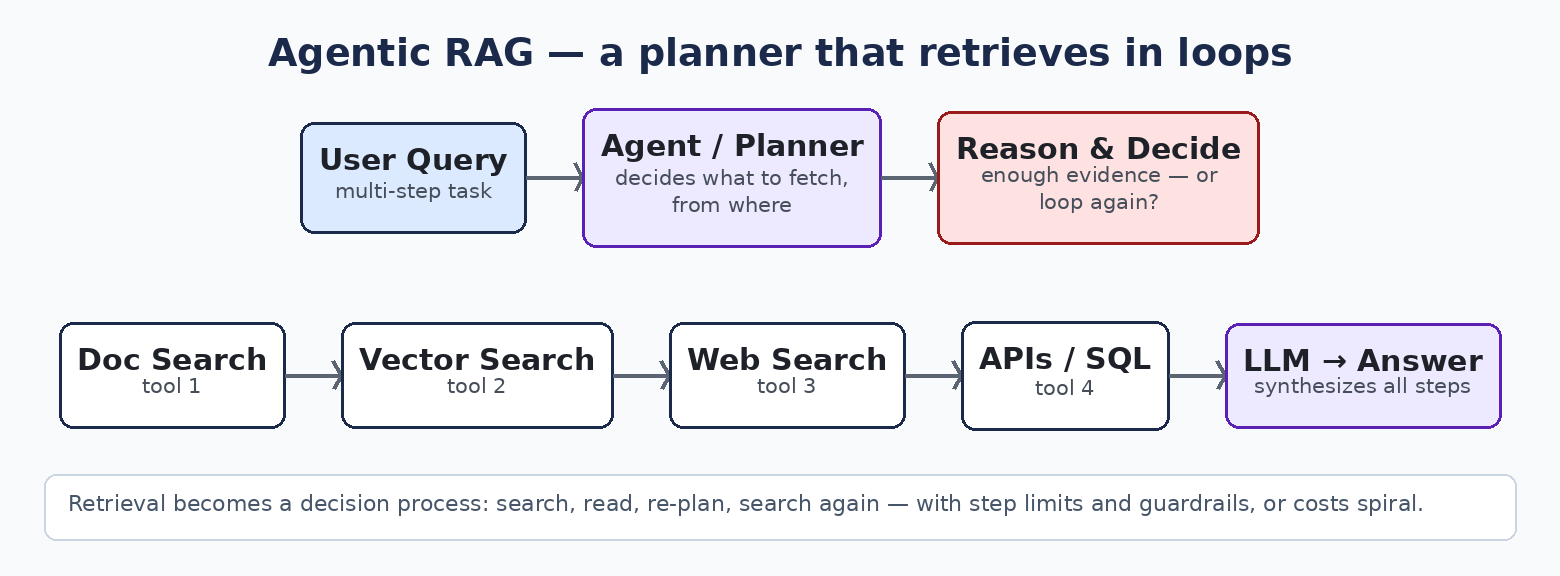
When it earns its place. Questions that need multiple steps and multiple sources: research tasks, investigations, anything where step two depends on what step one found. Also when the right source varies by question — no fixed pipeline can route as flexibly as an agent that reads the question and chooses.
Where it breaks. Everything compounds: latency (each loop is model calls), cost (same), and evaluation complexity (the path differs every run, so “why did it fail” becomes a forensic question). Agents also fail in agent ways — loops that never converge, tools called with malformed inputs, confident plans built on a misread first result. Guardrails and step limits are not optional.
Say it in the interview. “Agentic RAG replaces the fixed pipeline with a planner that chooses sources and iterates. It is the most capable pattern and the most expensive to run and evaluate, so I use it when the task genuinely requires multi-step reasoning over multiple sources — not as a default.”
7. Corrective RAG (CRAG) — retrieval that grades itself
How it works. After retrieval, a lightweight evaluator scores the retrieved material for relevance before generation. Good context goes straight to the model. Poor context triggers corrective action — the query is refined and retrieval runs again, possibly against an alternative source such as web search. The system checks its own homework before answering. (From the CRAG paper, Yan et al., 2024.)
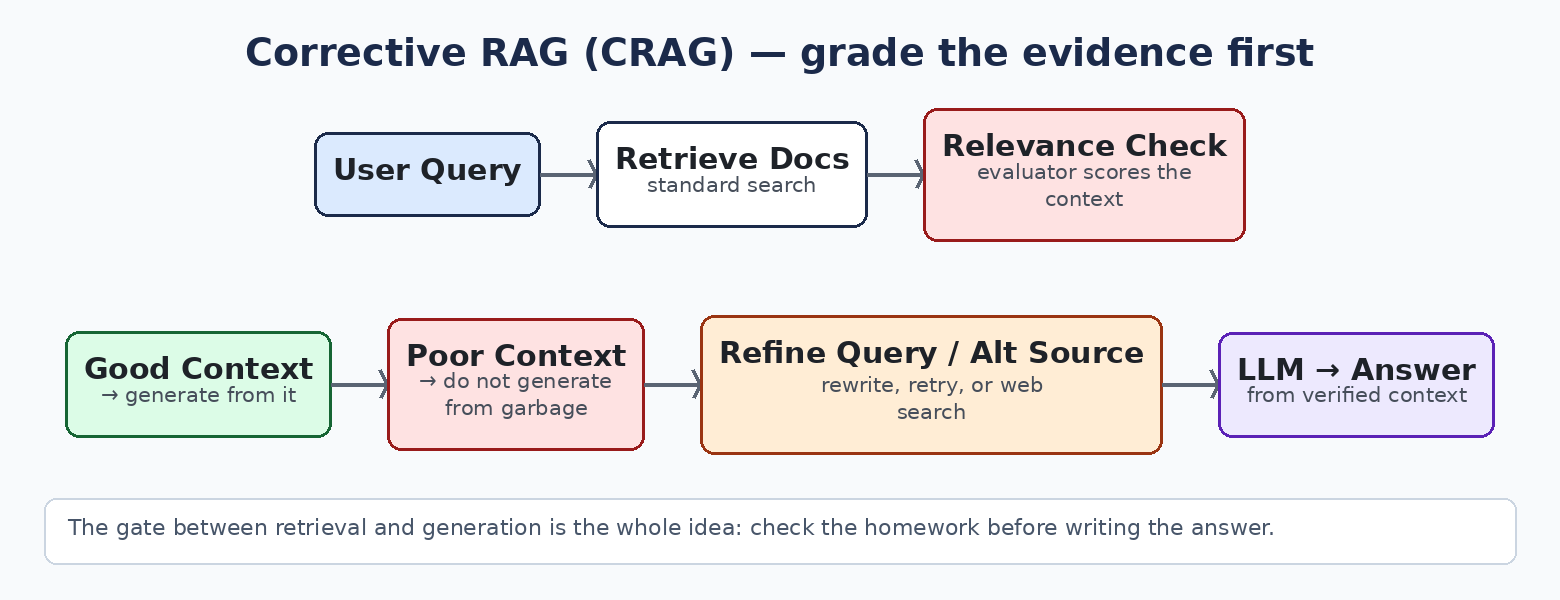
When it earns its place. When retrieval quality varies — mixed corpora, uneven document quality, questions that sometimes fall outside the knowledge base entirely. Also anywhere a wrong answer is expensive: if the context is bad, CRAG’s fallback beats generating from garbage and hoping.
Where it breaks. The evaluator is itself a model with errors; a relevance check that wrongly rejects good context adds cost and latency for nothing. The fallback path (web search, say) introduces its own trust questions. More components, more evaluation logic to validate.
Say it in the interview. “CRAG adds a relevance gate between retrieval and generation: score the context, and if it is poor, correct — rewrite the query, try another source — instead of generating from bad evidence. It is the pattern I choose when retrieval quality is uneven and wrong answers are costly.”
8. Self-RAG — the model decides whether to retrieve, then grades its own answer
How it works. Self-RAG (Asai et al., 2023) trains the model itself to control the process. The model first decides whether retrieval is even needed for this question. If it retrieves, it generates while critiquing its own output with special “reflection tokens” — judging whether passages support the answer and whether the answer is useful — and can retrieve again if its confidence is low.
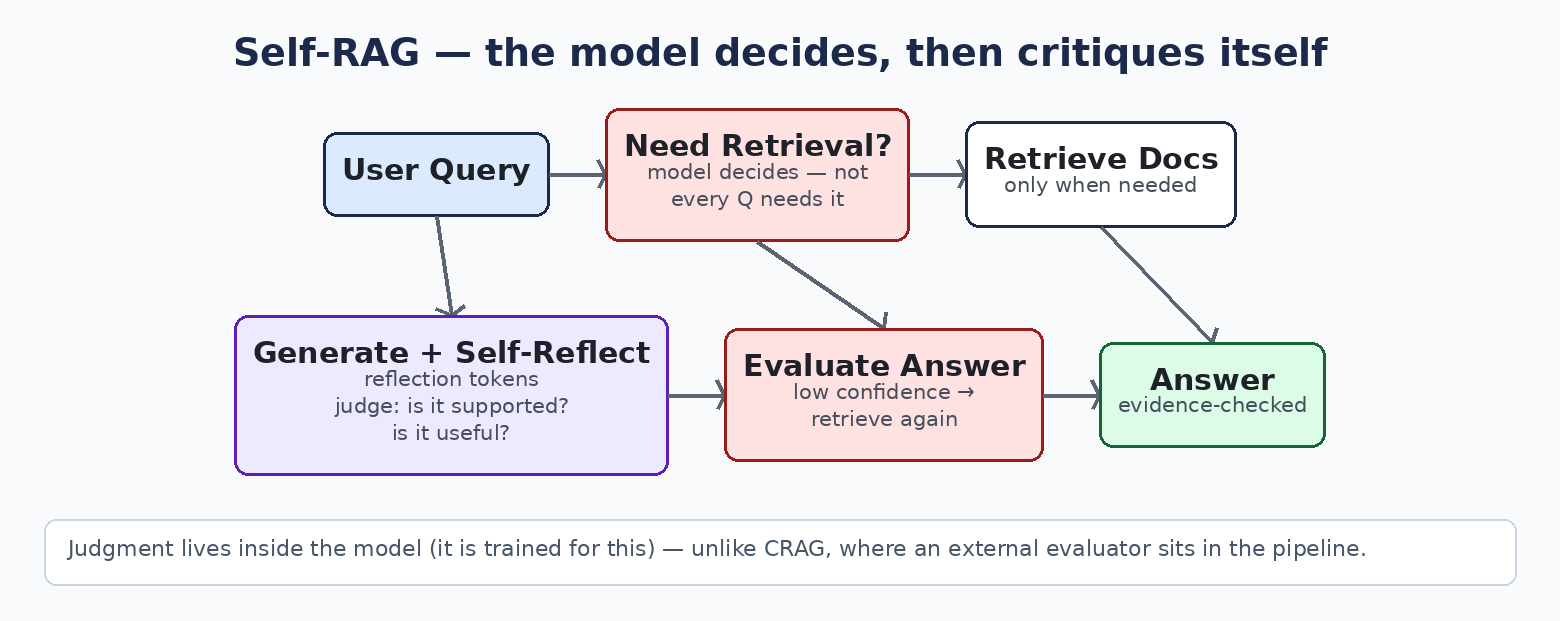
When it earns its place. Mixed workloads: many questions the model can answer from its own knowledge, some that demand evidence. Retrieving for every question wastes cost and can actively hurt — irrelevant context drags good answers down. Self-RAG also shines where you want evidence-grounded generation with explicit self-checking built in, rather than bolted on.
Where it breaks. It requires a model trained (or fine-tuned) for the reflection-token scheme — you cannot bolt Self-RAG onto an arbitrary off-the-shelf model the way you can with CRAG. The extra critique steps cost tokens and time, and the quality of the whole loop depends on that specialized training.
Say it in the interview. “Self-RAG puts the control inside the model: it learns when to retrieve and how to critique its own generations using reflection tokens. The distinction from CRAG is where the judgment lives — in the model’s training versus an external evaluator in the pipeline.”
9. Long-Context RAG — when the window got big enough to skip the funnel
How it works. Modern models accept enormous inputs — 128K tokens and well beyond. Long-context RAG retrieves generously (large sections, or entire documents) and lets the model’s attention do the fine-grained work that chunking and reranking used to do. The retrieval funnel gets wider and shallower.
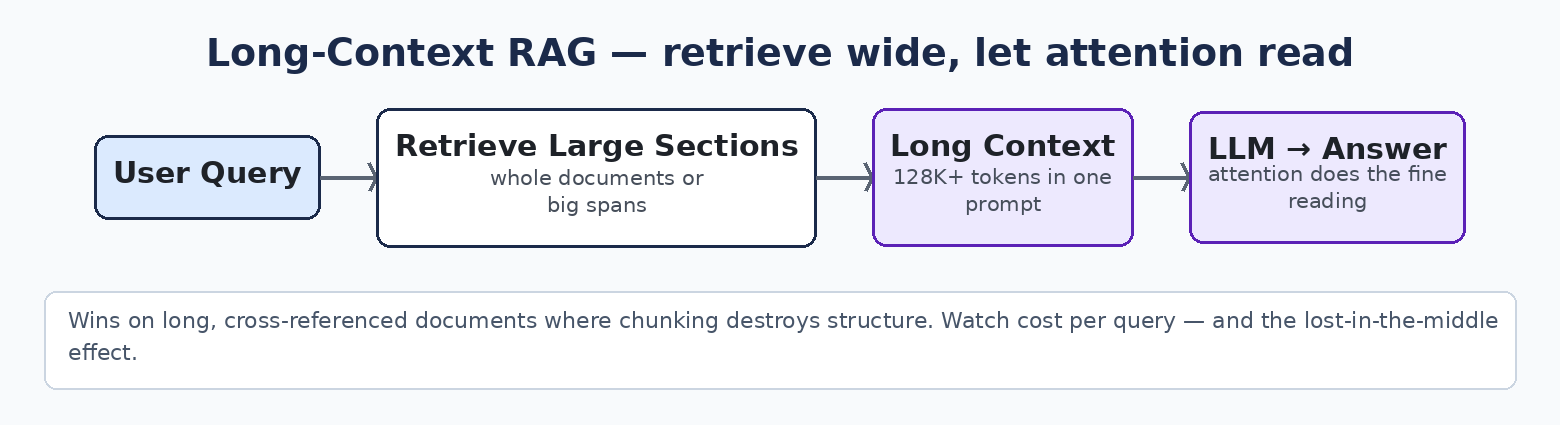
When it earns its place. Long, interconnected documents where answers span sections — contracts, clinical guidelines, regulatory filings — and chunking destroys exactly the cross-references that matter. Also small-to-medium corpora where “just put the relevant documents in the prompt” is honestly feasible.
Where it breaks. Inference cost scales with input, and a fat context on every query gets expensive fast. And a hard truth from practice: more context is not automatically better accuracy. Models can lose material in the middle of very long inputs, and irrelevant bulk dilutes attention. Retrieval still earns its keep as a cost and focus mechanism — long context changes the trade-off, it does not repeal it.
Say it in the interview. “Long-context models let me retrieve coarsely and let attention do the fine work. It wins on interconnected documents, but I watch cost per query and the lost-in-the-middle effect — bigger context is a trade-off, not a free upgrade.”
The decision guide
Start from the problem, not the pattern:
| Your situation | Start with | Because |
|---|---|---|
| Simple document Q&A, small corpus, proving value | Naive RAG | Fastest path to a working baseline |
| Retrieval returns almost-right passages | Advanced RAG | Rewriting + reranking fix the ranking, cheaply |
| Exact codes, IDs, names matter alongside meaning | Hybrid RAG | Dense misses exact tokens; BM25 misses meaning; you need both |
| Questions connect entities across documents | Graph RAG | The answer is in the relationships, not any single passage |
| Multi-step questions spanning several sources/tools | Agentic RAG | A planner can route and iterate; a fixed pipeline cannot |
| Retrieval quality is uneven; wrong answers are expensive | Corrective RAG | Grade the evidence before you generate from it |
| Mixed workload; many questions need no retrieval | Self-RAG | The model learns when retrieval helps and when it hurts |
| Long, cross-referenced documents; modest corpus | Long-Context RAG | Chunking destroys the structure the answers depend on |
| Multiple use cases on one platform | Modular RAG | Composable parts beat one pipeline per use case |
And the sentence that ties it together, in any interview room: these patterns compose. A production system might be modular in structure, hybrid in retrieval, corrective at the gate, and agentic for its hardest query class. The nine types are a vocabulary for decisions, not a multiple-choice question with one right answer.
FAQs
Q: Is RAG better than fine-tuning?
They solve different problems. Fine-tuning changes how the model behaves — tone, format, task skill. RAG changes what the model knows at answer time. If your problem is “the model doesn’t know our current data,” that is RAG. If it is “the model doesn’t follow our format,” that is fine-tuning. Serious systems often use both, and reaching for fine-tuning to inject facts is the classic beginner mistake — facts change, and retraining is a slow way to update them.
Q: What chunk size should I use?
There is no universal number, which is exactly why interviewers ask. Reasonable defaults are a few hundred tokens with some overlap between chunks, but the honest answer is: it depends on the document structure and the questions, and you decide by evaluating retrieval quality on real queries, not by folklore. Structure-aware chunking (splitting on headings, keeping tables intact) usually beats any magic number.
Q: How do I know if my RAG system is actually good?
Evaluate the two halves separately. Retrieval: are the right chunks coming back (recall and ranking quality against a set of real questions with known answers)? Generation: is the answer faithful to the retrieved context, and does it actually address the question? Teams that only eyeball final answers cannot tell which half is failing — and it is usually retrieval.
Q: Vector database — which one should I pick?
For most teams, the honest answer is: the one that fits your existing stack and scale, because at moderate scale they are more alike than different. The decision matters more at very large scale, with heavy metadata filtering, or with hybrid search requirements. In an interview, talk about the criteria — scale, filtering, hybrid support, operational burden — not brand loyalty.
Q: Doesn’t long context make RAG obsolete?
No — it reprices it. Stuffing everything into the prompt costs more per query, slows responses, and can reduce accuracy when relevant material sits buried mid-context. Retrieval remains how you control cost and focus attention. What long context changes is granularity: you can retrieve documents instead of fragments and let the model read widely within a selected set.
Q: When should I NOT use RAG at all?
When the knowledge is tiny and static (put it in the prompt), when the task needs no external facts (pure reasoning or transformation), and when the real problem is structured transactions — if the user needs the current account balance, that is a database query or a tool call, not a document search.
Q: How do I stop a RAG system from answering questions it has no evidence for?
Teach it to abstain. Instruct the model to answer only from context and to say so when the context is insufficient, evaluate faithfulness, and consider a corrective pattern (CRAG) that detects poor retrieval before generation. A system that says “I don’t have that in the knowledge base” is worth ten that improvise.
Q: What’s the difference between CRAG and Self-RAG?
Where the judgment lives. CRAG puts an external evaluator in the pipeline — any model can sit behind it. Self-RAG builds the judgment into the model itself through training with reflection tokens. CRAG is easier to adopt; Self-RAG is more integrated but requires the specialized model.
Interview rapid-fire
“Walk me through how you’d design a RAG system for [our documents].”
Start with the naive baseline and say so. Then ask (or state assumptions) about corpus size, question types, exact-match needs, and cost of a wrong answer — and let those answers pull in advanced, hybrid, or corrective patterns one at a time, naming the failure each addition fixes. This structure — baseline, then failure-driven upgrades — is the strongest signal you can send.
“Our RAG system hallucinates. What do you check first?”
Whether the retrieved context contained the answer at all. Most “hallucination” in RAG is retrieval failure followed by the model filling the gap. Check retrieval quality on the failing questions before touching prompts or models.
“Why not just use a bigger model?”
A bigger model reasons better over the context it is given; it does not fix being given the wrong context, and it multiplies cost across every query. Architecture first, model size second.
“How would you cut our RAG costs?”
Retrieve less but better (reranking lets you shrink Top-K), cache frequent queries and embeddings, route simple questions to smaller models, and reserve agentic or long-context patterns for the query classes that demonstrably need them.
The one-sentence version
RAG is not a product you install; it is a set of decisions about how evidence reaches the model — and the right architecture is the simplest one whose failure modes you have actually observed and priced.
Start simple. Measure. Add exactly the complexity your failures demand. That sentence will carry you through most interviews — and, not coincidentally, most production systems too.
If this helped, subscribe to The Agentic Enterprise below — one practical AI architecture breakdown a month, written from production experience, no hype. And if you are preparing for interviews, the free GenAI Interview Question Bank on the Free Toolkits page goes deeper.

