
Author: Jugal Shah

  • The 9 Types of RAG, Explained: Pick the Right Architecture (and Survive the Interview)

    Every RAG system that fails in production fails the same quiet way. The demo worked. The model was fine. Then real users arrived with real questions — misspelled product codes, questions that span four documents, questions the knowledge base simply cannot answer — and the system started producing confident, fluent, wrong answers.

    Nine times out of ten, the problem is not the model. It is the architecture choice. Somebody picked the simplest possible retrieval design, shipped it, and never revisited the decision when the questions outgrew it.

    That is what this guide is for. There are nine RAG architectures worth knowing. They are not nine competing products — they are nine answers to nine different failure modes. By the end, you should be able to do three things: look at a use case and pick the right type, explain why in plain language, and hold your own when an interviewer starts pushing on the trade-offs.

    One rule before we start, and it is the rule every experienced builder I know follows: start with the simplest architecture that could work, and add complexity only when a specific, observed failure demands it. Every layer you add buys accuracy with latency, cost, and moving parts. Spend that budget only where the failures actually are.

    First, the vocabulary (because interviews are lost here)

    Most RAG explanations drown in jargon. Let us fix that first, because every architecture below is built from these same blocks.

    Embedding. A piece of text converted into a list of numbers (a vector) that captures its meaning. Texts with similar meanings get similar numbers. This is how a system can know that “how do I reset my password” and “forgot my login credentials” are asking the same thing, even though they share almost no words.

    Chunking. Splitting documents into smaller pieces before storing them. Embeddings work on chunks, not whole documents — a 200-page manual embedded as one blob matches everything and nothing. Chunk size is a genuine design decision: too small and you lose context, too large and you dilute the signal.

    Vector database. A database built to store embeddings and find the nearest ones to a query, fast. When people say “semantic search,” this is the machinery underneath it.

    Top-K. How many chunks you pull back from the search. Top-K of 5 means “give me the 5 closest chunks.” More is not better — every irrelevant chunk you hand the model is an invitation to wander.

    Reranking. A second, slower, more careful scoring pass. The vector search retrieves, say, 50 candidate chunks quickly and approximately; a reranker (often a cross-encoder model that reads the question and each chunk together) reorders them by true relevance and keeps the best few. Cheap retrieval for recall, expensive reranking for precision.

    BM25. The classic keyword search algorithm — the technology behind decades of search engines. It matches actual words, weighted by rarity. Terrible at meaning, unbeatable at exact strings: error codes, part numbers, names, SKUs.

    Dense vs. sparse retrieval. Dense = embedding-based (meaning). Sparse = keyword-based, like BM25 (exact words). Remember this pair; Hybrid RAG is just the two of them holding hands.

    Knowledge graph. Information stored as entities and relationships — Customer → placed → Order → contains → Product — instead of as text chunks. You query it by traversal: following the links.

    Grounding / faithfulness. Whether the answer is actually supported by the retrieved material, as opposed to the model improvising. The central quality question of every RAG system.

    Hallucination. The model generating something fluent and false. In RAG, hallucination usually means the model answered beyond — or against — the context it was given.

    Context window. How much text the model can consider at once, measured in tokens. Modern models offer 128K tokens and far beyond — which is what makes Long-Context RAG (type 9) possible at all.

    With that in hand, the nine types will read easily.


    1. Naive RAG — the baseline everything else improves on

    How it works. Documents are chunked, embedded, and stored in a vector database. A user question is embedded with the same model, the database returns the Top-K most similar chunks, those chunks are pasted into the prompt, and the LLM writes an answer from them. Four moving parts. You can build it in an afternoon.
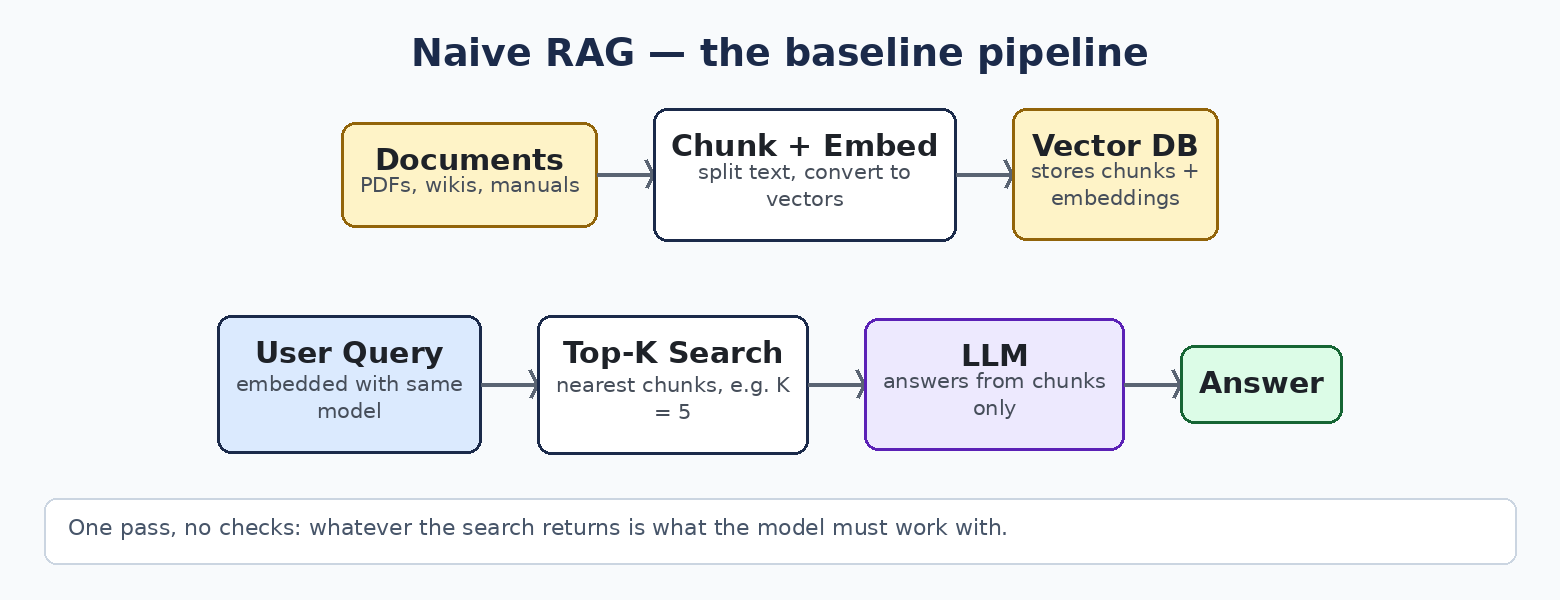
    Naive RAG diagram

    When it earns its place. Internal document Q&A over a modest, well-behaved corpus. A proof of concept. Anywhere the questions are simple, the documents are the single source of truth, and “mostly right” is acceptable while you learn.

    Where it breaks. Retrieval quality is the whole game, and naive retrieval is weak: chunk boundaries cut answers in half, the closest chunk by embedding is often not the chunk that answers the question, and there is no mechanism to notice failure. It retrieves once, blindly, and the model must make the best of whatever came back.

    Say it in the interview. “Naive RAG is my starting point for any retrieval problem — it is the baseline you measure everything else against. I move beyond it the moment I can name the specific way retrieval is failing, because each advanced pattern exists to fix a particular failure.”

    2. Advanced RAG — fixing retrieval before and after the search

    How it works. Advanced RAG keeps the naive skeleton and wraps it with effort on both sides of the search. Before retrieval: the user’s question is rewritten (expanded, clarified, or split into sub-questions), because users ask badly and embeddings punish vague queries. After retrieval: results are filtered by metadata and reranked, so the model sees the best few chunks rather than the merely closest ones.
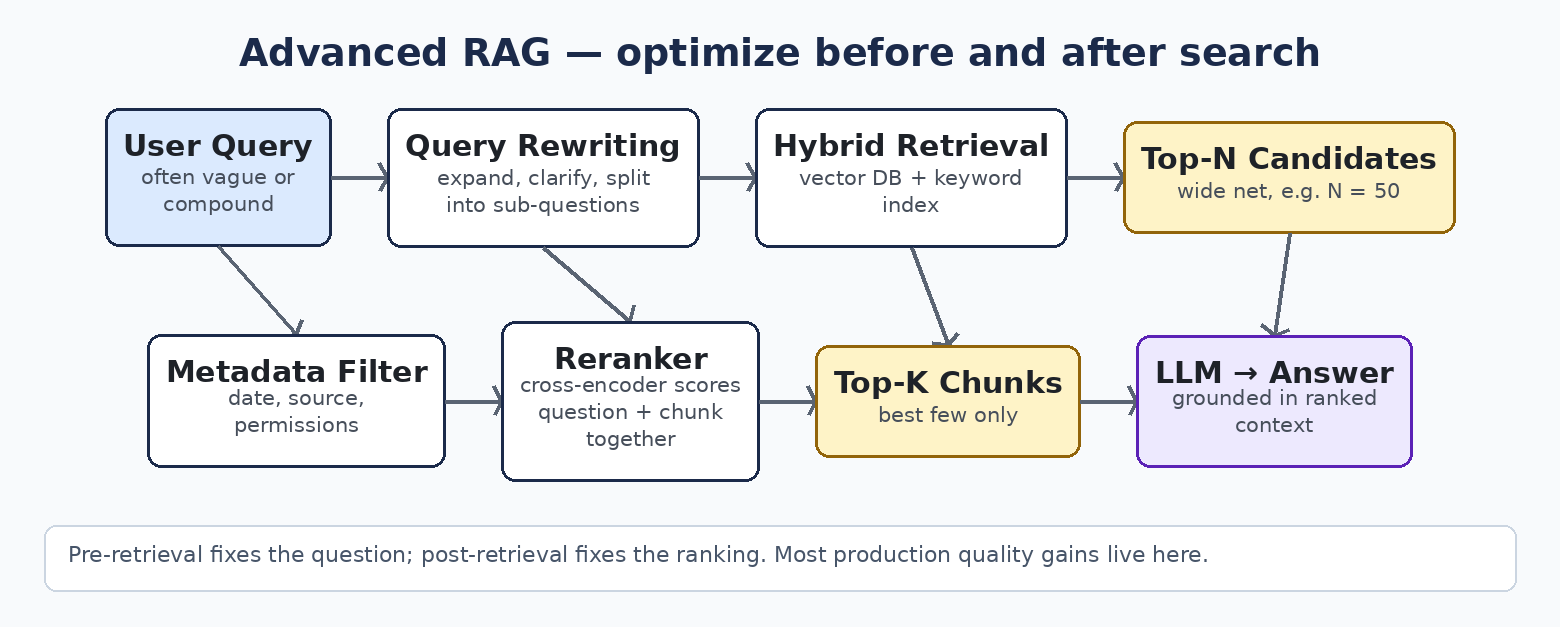
    Advanced RAG diagram

    When it earns its place. When your naive system retrieves almost the right material — relevant documents exist, but the wrong passages surface. Complex or domain-specific corpora, where vocabulary is precise and questions are not. This is the single most common upgrade in production systems, because most RAG quality problems are retrieval problems wearing a disguise.

    Where it breaks. Every added stage is latency and a tuning surface. A bad query rewrite can drag retrieval further from the answer than the original question would have. You now have knobs — rewrite strategy, filter logic, reranker choice, Top-K at each stage — and knobs demand evaluation, or you are tuning by vibes.

    Say it in the interview. “Advanced RAG is pre-retrieval and post-retrieval optimization around the same core loop. Query rewriting fixes the question, reranking fixes the ranking. In my experience it is where the largest quality gains per dollar live.”

    3. Modular RAG — RAG as interchangeable parts

    How it works. Instead of one fixed pipeline, the system is decomposed into modules — a query module, a retrieval module, a reranking module, a generation module — each swappable, each potentially backed by different sources: a vector database here, a document store there, an API or a SQL database alongside. Different queries can be routed through different combinations.
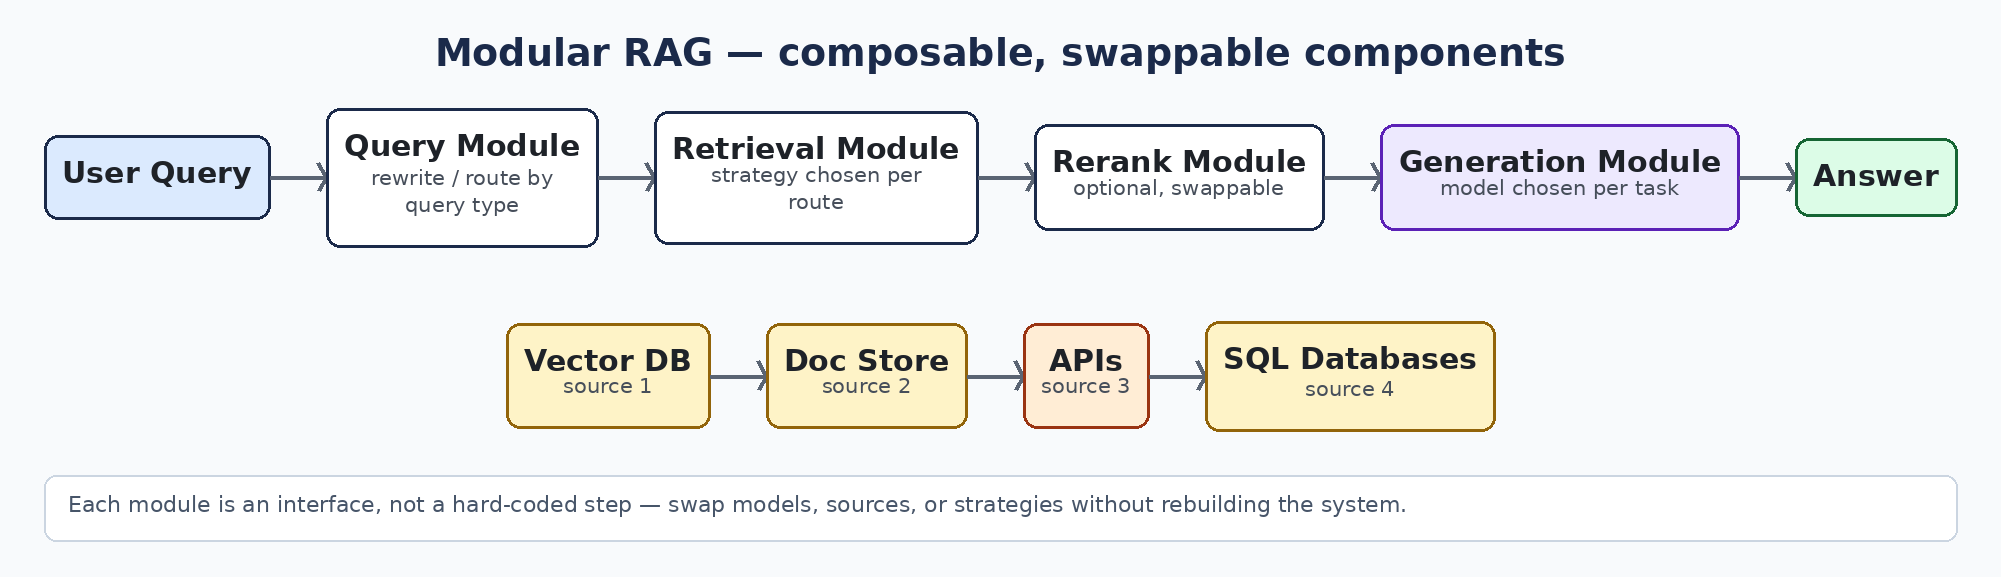
    Modular RAG diagram

    When it earns its place. Platforms, not features. When one team serves many use cases, when you need to experiment with components without rebuilding the system, or when different query types genuinely need different strategies. Modular RAG is less an architecture you choose on day one and more the shape a maturing system grows into.

    Where it breaks. Abstraction is not free. You are now maintaining an orchestration layer, versioning components, and debugging interactions between parts that each look fine alone. For a single use case, it is engineering effort spent on flexibility you may never use.

    Say it in the interview. “Modular RAG treats retrieval as composable services rather than a fixed pipeline. I reach for it when the system serves multiple use cases or sources — and I am honest that for one use case, it is over-engineering.”

    4. Hybrid RAG — meaning and exact words, together

    How it works. Run two retrievals in parallel: dense retrieval (embeddings) for meaning, and sparse retrieval (BM25) for exact keyword match. Merge the two result lists — typically with a fusion technique like Reciprocal Rank Fusion — then rerank the merged set and generate as usual.
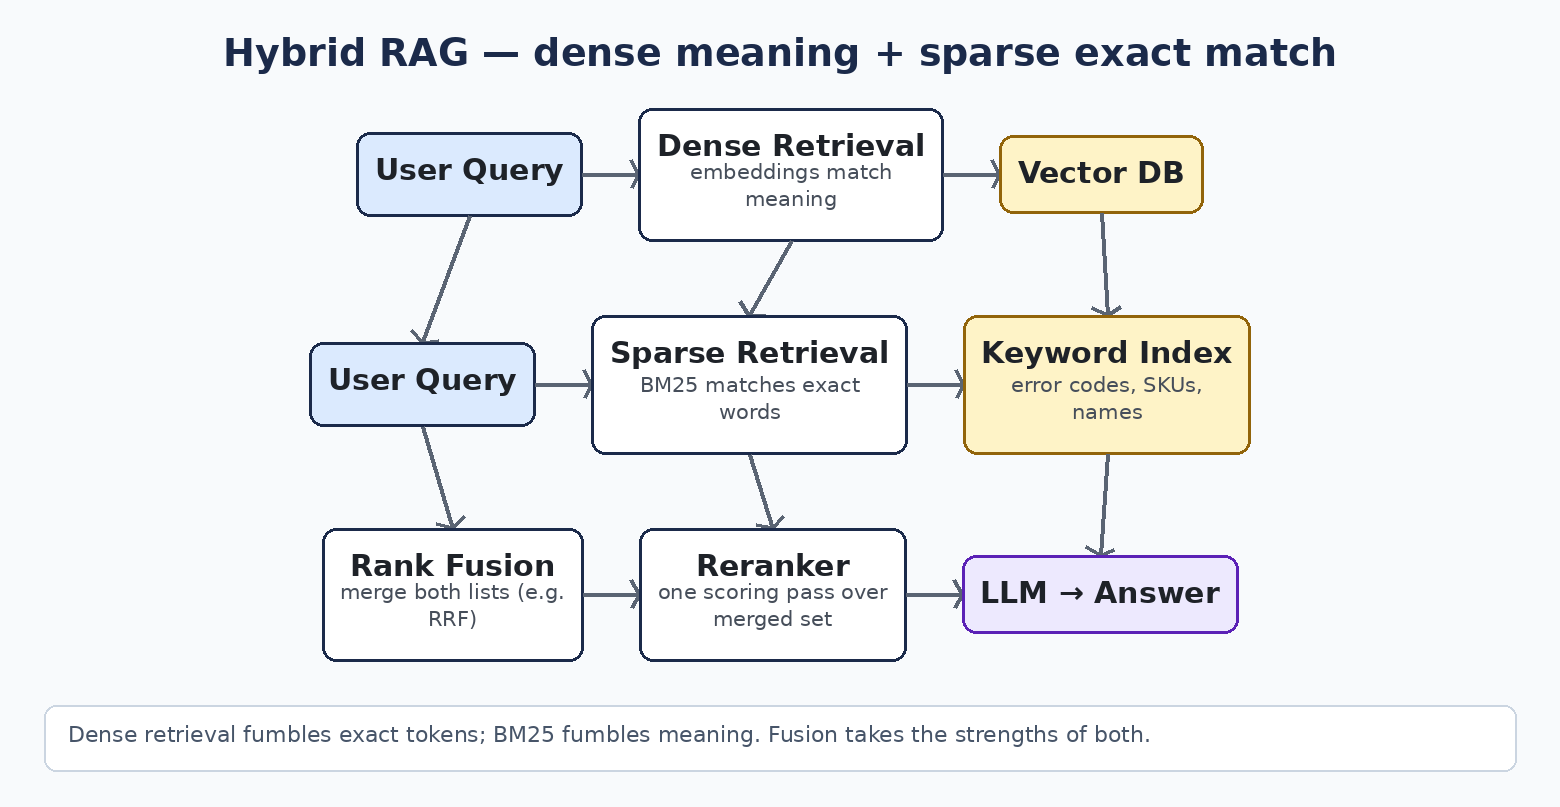
    Hybrid RAG diagram

    When it earns its place. Anywhere exact strings carry meaning: error codes, product IDs, drug names, legal clauses, ticker symbols. Semantic search is famously blind here — an embedding will happily return text about a similar error code. BM25 will not. Real enterprise corpora are full of such strings, which is why hybrid is the quiet default in serious production systems.

    Where it breaks. Two indexes to build, keep in sync, and tune. The fusion weighting between dense and sparse results is corpus-dependent, and the merged candidate set is bigger, so reranking cost rises.

    Say it in the interview. “Embeddings match meaning but fumble exact tokens — SKUs, error codes, names. BM25 is the opposite. Hybrid retrieval runs both and fuses the rankings, and in enterprise data, where exact identifiers matter, it is usually my production default.”

    5. Graph RAG — when the answer lives in the relationships

    How it works. Instead of (or alongside) chunking text, you extract entities and their relationships into a knowledge graph. A question is answered by identifying the entities it mentions and traversing the graph — following relationships across nodes — then handing the connected subgraph to the model as context.
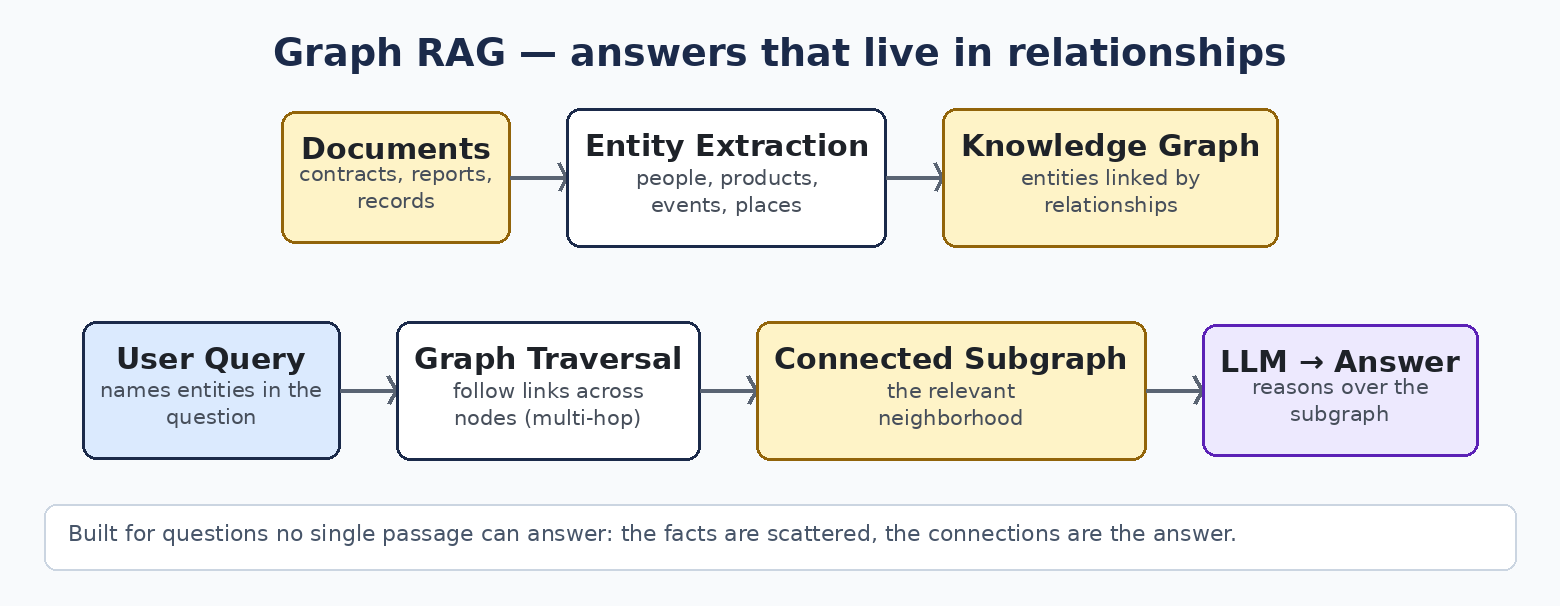
    Graph RAG diagram

    When it earns its place. Multi-hop questions: “Which suppliers provide components for the products that failed inspection last quarter?” No single document contains that answer; it exists only in the connections. Also for thematic questions over a whole corpus — “what are the main risk themes across these 500 reports?” — where chunk retrieval returns fragments but a graph can summarize structure.

    Where it breaks. Somebody has to build and maintain the graph. Entity extraction is imperfect, relationships drift as data changes, and graph construction over a large corpus is a project in itself. If your questions are simple lookups, you have bought a very expensive way to avoid a vector search.

    Say it in the interview. “Graph RAG answers questions whose answers live in relationships, not in any single passage. The cost is graph construction and upkeep, so I justify it with genuinely multi-hop questions — and I can point to the queries that chunk retrieval structurally cannot answer.”

    6. Agentic RAG — retrieval that thinks in loops

    How it works. An AI agent — typically with a planning step — decides what to retrieve, from where, and whether it has enough. It can search documents, query a vector store, call web search, hit APIs, or run SQL, then reason about the results and loop: refine, search again, or answer. Retrieval stops being a single function call and becomes a decision process.
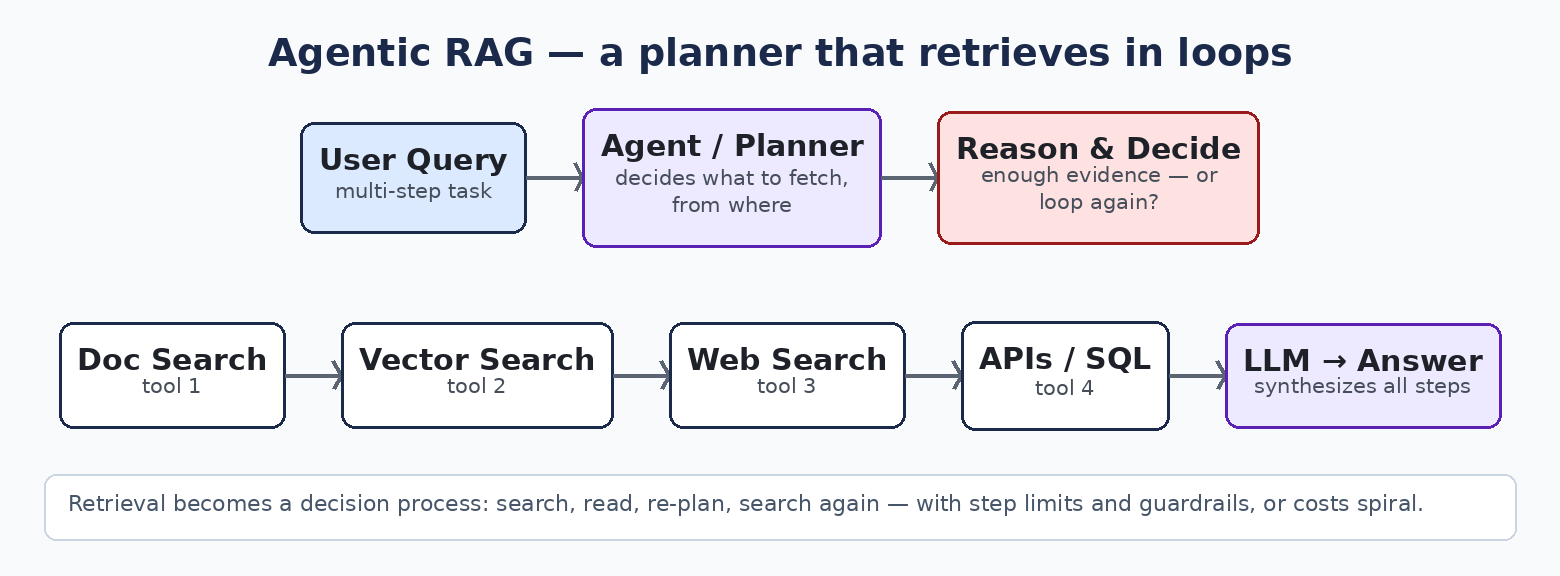
    Agentic RAG diagram

    When it earns its place. Questions that need multiple steps and multiple sources: research tasks, investigations, anything where step two depends on what step one found. Also when the right source varies by question — no fixed pipeline can route as flexibly as an agent that reads the question and chooses.

    Where it breaks. Everything compounds: latency (each loop is model calls), cost (same), and evaluation complexity (the path differs every run, so “why did it fail” becomes a forensic question). Agents also fail in agent ways — loops that never converge, tools called with malformed inputs, confident plans built on a misread first result. Guardrails and step limits are not optional.

    Say it in the interview. “Agentic RAG replaces the fixed pipeline with a planner that chooses sources and iterates. It is the most capable pattern and the most expensive to run and evaluate, so I use it when the task genuinely requires multi-step reasoning over multiple sources — not as a default.”

    7. Corrective RAG (CRAG) — retrieval that grades itself

    How it works. After retrieval, a lightweight evaluator scores the retrieved material for relevance before generation. Good context goes straight to the model. Poor context triggers corrective action — the query is refined and retrieval runs again, possibly against an alternative source such as web search. The system checks its own homework before answering. (From the CRAG paper, Yan et al., 2024.)
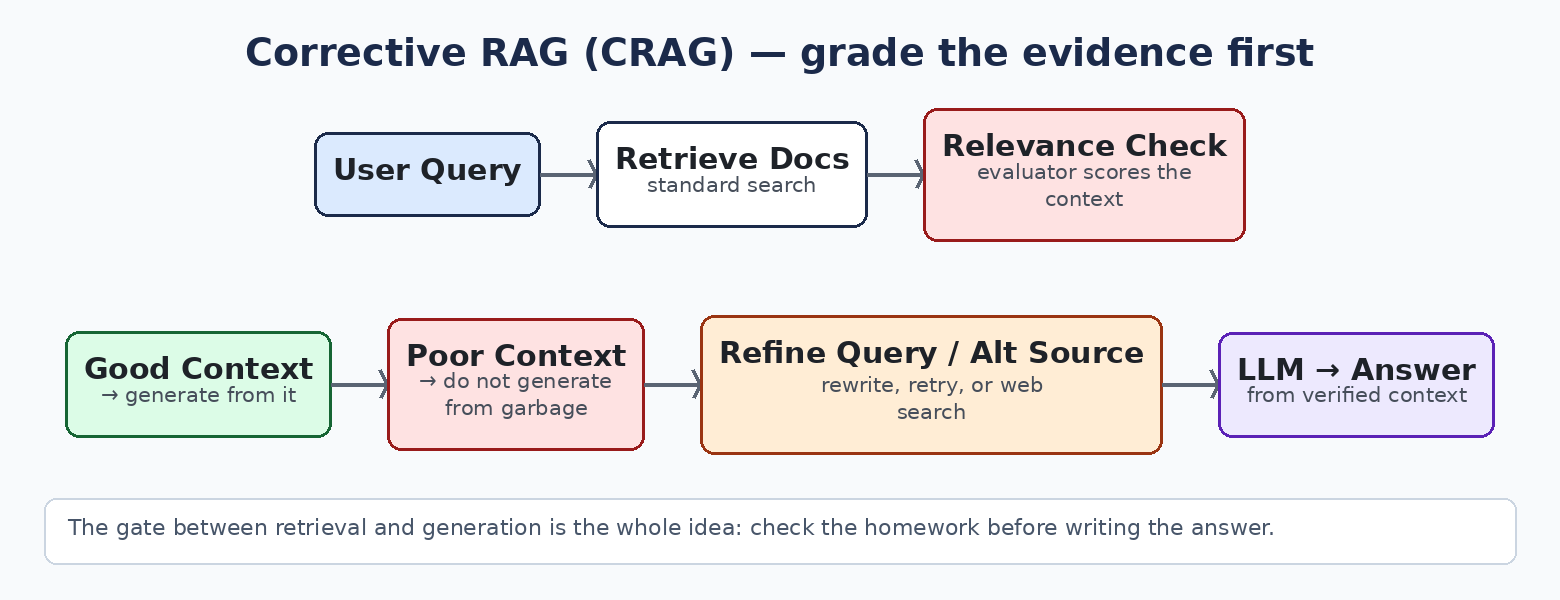
    Corrective RAG diagram

    When it earns its place. When retrieval quality varies — mixed corpora, uneven document quality, questions that sometimes fall outside the knowledge base entirely. Also anywhere a wrong answer is expensive: if the context is bad, CRAG’s fallback beats generating from garbage and hoping.

    Where it breaks. The evaluator is itself a model with errors; a relevance check that wrongly rejects good context adds cost and latency for nothing. The fallback path (web search, say) introduces its own trust questions. More components, more evaluation logic to validate.

    Say it in the interview. “CRAG adds a relevance gate between retrieval and generation: score the context, and if it is poor, correct — rewrite the query, try another source — instead of generating from bad evidence. It is the pattern I choose when retrieval quality is uneven and wrong answers are costly.”

    8. Self-RAG — the model decides whether to retrieve, then grades its own answer

    How it works. Self-RAG (Asai et al., 2023) trains the model itself to control the process. The model first decides whether retrieval is even needed for this question. If it retrieves, it generates while critiquing its own output with special “reflection tokens” — judging whether passages support the answer and whether the answer is useful — and can retrieve again if its confidence is low.
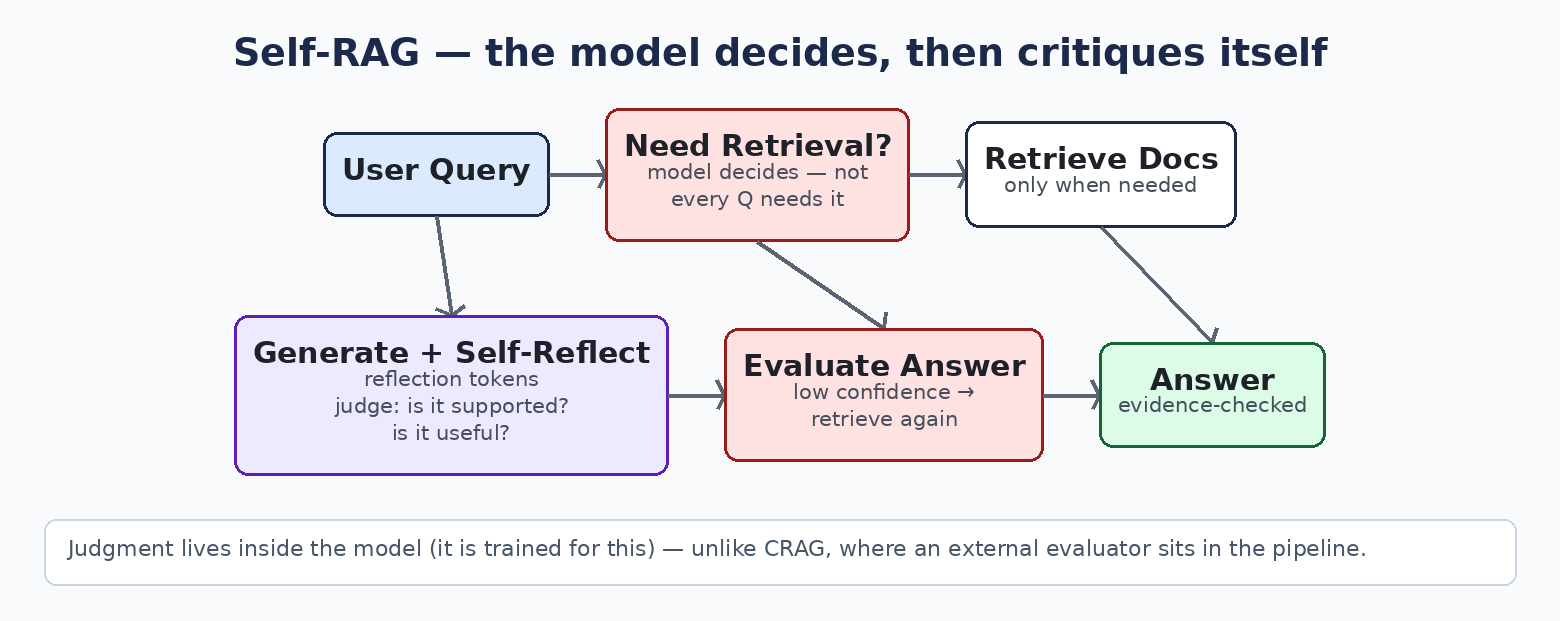
    Self-RAG diagram

    When it earns its place. Mixed workloads: many questions the model can answer from its own knowledge, some that demand evidence. Retrieving for every question wastes cost and can actively hurt — irrelevant context drags good answers down. Self-RAG also shines where you want evidence-grounded generation with explicit self-checking built in, rather than bolted on.

    Where it breaks. It requires a model trained (or fine-tuned) for the reflection-token scheme — you cannot bolt Self-RAG onto an arbitrary off-the-shelf model the way you can with CRAG. The extra critique steps cost tokens and time, and the quality of the whole loop depends on that specialized training.

    Say it in the interview. “Self-RAG puts the control inside the model: it learns when to retrieve and how to critique its own generations using reflection tokens. The distinction from CRAG is where the judgment lives — in the model’s training versus an external evaluator in the pipeline.”

    9. Long-Context RAG — when the window got big enough to skip the funnel

    How it works. Modern models accept enormous inputs — 128K tokens and well beyond. Long-context RAG retrieves generously (large sections, or entire documents) and lets the model’s attention do the fine-grained work that chunking and reranking used to do. The retrieval funnel gets wider and shallower.
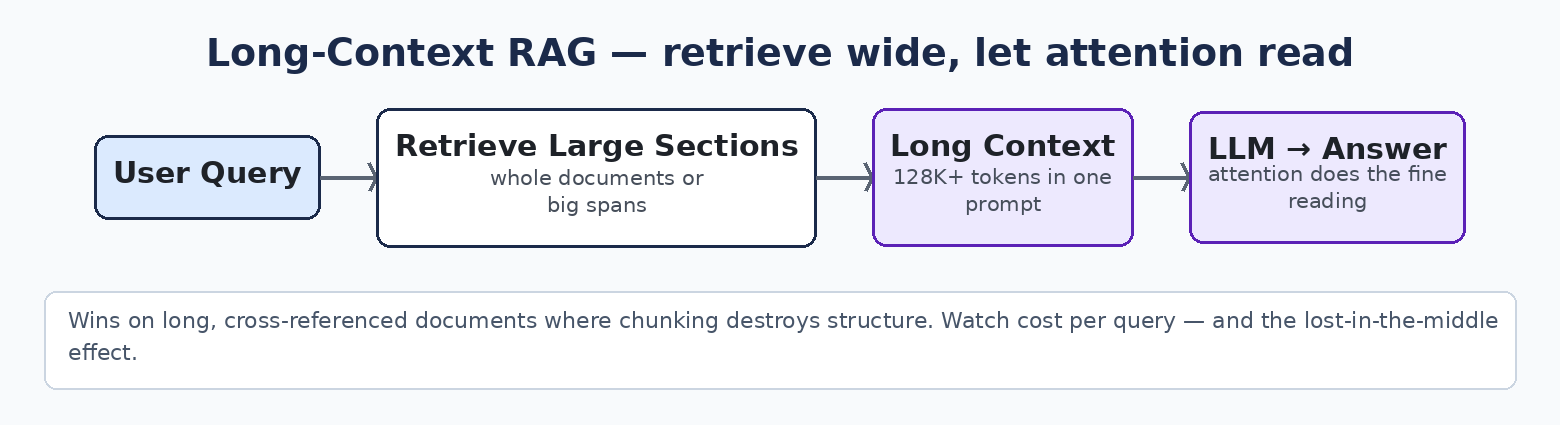
    Long-context RAG diagram

    When it earns its place. Long, interconnected documents where answers span sections — contracts, clinical guidelines, regulatory filings — and chunking destroys exactly the cross-references that matter. Also small-to-medium corpora where “just put the relevant documents in the prompt” is honestly feasible.

    Where it breaks. Inference cost scales with input, and a fat context on every query gets expensive fast. And a hard truth from practice: more context is not automatically better accuracy. Models can lose material in the middle of very long inputs, and irrelevant bulk dilutes attention. Retrieval still earns its keep as a cost and focus mechanism — long context changes the trade-off, it does not repeal it.

    Say it in the interview. “Long-context models let me retrieve coarsely and let attention do the fine work. It wins on interconnected documents, but I watch cost per query and the lost-in-the-middle effect — bigger context is a trade-off, not a free upgrade.”


    The decision guide

    Start from the problem, not the pattern:

    Your situationStart withBecause
    Simple document Q&A, small corpus, proving valueNaive RAGFastest path to a working baseline
    Retrieval returns almost-right passagesAdvanced RAGRewriting + reranking fix the ranking, cheaply
    Exact codes, IDs, names matter alongside meaningHybrid RAGDense misses exact tokens; BM25 misses meaning; you need both
    Questions connect entities across documentsGraph RAGThe answer is in the relationships, not any single passage
    Multi-step questions spanning several sources/toolsAgentic RAGA planner can route and iterate; a fixed pipeline cannot
    Retrieval quality is uneven; wrong answers are expensiveCorrective RAGGrade the evidence before you generate from it
    Mixed workload; many questions need no retrievalSelf-RAGThe model learns when retrieval helps and when it hurts
    Long, cross-referenced documents; modest corpusLong-Context RAGChunking destroys the structure the answers depend on
    Multiple use cases on one platformModular RAGComposable parts beat one pipeline per use case

    And the sentence that ties it together, in any interview room: these patterns compose. A production system might be modular in structure, hybrid in retrieval, corrective at the gate, and agentic for its hardest query class. The nine types are a vocabulary for decisions, not a multiple-choice question with one right answer.

    FAQs

    Q: Is RAG better than fine-tuning?

    They solve different problems. Fine-tuning changes how the model behaves — tone, format, task skill. RAG changes what the model knows at answer time. If your problem is “the model doesn’t know our current data,” that is RAG. If it is “the model doesn’t follow our format,” that is fine-tuning. Serious systems often use both, and reaching for fine-tuning to inject facts is the classic beginner mistake — facts change, and retraining is a slow way to update them.

    Q: What chunk size should I use?

    There is no universal number, which is exactly why interviewers ask. Reasonable defaults are a few hundred tokens with some overlap between chunks, but the honest answer is: it depends on the document structure and the questions, and you decide by evaluating retrieval quality on real queries, not by folklore. Structure-aware chunking (splitting on headings, keeping tables intact) usually beats any magic number.

    Q: How do I know if my RAG system is actually good?

    Evaluate the two halves separately. Retrieval: are the right chunks coming back (recall and ranking quality against a set of real questions with known answers)? Generation: is the answer faithful to the retrieved context, and does it actually address the question? Teams that only eyeball final answers cannot tell which half is failing — and it is usually retrieval.

    Q: Vector database — which one should I pick?

    For most teams, the honest answer is: the one that fits your existing stack and scale, because at moderate scale they are more alike than different. The decision matters more at very large scale, with heavy metadata filtering, or with hybrid search requirements. In an interview, talk about the criteria — scale, filtering, hybrid support, operational burden — not brand loyalty.

    Q: Doesn’t long context make RAG obsolete?

    No — it reprices it. Stuffing everything into the prompt costs more per query, slows responses, and can reduce accuracy when relevant material sits buried mid-context. Retrieval remains how you control cost and focus attention. What long context changes is granularity: you can retrieve documents instead of fragments and let the model read widely within a selected set.

    Q: When should I NOT use RAG at all?

    When the knowledge is tiny and static (put it in the prompt), when the task needs no external facts (pure reasoning or transformation), and when the real problem is structured transactions — if the user needs the current account balance, that is a database query or a tool call, not a document search.

    Q: How do I stop a RAG system from answering questions it has no evidence for?

    Teach it to abstain. Instruct the model to answer only from context and to say so when the context is insufficient, evaluate faithfulness, and consider a corrective pattern (CRAG) that detects poor retrieval before generation. A system that says “I don’t have that in the knowledge base” is worth ten that improvise.

    Q: What’s the difference between CRAG and Self-RAG?

    Where the judgment lives. CRAG puts an external evaluator in the pipeline — any model can sit behind it. Self-RAG builds the judgment into the model itself through training with reflection tokens. CRAG is easier to adopt; Self-RAG is more integrated but requires the specialized model.

    Interview rapid-fire

    “Walk me through how you’d design a RAG system for [our documents].”

    Start with the naive baseline and say so. Then ask (or state assumptions) about corpus size, question types, exact-match needs, and cost of a wrong answer — and let those answers pull in advanced, hybrid, or corrective patterns one at a time, naming the failure each addition fixes. This structure — baseline, then failure-driven upgrades — is the strongest signal you can send.

    “Our RAG system hallucinates. What do you check first?”

    Whether the retrieved context contained the answer at all. Most “hallucination” in RAG is retrieval failure followed by the model filling the gap. Check retrieval quality on the failing questions before touching prompts or models.

    “Why not just use a bigger model?”

    A bigger model reasons better over the context it is given; it does not fix being given the wrong context, and it multiplies cost across every query. Architecture first, model size second.

    “How would you cut our RAG costs?”

    Retrieve less but better (reranking lets you shrink Top-K), cache frequent queries and embeddings, route simple questions to smaller models, and reserve agentic or long-context patterns for the query classes that demonstrably need them.

    The one-sentence version

    RAG is not a product you install; it is a set of decisions about how evidence reaches the model — and the right architecture is the simplest one whose failure modes you have actually observed and priced.

    Start simple. Measure. Add exactly the complexity your failures demand. That sentence will carry you through most interviews — and, not coincidentally, most production systems too.

    If this helped, subscribe to The Agentic Enterprise below — one practical AI architecture breakdown a month, written from production experience, no hype. And if you are preparing for interviews, the free GenAI Interview Question Bank on the Free Toolkits page goes deeper.

  • Building a Semantic Layer, Hands-On

    In the earlier piece on the semantic layer, I made the case: define each business metric once, and let every dashboard, tool, and AI agent read from it. This is the hands-on companion. We build one.

    What we’re building: a metrics layer for a single metric — revenue — that your BI tool, your dbt project, and an AI agent can all consume without disagreeing. By the end, “revenue” means one thing everywhere, it’s tested, and it’s served through an API.

    Step 1: Define the metric with a human, not in YAML

    The unsexy step that decides everything. Before touching code, get the business owner in a room (or a doc) and nail down:

    Name: revenue
    Definition: gross revenue, refunds excluded, recognized on order date
    Grain: one row per day per region
    Owner: who signs off when the number looks wrong

    Write this down where everyone can see it. Most metric disagreements I’ve seen weren’t technical — two teams with two definitions, both convinced theirs was “revenue.” The semantic layer doesn’t fix disagreement. It forces the conversation early, once, instead of late, forever.

    Step 2: Model it

    Here’s the shape of a semantic model in dbt’s MetricFlow format (adapt to your dbt version — the concepts transfer to any tool):

    semantic_models:
      - name: orders
        description: Order-level facts, one row per order line
        defaults:
          agg_time_dimension: ordered_at
        entities:
          - name: order_id
            type: primary
          - name: customer_id
            type: foreign
        dimensions:
          - name: ordered_at
            type: TIME
            type_params:
              time_granularity: day
          - name: region
            type: CATEGORICAL
        measures:
          - name: order_total
            agg: SUM
            expr: line_total
    
    metrics:
      - name: revenue
        description: Gross revenue, refunds excluded, recognized on order date
        type: SIMPLE
        type_params:
          measure: order_total

    Three things to notice. First, the measure (order_total) is the raw aggregation; the metric (revenue) is the business concept layered on top with its definition. Second, dimensions like region and ordered_at are what let every consumer slice the same metric the same way. Third, the description isn’t decoration — it’s the contract. When an AI agent reads this metric, the description is what keeps it from inventing its own interpretation.

    No dbt? A SQL view gets you 80% of the way:

    CREATE OR REPLACE VIEW marts.revenue_daily AS
    SELECT
      DATE_TRUNC('day', ordered_at) AS day,
      region,
      SUM(line_total) AS revenue
    FROM orders
    WHERE order_status != 'refunded'
    GROUP BY 1, 2;

    Same idea: one definition, one place, everyone reads from it.

    Step 3: Test it like production code

    Metrics without tests are rumors. At minimum:

    Sanity bounds: revenue is never negative; day-over-day change beyond some threshold pages someone.
    Grain checks: no duplicate day/region rows; no future dates.
    Reconciliation: the semantic layer’s revenue matches the finance system’s revenue within tolerance, on a schedule.

    In dbt, these are data tests on the underlying models plus a scheduled reconciliation query. The point isn’t the tooling — it’s the discipline. A metric nobody tests is a metric nobody trusts, and an untrusted metric gets forked: someone builds their own version in a spreadsheet, and you’re back to three definitions of revenue.

    Step 4: Serve it to everyone — including agents

    This is the step most teams skip, and it’s the whole point.

    Your BI tool connects to the semantic layer natively (most modern BI tools speak dbt’s Semantic Layer or query the views directly). But the second consumer — the AI agent — needs the same metrics through an API, not a dashboard. The agent should ask for “revenue by region for Q3” by metric name and get back a governed number, not write its own SQL against raw tables and reinvent the definition.

    That’s the real payoff: the agent stops hallucinating metrics because it stops computing them. It reads them.

    Step 5: Govern changes

    Metrics change. Tax rules change, refund policies change, someone acquires a company. The semantic layer needs change control like any production system:

    Versioning: metric definitions are versioned; breaking changes get a migration path, not a silent edit.
    Ownership: every metric has an owner who approves changes. No owner, no metric.
    Deprecation: old definitions get sunset with notice, not deleted on a Friday.

    Humans grumble at schema changes and adapt. Agents break silently. Versioning isn’t bureaucracy — it’s the difference between a controlled rollout and a fleet of agents confidently reporting last quarter’s definition.

    Five mistakes I see everywhere

    1. Defining metrics in the BI tool. Now your definition lives in one vendor’s dialect, invisible to everyone else — including your agents. The semantic layer belongs underneath the BI tool, not inside it.

    2. No owner per metric. A metric nobody owns is a metric nobody fixes. Assign ownership on day one.

    3. Grain ambiguity. Is revenue recognized on order date or ship date? If the model doesn’t say, every consumer guesses — differently.

    4. Skipping tests. “Trust me” is not a data quality strategy. Test the metric, reconcile it against finance, alert on drift.

    5. Letting teams fork definitions. The moment someone builds “revenue_v2_final_FINAL” in a spreadsheet, you’ve lost. Make the governed path the easy path: good docs, fast queries, one API.

    The payoff

    A working semantic layer is unglamorous. No demo has ever wowed a room with “consistent metric definitions.” But it’s the foundation everything else stands on: dashboards people trust, agents that don’t invent numbers, and executives who stop arguing about whose report is right.

    Build it once, define it once, test it, serve it to everyone. The iceberg below the waterline holds up the tip.


    — Jugal

  • The AI Engineering Iceberg: What It Really Takes to Ship AI to Production

    Anyone can build an AI demo. Connect an API, write a clever prompt, wrap it in a chat window — by Friday you have something that impresses a room. I’ve watched teams do it in a weekend.

    Then they try to put it in front of real users, and the iceberg shows up.

    Below the waterline of every AI demo sits roughly 90% of the actual engineering: the data pipelines, the retrieval tuning, the evals, the guardrails, the cost controls, the incident response. None of it is visible in the demo. All of it decides whether the thing survives contact with production.

    There’s a popular visual making the rounds — Jean Lee’s AI Engineering Iceberg — that captures this perfectly: a small tip above water (prompts, API calls, chatbots) and a massive submerged body of everything else. What follows is my version of what’s down there, drawn from years of shipping data and AI systems at enterprise scale.

    The visible tip

    Prompt engineering. Calling LLM APIs. Building chatbots.

    This is real work, and it’s where everyone starts. It’s also maybe 10% of a production system. The tip is the part you can learn in a weekend and demo on a Friday. Everything below takes the other 90% of the calendar — and nearly 100% of the budget that matters.

    The tip is also where most AI strategies stop. “We need an LLM strategy” usually means “we built a chatbot.” The organizations that get past this stage are the ones that ask what happens after the demo.

    Below the waterline: data

    Every production AI system I’ve seen fail failed on data first.

    Data pipelines — ingestion, cleaning, chunking, enrichment. The demo reads three PDFs. Production ingests thousands of documents in five formats, half of them scanned, with tables that break every parser you try.

    Retrieval engineering — hybrid search, reranking, metadata filtering. “RAG basics” is chatting with documents. Retrieval engineering is making the right document win, every time, when the corpus is messy and the questions are adversarial. This is where most RAG pilots quietly die: the retrieval looks fine on ten test queries and falls apart on ten thousand real ones.

    If your data foundation was built for dashboards, your agents are standing on a surface designed for human eyes. I wrote about this at length in the AI-ready data field guide — the short version is that data good enough for humans is not automatically good enough for machines.

    Below the waterline: quality

    Model evaluation — quality, accuracy, relevance, task success. The demo has no evals; it has a founder nodding at outputs. Production needs golden datasets, regression suites, and a definition of “good” that survives contact with edge cases.

    Observability — tracing prompts, tools, tokens, failures. When a user reports a wrong answer on Tuesday, you need to replay exactly what the system saw, retrieved, and decided. Without traces, debugging an AI system is archaeology.

    If you can’t measure it, you can’t ship it — you’re just hoping.

    Below the waterline: systems

    Agent orchestration — tools, workflows, memory, multi-agent coordination. The demo calls one model. Production orchestrates dozens of moving parts that fail independently and need to fail gracefully.

    Tool calling — schemas, permissions, retries, validation. Giving an LLM a tool is the tip. Making that tool call reliable, permissioned, idempotent, and auditable is the iceberg.

    Structured outputs — reliable JSON, parsing, schema enforcement. Downstream systems don’t consume vibes. Every handoff between the model and your software needs a contract.

    Reliability engineering — fallbacks, retries, timeouts, error handling. Models go down, rate limits hit, latency spikes. Production AI needs the same resilience discipline as any distributed system, because it is one.

    Below the waterline: operations

    This is the layer nobody demos and everybody pays for.

    Cost and latency optimization — token budgets, smaller models, smart routing, caching, batching, streaming. The pilot costs $200. Production costs $200,000. Nobody budgets for it until the first invoice arrives.

    CI/CD for AI — testing prompts, workflows, models, deployments. Prompts are code now: versioned, reviewed, tested, rolled back.

    Production monitoring — drift, quality degradation, usage, incidents. Models don’t stay good by themselves. Data drifts, user behavior shifts, and yesterday’s eval scores quietly decay.

    Security, governance, and human-in-the-loop — authentication, secrets, prompt-injection defenses, data governance, approvals and escalation workflows. Mapped to something like the NIST AI Risk Management Framework, this is the layer that keeps you out of the news.

    What this means for leaders

    Three implications if you’re funding or hiring for AI:

    Budget for the iceberg, not the tip. If your AI budget covers models and prompts, you’ve budgeted for 10% of the system. The teams that blow up do so in the submerged 90% — usually on data and evals they never planned for.

    Hire for what’s below the waterline. Anyone can demo. In interviews, skip the chatbot questions and ask about the submerged part: how they’d debug wrong answers in production, cut inference cost 10x, design an eval harness, or make AI writes to a CRM safe. The answers reveal who’s shipped and who’s watched tutorials.

    Don’t let the pilot set the architecture. Two-week pilots prove the tip. That’s their job. But plan the production architecture — retrieval, evals, guardrails, cost controls — from day one, or you’ll rebuild everything the pilot validated.

    The demo is the tip

    None of this is an argument against demos. Demos are how you learn, get funding, and build momentum. Just don’t mistake the tip for the iceberg.

    The organizations shipping AI that actually works all learned the same lesson, usually the expensive way: production is the iceberg. Build for what’s below the waterline, and the tip takes care of itself.


    — Jugal

  • Dual-Purpose Data: Designing Foundations for Humans and Agents

    Every data foundation built in the last decade was designed for one consumer: people. Analysts, executives, data scientists — humans who look at dashboards, ask questions, and apply judgment. That foundation is about to get a second consumer that behaves nothing like the first: AI agents.

    Same data. Two consumers. Radically different needs. The architects who design for both, deliberately, will build the foundations that last. The ones who bolt agents onto human-shaped data will spend the next three years firefighting.


    The two consumers

    Humans and agents consume data in fundamentally different ways.

    A human looks at a dashboard, notices something odd, drills down, asks a colleague, and applies context the data doesn’t contain. Humans are fault-tolerant. They squint.

    An agent does none of that. It reads structured output, follows its instructions, and acts — no squinting, no “this doesn’t look right,” no hallway conversation to resolve ambiguity. It’s fast, tireless, and completely literal. Every gap a human would bridge with judgment becomes a gap the agent falls into.

    This isn’t an argument against agents. It’s the design constraint that changes everything: data good enough for humans is not automatically good enough for machines.


    What agents need that dashboards don’t

    Designing for agents surfaces requirements that human-centric foundations never had to meet:

    Freshness with guarantees, not vibes. A human tolerates “data refreshed nightly, mostly.” An agent acting on a stale customer record needs to know exactly how stale, and what it can and can’t do about it. Freshness becomes a contract with SLAs, not a footnote.

    Structure over presentation. Dashboards are forgiving — a human reads around a null, interprets a weird format, ignores the extra column. Agents need clean schemas, typed fields, explicit nulls, and documented enumerations. The pretty chart hides sins the API can’t.

    Permissions at the row, not the dashboard. Human access control often lives at the report or dashboard level. Agents need row-level, attribute-level enforcement — because the agent will happily read the salary column the dashboard hid, and then mention it in a summary. If the permission isn’t in the data layer, it doesn’t exist for agents.

    Grounding, not just retrieval. Humans bring world knowledge to ambiguous data. Agents need explicit grounding: definitions, lineage, quality verdicts, and business rules attached to the data itself. An agent that can’t see why a number is what it is will invent a why.

    If your access control lives in the dashboard, your agents are already reading the columns you hid.


    Design once, serve twice

    The good news: you don’t need two foundations. You need one foundation designed with both consumers in mind — and that’s a better foundation for humans too.

    The pattern is a layered architecture with a clean contract between layers. Raw ingestion at the bottom, governed and modeled in the middle, and serving layers on top — one serving humans through BI, one serving machines through APIs and agent tooling. Same governed core, different doors.

    The discipline is in the middle layer. Every dataset that serves both consumers needs: a schema agents can parse without guessing, quality verdicts a machine can read programmatically, lineage an agent can traverse, access policies enforced at the data layer, and semantic definitions shared with the human side. Build this once and both consumers benefit. Skip it and you’ll build it twice — once in panic, once properly.


    Governance for both

    Governance was already hard with one consumer. Two consumers with different failure modes makes it harder — and more important.

    The shift is from governance-as-documentation to governance-as-execution. Policies can’t live in PDFs when the consumer is a machine; they have to be enforced in the platform. Access rules, quality gates, retention policies, consent flags — all machine-readable, all enforced at query time, all auditable. The audit trail matters doubly now: when an agent acts on data, you need to prove what it saw, what rules applied, and why it was allowed to see it.

    Governance that lives in a PDF is governance for humans. Agents need governance in the platform.

    This is also where stewardship evolves. Data stewards used to answer human questions about data. Now they curate the machine-readable context agents depend on: definitions, quality rules, escalation paths for ambiguous cases. The steward’s audience doubled.


    The operating model

    Dual-purpose data needs a dual-purpose operating model. A few things change in practice:

    Quality becomes a production concern, not an analytics concern. When agents act on data in real time, a quality failure is an operational incident, not a reporting footnote. Data quality SLAs, monitoring, and incident response move from “nice to have” to “the thing that keeps agents from embarrassing you.”

    The catalog becomes an agent’s first stop. Data discovery for humans is browsing. For agents, the catalog is infrastructure — machine-readable metadata, searchable by capability, with quality and access signals attached. If your catalog is a website humans click through, agents can’t use it. If it’s an API with rich metadata, both can.

    Versioning gets serious. Humans adapt to schema changes with a grumble and a rewritten query. Agents break. Every schema change, every definition change, every deprecation needs versioning and notice — the same discipline APIs have had for years, now applied to data.


    The unfair advantage

    Here’s the thing most organizations miss: designing for agents makes the human experience better too. Cleaner schemas, enforced quality, real access control, versioned definitions — every one of these is something analysts have wanted for years. The agent is just the forcing function that finally makes it non-negotiable.

    The enterprises that build dual-purpose foundations now will have something rare: data their people trust and their machines can act on. Everyone else will discover — usually via an incident — that their foundation was built for exactly one consumer, and the second one doesn’t squint.

    Design for both. The humans will thank you. The agents won’t — but they won’t embarrass you either, and right now, that’s the higher bar.


    — Jugal

  • The Semantic Layer: The Most Underrated Architecture in Enterprise Data

    Ask three teams in your company to define “active customer” and you’ll get four answers. Marketing counts anyone who opened an email this quarter. Finance counts paying accounts. Product counts monthly active users. And the executive dashboard shows a fifth number that nobody can explain but everyone quotes.

    This is the metrics mess, and it’s the most expensive problem in enterprise data that nobody’s job title mentions. Billions get spent on lakes, warehouses, and pipelines, and then the business argues about what the numbers mean. The technology worked. The meaning didn’t.

    The fix has a name, and it’s the most underrated architecture in the data world: the semantic layer.


    What a semantic layer actually is

    A semantic layer is a single, governed definition of every business metric and dimension, sitting between the raw data and everyone who consumes it. “Revenue” is defined once — the logic, the filters, the grain, the edge cases — and every dashboard, report, API, and AI agent uses that definition.

    Not a wiki page describing revenue. Not a Confluence doc everyone ignores. The actual logic, executable, versioned, and shared. When someone asks “how is revenue calculated?”, the answer is the semantic layer, and it’s the same answer everywhere.

    If your metrics are defined in forty dashboards instead of one place, you don’t have metrics. You have opinions with charts.


    Why the old answers failed

    We’ve tried to solve this before. The data warehouse was supposed to be the single version of the truth — but the logic leaked into BI tools, dbt models, spreadsheets, and one-off SQL. The “metrics layer” wave of a few years ago got the idea right but often landed as yet another tool to adopt rather than a discipline to enforce.

    The failure pattern is always the same: the definitions live wherever it’s convenient in the moment, and convenience compounds into chaos. A semantic layer only works when it’s the only place metric logic is allowed to live. That’s a governance decision before it’s a technology decision.


    Conceptual, logical, physical: the modeling discipline underneath

    Under every good semantic layer is old-fashioned data modeling discipline — the kind that fell out of fashion and is now quietly saving AI projects.

    Conceptual modeling answers “what are the things we care about and how do they relate?” — customers, orders, products, the entities and relationships, in business language. Logical modeling adds structure: attributes, keys, grain, the rules that hold regardless of technology. Physical modeling is the implementation: tables, partitions, indexes, the performance reality.

    Most organizations skipped straight to physical — built the tables, worried about meaning later. Later never came. The semantic layer forces the discipline back in: you can’t define “revenue” once, governably, without agreeing on what a customer is and what counts as an order. The modeling conversation is the alignment conversation.


    The business glossary as a contract

    The glossary is the semantic layer’s public face: every metric and dimension, defined in plain language, with an owner, a lineage trail, and a version history. But the key word is contract. A glossary that nobody is obligated to use is documentation. A glossary wired into the platform — where the BI tool pulls definitions from it, where data contracts reference it, where new pipelines must map to it — is infrastructure.

    The test is simple: can a new analyst find the definition of a metric, see who owns it, trace it to source, and trust it — in an afternoon? If yes, you have a contract. If it takes a quarter and five Slack threads, you have a wiki.


    The semantic layer and AI

    Here’s what makes this urgent instead of merely important: AI agents need shared meaning more desperately than humans do.

    A human analyst who sees a weird revenue number will squint, ask around, and figure out the definition drift. An agent won’t. It will take the number, act on it, and compound the error into decisions. Worse, agents from different teams will each invent their own interpretation of the same metric — automated definition drift, at machine speed.

    The semantic layer is what grounds AI in shared business meaning. Retrieval gives agents facts; the semantic layer gives them definitions. An agent that queries “revenue” through the semantic layer gets the governed answer. One that writes its own SQL gets whatever it feels like.

    In the agentic era, the semantic layer isn’t a BI convenience. It’s the difference between grounded AI and confident fiction.


    Where to start

    Don’t boil the ocean. Pick the ten metrics the business argues about most — revenue, active customers, churn, cost, whatever sparks the weekly debate — and define them once, in one place, with owners and lineage. Wire one BI tool to consume them. Show the before and after: same question, one answer.

    Then expand. The goal isn’t a perfect enterprise ontology on day one; it’s breaking the pattern where every new dashboard invents its own definitions. Ten governed metrics, actually used, beat a hundred documented ones nobody trusts.

    The enterprises that get this right will discover something their competitors won’t: when the AI era demands grounded, consistent, explainable answers, they’ll already have the layer that provides them. Everyone else will be retrofitting meaning onto chaos — while their agents confidently report five different revenues.

    The work is unglamorous. The payoff isn’t. Define it once.


    — Jugal