Author: Jugal Shah

  • R-I-S-K-S: The 5-Dimension Framework for AI Risk Management

    Most organizations treat AI risk as a compliance checkbox — a review board, a form, a sign-off. That is backwards.

    I believe AI risk management should be embedded into the enterprise architecture and the delivery lifecycle, not treated as a separate compliance activity. When risk controls live inside the architecture, teams move fast by default and slow down only where it matters.

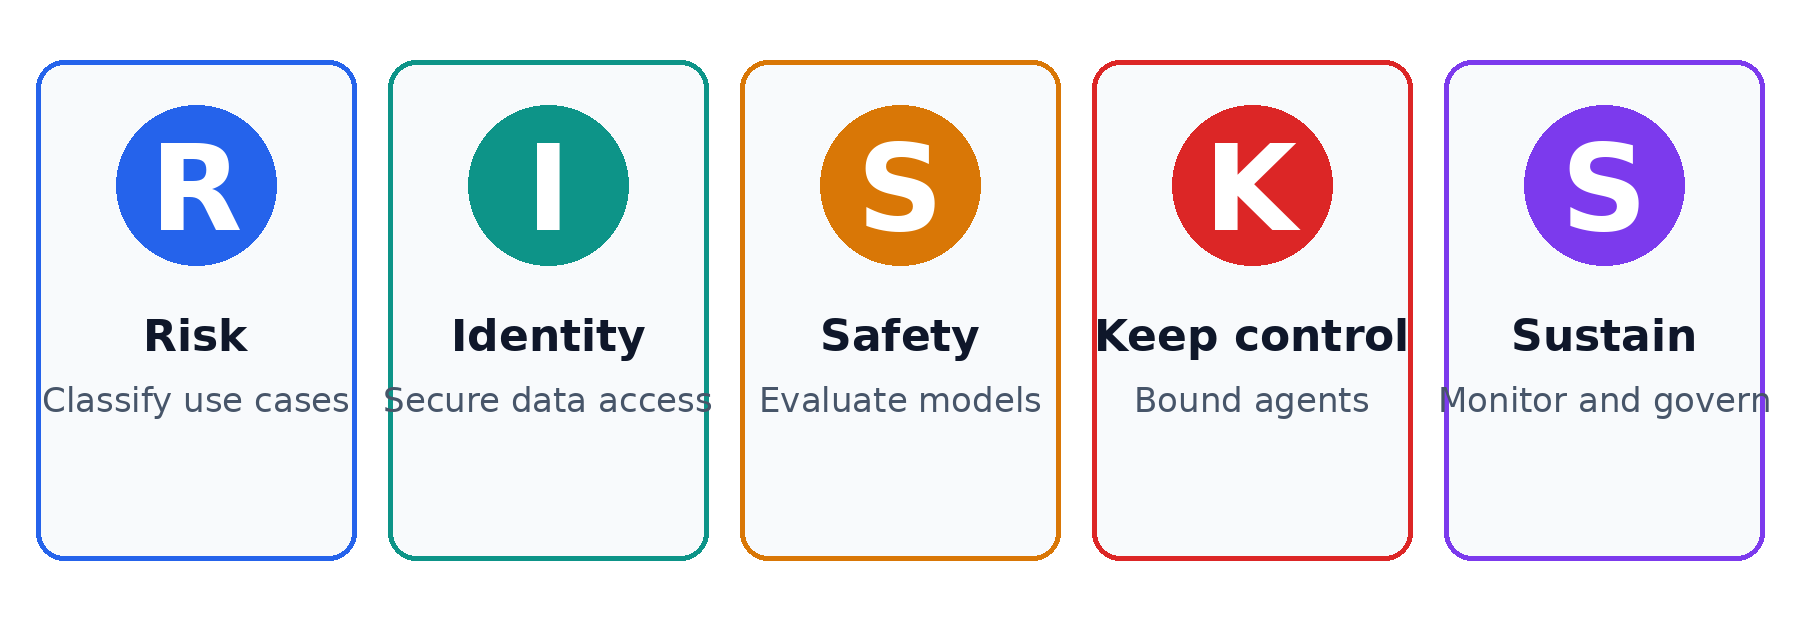
    Here is the whole framework in five letters: R-I-S-K-S.
    The 5 dimensions of AI risk management

    R — Risk: classify use cases

    Not every AI use case carries the same risk. A knowledge assistant summarizing internal policies is not the same as an agent recommending manufacturing quality decisions or initiating financial transactions.

    Classify every application on four axes: data sensitivity, business criticality, autonomy, and regulatory impact. The classification decides everything downstream — which controls apply, who reviews, how fast it ships.

    I — Identity: secure data access

    Trusted data access, data classification, least-privilege permissions, encryption, lineage, auditability.

    For RAG applications, one rule matters most: enforce document-level authorization before retrieval reaches the LLM. The model should never see what the user is not entitled to see.

    S — Safety: evaluate models

    Evaluation frameworks that measure accuracy, hallucinations, bias, groundedness, and robustness — where each is relevant.

    These evaluations belong in CI/CD release gates, backed by versioned datasets and ongoing production monitoring. If you cannot measure it, you cannot ship it.

    K — Keep control: bound agents

    Moving from AI-generated recommendations to agents taking actions is where risk jumps. Deterministic orchestration for business-critical workflows. Tools restricted through explicit authorization. Human approval required for high-impact decisions.

    Agents operate within clearly defined boundaries. Outside those boundaries, the agent does not exist.

    S — Sustain: monitor and govern

    AI observability. Incident response. Model and prompt versioning. Rollback capabilities. Vendor risk management. Clear accountability across architecture, security, compliance, and business owners.

    This is the dimension that keeps the other four honest in production.

    How to apply it

    Implement these controls through a risk-based governance framework — not the same review process for every application. Low-risk use cases move fast. High-impact ones get the full treatment.

    The objective: an environment where business teams innovate quickly, and security, compliance, reliability, and accountability are built into the architecture from day one.

    My philosophy, in one line: AI innovation and AI governance should not compete. The right architecture enables both. Move quickly where the risk is low, apply stronger controls where the impact is high, and always preserve human accountability for consequential decisions.

    The framework to memorize: R-I-S-K-S.
  • The Agent Cookbook: 12 Patterns That Keep AI Agents Safe in Production

    Everyone is building agents. Almost nobody ships the safety layer.

    Demos are easy. Production is where agents approve the wrong thing, loop until the invoice arrives, call tools they were never meant to touch, and fail silently at 2 AM. The gap between a demo agent and a production agent is not a better model. It is a set of small, boring, essential patterns around the model.

    So I built them. The Agent Cookbook is an open-source repo of 12 production patterns for agentic AI — each one a small, runnable, copy-paste Python example. No framework. No API keys. Each pattern runs locally in under five minutes.

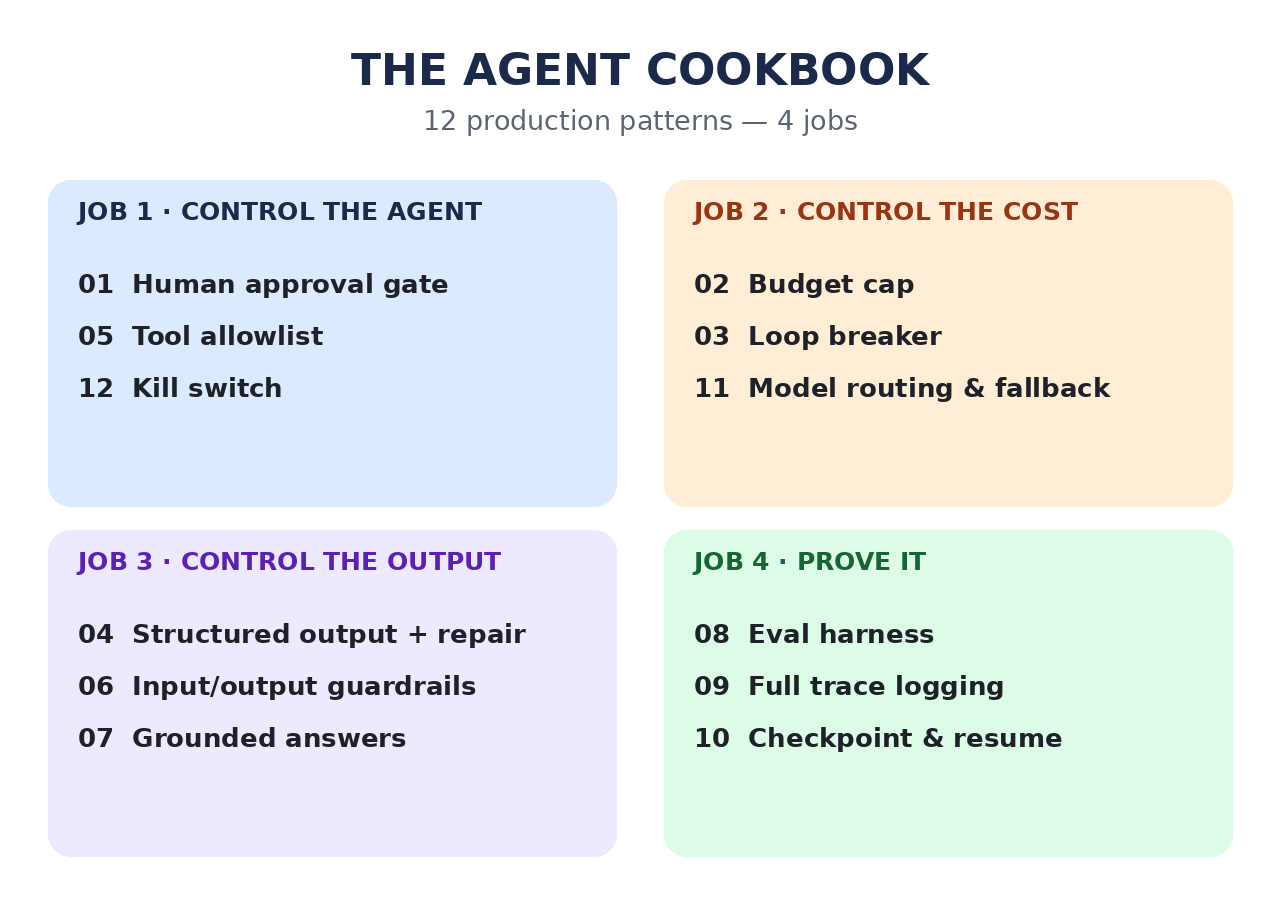
    Here is the whole cookbook on one page — the 12 patterns do four jobs.

    Diagram: The Agent Cookbook's 12 patterns grouped into four jobs — control what the agent can do, control what it can spend, control what it can say, and prove what it did.

    Job 1: Control what the agent can do

    01 — Human approval gate. The agent proposes; a human disposes. Anything irreversible waits for a yes.
    05 — Tool allowlist. Least privilege for agents: the agent can only call the tools it is explicitly given. Everything else does not exist.
    12 — Kill switch. One flag that stops the agent now — not after the deploy, not after the meeting. Now.

    Job 2: Control what the agent can spend

    02 — Budget cap. A hard ceiling on tokens and cost per run. When the cap is hit, the agent stops, cleanly, with a reason.
    03 — Loop breaker. Agents love loops. This pattern counts, detects the spin, and breaks out before the bill does.
    11 — Model routing & fallback. Cheap model first, strong model when it matters, and a fallback path when the primary model fails.

    Job 3: Control what the agent can say

    04 — Structured output with repair. Demand a schema. When the output does not parse, repair it instead of crashing on it.
    06 — Input/output guardrails. Check what goes in and what comes out. Both directions. Every time.
    07 — Grounded answers. The agent answers from retrieved evidence — and says “I don’t know” when the evidence is not there.

    Job 4: Prove what the agent did

    08 — Eval harness. A small, repeatable test set the agent must pass before any change ships.
    09 — Full trace logging. Every step, tool call, and decision recorded. When someone asks “why did the agent do that?”, you have the receipt.
    10 — Checkpoint & resume. Long runs save state as they go. A crash becomes a pause, not a restart from zero.

    How to use it

    Clone the repo, pick the pattern your agent is missing, and run it — each folder under patterns/ has its own README and a single framework-free Python file:

    github.com/simplyjug/agent-cookbook

    The patterns are deliberately small. Copy one into your codebase, adapt it, and your agent gets a little more production-shaped. Stack all twelve and you have the safety layer most agent projects skip — the layer that decides whether your agent survives its first month in production.

    The repo is MIT licensed. If it saves you from one 2 AM incident, star it so the next engineer finds it — and subscribe below for the deep-dives: I will be taking individual patterns apart, one at a time, here on aiDeeva.

    The Agent Cookbook is maintained by Jugal Shah. Companion reading: The Agentic Architecture Framework — the method these patterns plug into.

  • SQL vs NoSQL: Two Ways to Store Data, One Decision to Get Right

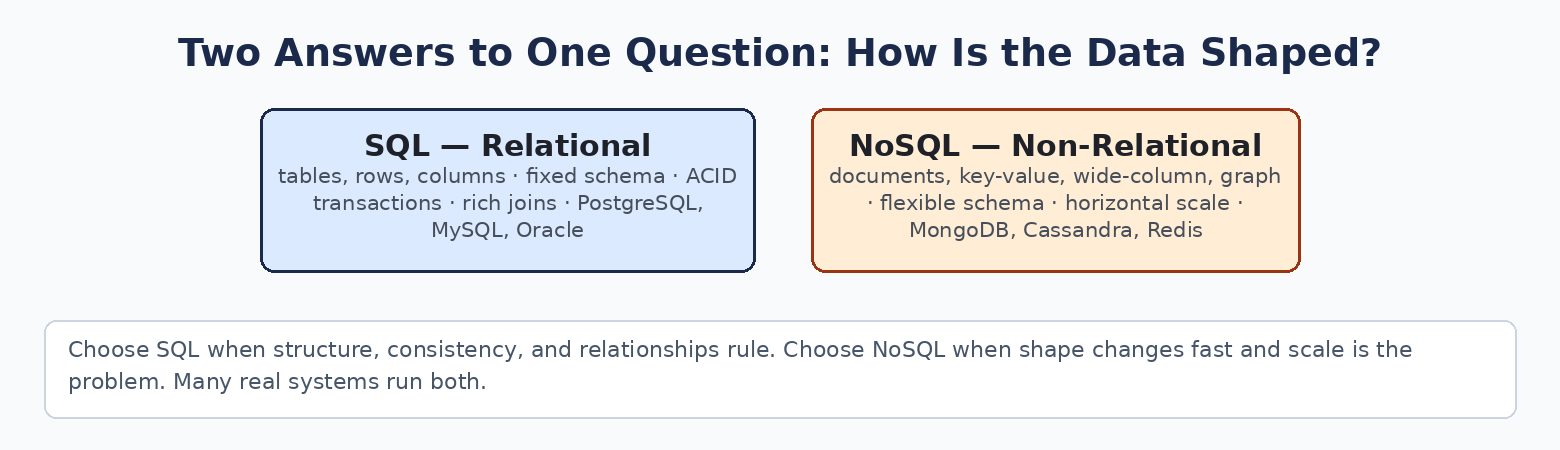
    One database choice, made in week one, quietly shapes a system for years. SQL and NoSQL are not rivals and neither is “newer and better” — they are two different answers to one question: how is your data shaped, and how will it be asked for?

    SQL vs NoSQL comparison

    The two shapes

    SQL (relational). Data in tables of rows and columns, with a fixed schema defined up front and relationships enforced by the database itself — a Users table, an Orders table pointing at it, a Payments table pointing at orders. Strong consistency and ACID transactions are the native language. Examples: PostgreSQL, MySQL, Oracle.

    NoSQL (non-relational). Data in flexible forms — documents (JSON-like records), key-value pairs, wide columns, or graphs. The schema can evolve as the product does, and the systems are designed for horizontal scaling from the start. Examples: MongoDB, Cassandra, Redis.

    Side by side

    FeatureSQLNoSQL
    Data modelTables and relationsDocuments, key-value, wide-column, graph
    SchemaFixed, predefinedDynamic, flexible
    ScalingVertical first, scale-out possibleHorizontal by design
    ConsistencyStrongOften eventual / tunable
    TransactionsStrong ACID supportVaries by system
    QueriesRich joins and a full query languageOptimized for known access patterns
    FlexibilityLowerHigh
    Best forStructured transactional systemsLarge-scale, distributed, fast-changing apps

    The same question in both worlds

    SQL joins at query time:

    SELECT users.name, orders.total
    FROM users
    JOIN orders ON users.id = orders.user_id;

    NoSQL fetches the record shaped for the question:

    db.orders.find({ status: "paid"})

    That contrast is the decision. SQL stores data normalized and assembles answers on demand — any question, answered by joins. NoSQL stores data pre-assembled for the questions you already know — blindingly fast for those, awkward for new ones.

    The analogy

    SQL is a spreadsheet with strict columns and rules: every row fits the structure, and the structure guarantees the truth. NoSQL is a box of index cards: each card holds whatever that record needs, in whatever shape — perfect for millions of different records, as long as you know how you will look them up.

    When to use what

    SQL — financial systems, order management, reporting and BI, anything where data integrity, complex relationships, and “the numbers must agree” rule. Banking runs on SQL for a reason.

    NoSQL — rapidly evolving products, high-traffic systems, large distributed workloads, semi-structured data: social feeds, content platforms, IoT streams, real-time analytics.

    And the grown-up answer: many real systems run both — SQL for the transactional core where correctness is law, NoSQL beside it where scale and flexibility matter more. The choice is per workload, not per company.

    The bottom line

    Choose SQL when structure, consistency, and relationships matter most. Choose NoSQL when the shape changes fast and scale is the problem actually in front of you. Get the data shape right, and the rest of the architecture gets easier.

    Data decisions are the deepest layer of every system — the free toolkits map what sits on top of them.

  • The System Design Staircase: What to Learn, In What Order

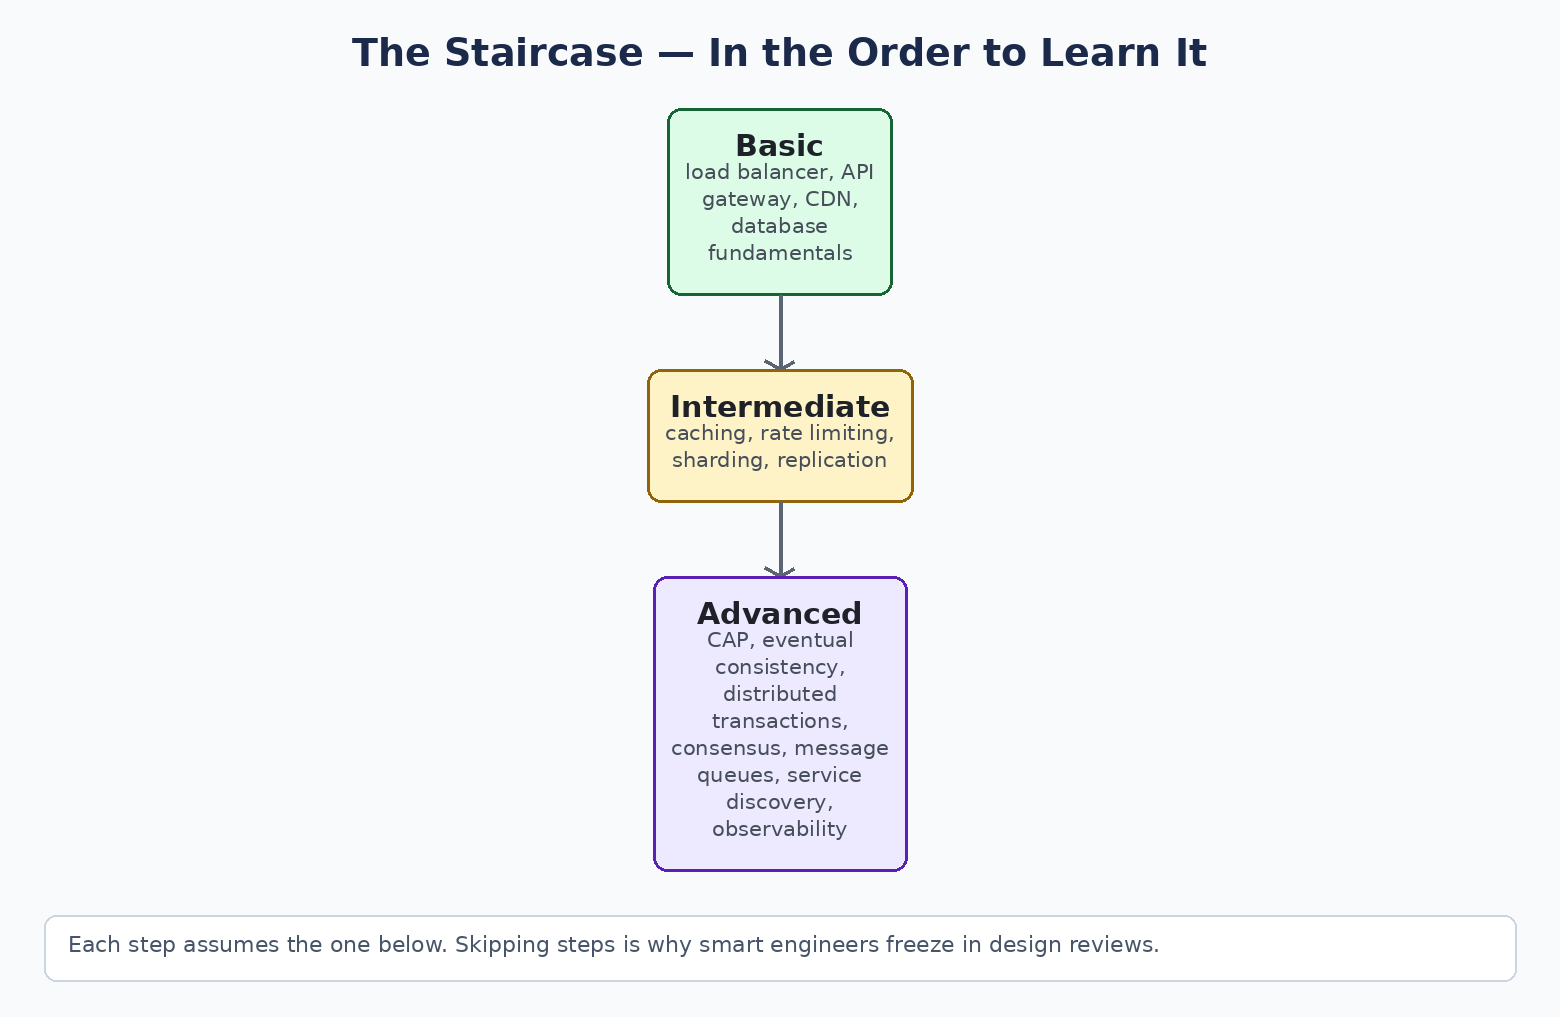
    System design feels overwhelming for one reason: people try to learn it from the top step. Consensus algorithms before load balancers. Distributed transactions before databases. The knowledge is a staircase, not a pile — each step assumes the one below it, and climbing in order turns a scary subject into a sequence of small, obvious ones.

    The system design staircase: basic, intermediate, advanced

    Step 1: Basic — how one system serves users

    Load Balancer. One front door that distributes incoming traffic across servers, so no single machine is the ceiling. (NGINX, AWS ELB.)

    API Gateway. The single entry point for client requests: routing, authentication, and rate limiting handled in one place instead of inside every service. (Kong, AWS API Gateway.)

    Content Delivery Network (CDN). Static assets copied to servers near the user, so a page in Texas does not wait on a disk in Virginia. (Cloudflare, Akamai.)

    Database Fundamentals. Where structured data lives — SQL (MySQL, PostgreSQL) and NoSQL (MongoDB) — and how it is queried. Everything above this step exists to protect or feed the database.

    Master these four and you can design a system that serves real users. Most internal tools never need more.

    Step 2: Intermediate — how a system grows

    Caching. Keep hot data in memory so the database stops answering the same question a million times a day. (Redis, Memcached.)

    Rate Limiting. Cap requests per user or app, so growth — or abuse — cannot take the system down with enthusiasm.

    Database Sharding. Split a dataset across machines, by user ID or region, when one database honestly cannot hold or serve it all.

    Replication. Copy data across servers for high availability and disaster recovery — the master–slave setups that keep reads fast and data alive.

    This step is where most production systems live. If Step 1 is “working,” Step 2 is “working at ten times the traffic.”

    Step 3: Advanced — how systems agree, survive, and stay honest

    CAP Theorem. During a network partition, choose consistency or availability. The trade-off that defines distributed systems.

    Eventual Consistency. The relaxation of CAP: all nodes will agree eventually, just not instantly. (DynamoDB and most planet-scale systems.)

    Distributed Transactions. Keeping an operation atomic across services and databases — coordination protocols like 2PC, and patterns like SAGA when 2PC does not fit.

    Consensus Algorithms. How distributed nodes agree on anything — leader, value, state — when some of them are lying dead. (Paxos, Raft; inside etcd and ZooKeeper.)

    Message Queues. Decoupling services with asynchronous communication, so a slow consumer never blocks a fast producer. (RabbitMQ, Kafka.)

    Service Discovery. In environments where services appear, disappear, and move, something must keep the phone book. (Consul, Eureka.)

    System Observability. Monitoring, logging, and tracing — knowing the system’s health from the outside before your users tell you from the inside. (Prometheus, Grafana, Jaeger.)

    The bottom line

    Basic serves users, intermediate survives growth, advanced survives failure and disagreement. Learn — and interview, and design — in that order, and you will never freeze in a design review again.

    Climbing the staircase? The free toolkits collect the reference posters for each step.

  • 12 Kafka Concepts That Explain Real-Time Data Engineering

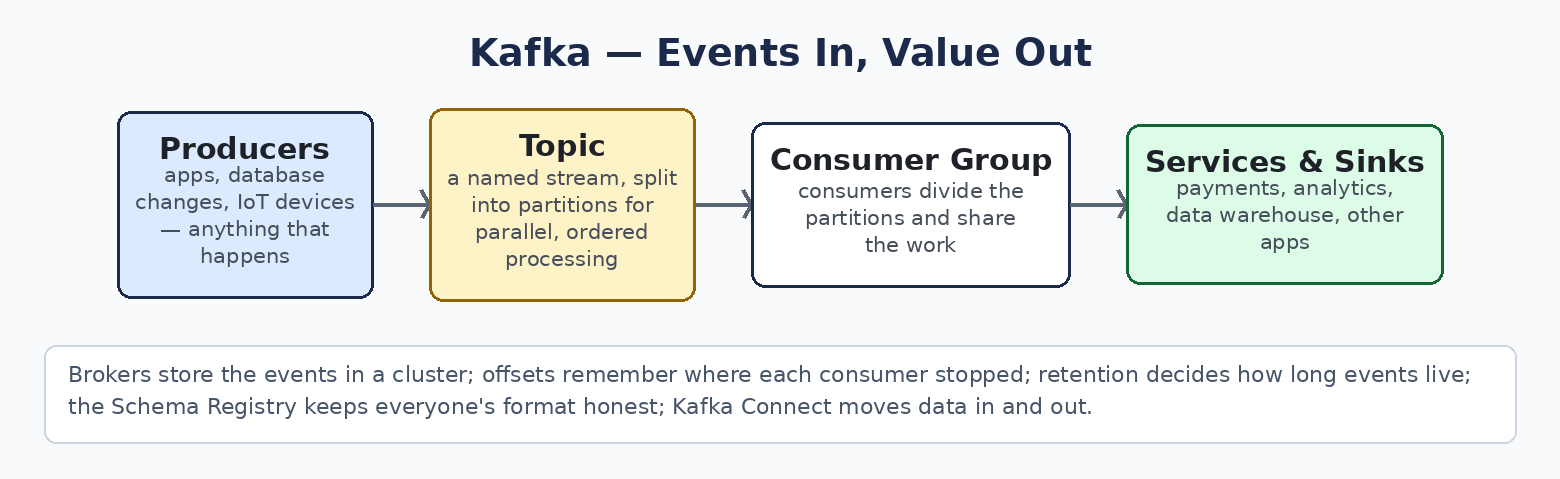
    Every food order, cab ride, payment, and delivery tracking screen you have ever watched was powered by events moving between systems. Kafka is the backbone most of those systems chose. Twelve concepts explain nearly all of it — and they build on each other in order.

    Kafka flow: producers, topics, consumer groups, services

    1. Producer. Anything that creates events: an app, a database change, an IoT sensor. A producer’s whole job is to fire events into Kafka, continuously, and move on — it never waits for whoever will use them.

    2. Topic. A named stream of related events — orders, payments, clicks. Topics are how Kafka organizes the firehose into channels with meaning.

    3. Partition. Each topic is split into partitions — parallel lanes. Partitions are where Kafka’s scale comes from (many consumers can read different lanes at once) and where ordering lives: events are ordered within a partition, not across the whole topic.

    4. Consumer. A service that reads events from topics and does work with them — updates inventory, sends the notification, writes to the warehouse.

    5. Consumer Group. Consumers working as a team. Kafka divides the topic’s partitions among the group’s members, so adding consumers adds parallel processing — up to the number of partitions, which is why partition count is a design decision, not a detail.

    6. Broker. A Kafka server. It receives events from producers, stores them, and serves them to consumers.

    7. Cluster. Many brokers working as one system. The cluster is what gives Kafka its scale (spread the load) and its resilience (survive losing machines).

    8. Offset. A bookmark. Every event in a partition has a position number, and each consumer group remembers its offset — where it stopped reading. Crash, restart, redeploy: the consumer resumes from its offset instead of starting over or losing events.

    9. Replication. Partitions are copied across brokers. If the broker holding a partition dies, a replica takes over and no data is lost. Replication is the difference between “event streaming” and “event streaming you can run a bank on.”

    10. Retention. Kafka does not delete an event after it is read. It keeps events for a configured time (or size) — seven days, say — so a new consumer can replay history, and a broken one can catch up. This single property separates Kafka from ordinary message queues.

    11. Schema Registry. The contract office. Producers and consumers register the exact format of their events, so a producer cannot silently change a field and break fifty downstream consumers at 3 AM.

    12. Kafka Connect. Prebuilt bridges that move data between Kafka and the outside world — databases in, warehouses and SaaS apps out — without hand-written producer and consumer code for every source and sink.

    The one-sentence version

    Producers write events into partitioned topics stored across a replicated cluster of brokers; consumer groups read them in parallel, track their place with offsets, keep them as long as retention allows, and trust the Schema Registry and Connect to keep the whole ecosystem honest and connected.

    Remember that sentence and you understand Kafka well enough to design with it. Everything else is tuning.

    Streaming is one layer of the modern data stack — the free toolkits map the rest.