Category: Data Engineering

  • SQL vs NoSQL: Two Ways to Store Data, One Decision to Get Right

    One database choice, made in week one, quietly shapes a system for years. SQL and NoSQL are not rivals and neither is “newer and better” — they are two different answers to one question: how is your data shaped, and how will it be asked for?
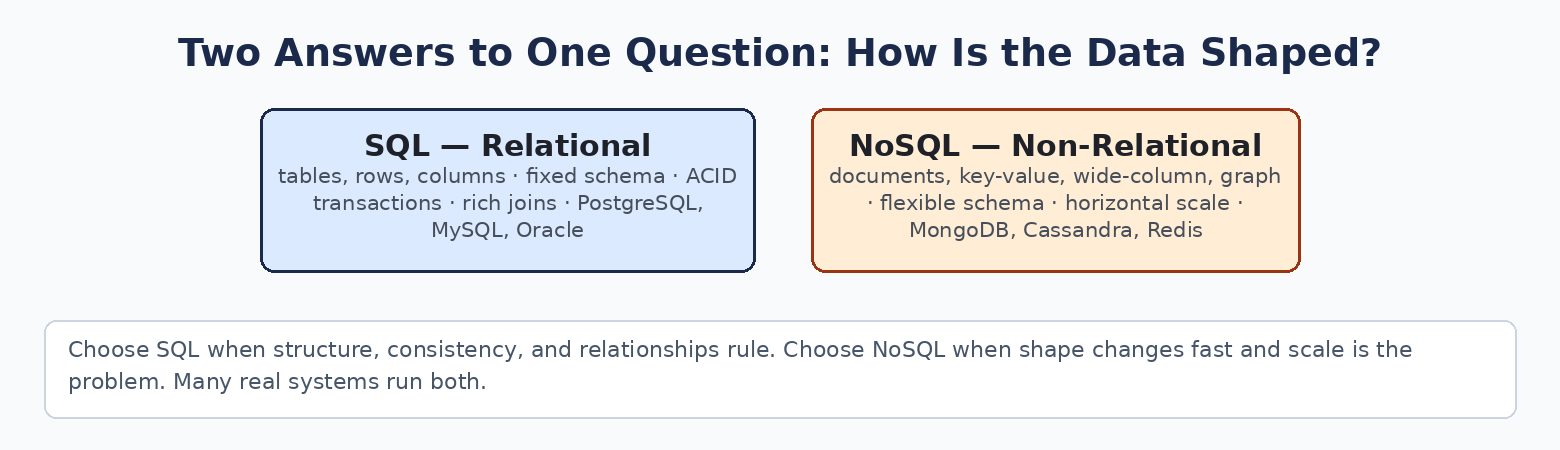
    SQL vs NoSQL comparison

    The two shapes

    SQL (relational). Data in tables of rows and columns, with a fixed schema defined up front and relationships enforced by the database itself — a Users table, an Orders table pointing at it, a Payments table pointing at orders. Strong consistency and ACID transactions are the native language. Examples: PostgreSQL, MySQL, Oracle.

    NoSQL (non-relational). Data in flexible forms — documents (JSON-like records), key-value pairs, wide columns, or graphs. The schema can evolve as the product does, and the systems are designed for horizontal scaling from the start. Examples: MongoDB, Cassandra, Redis.

    Side by side

    FeatureSQLNoSQL
    Data modelTables and relationsDocuments, key-value, wide-column, graph
    SchemaFixed, predefinedDynamic, flexible
    ScalingVertical first, scale-out possibleHorizontal by design
    ConsistencyStrongOften eventual / tunable
    TransactionsStrong ACID supportVaries by system
    QueriesRich joins and a full query languageOptimized for known access patterns
    FlexibilityLowerHigh
    Best forStructured transactional systemsLarge-scale, distributed, fast-changing apps

    The same question in both worlds

    SQL joins at query time:

    SELECT users.name, orders.total
    FROM users
    JOIN orders ON users.id = orders.user_id;

    NoSQL fetches the record shaped for the question:

    db.orders.find({ status: "paid"})

    That contrast is the decision. SQL stores data normalized and assembles answers on demand — any question, answered by joins. NoSQL stores data pre-assembled for the questions you already know — blindingly fast for those, awkward for new ones.

    The analogy

    SQL is a spreadsheet with strict columns and rules: every row fits the structure, and the structure guarantees the truth. NoSQL is a box of index cards: each card holds whatever that record needs, in whatever shape — perfect for millions of different records, as long as you know how you will look them up.

    When to use what

    SQL — financial systems, order management, reporting and BI, anything where data integrity, complex relationships, and “the numbers must agree” rule. Banking runs on SQL for a reason.

    NoSQL — rapidly evolving products, high-traffic systems, large distributed workloads, semi-structured data: social feeds, content platforms, IoT streams, real-time analytics.

    And the grown-up answer: many real systems run both — SQL for the transactional core where correctness is law, NoSQL beside it where scale and flexibility matter more. The choice is per workload, not per company.

    The bottom line

    Choose SQL when structure, consistency, and relationships matter most. Choose NoSQL when the shape changes fast and scale is the problem actually in front of you. Get the data shape right, and the rest of the architecture gets easier.

    Data decisions are the deepest layer of every system — the free toolkits map what sits on top of them.
  • The System Design Staircase: What to Learn, In What Order

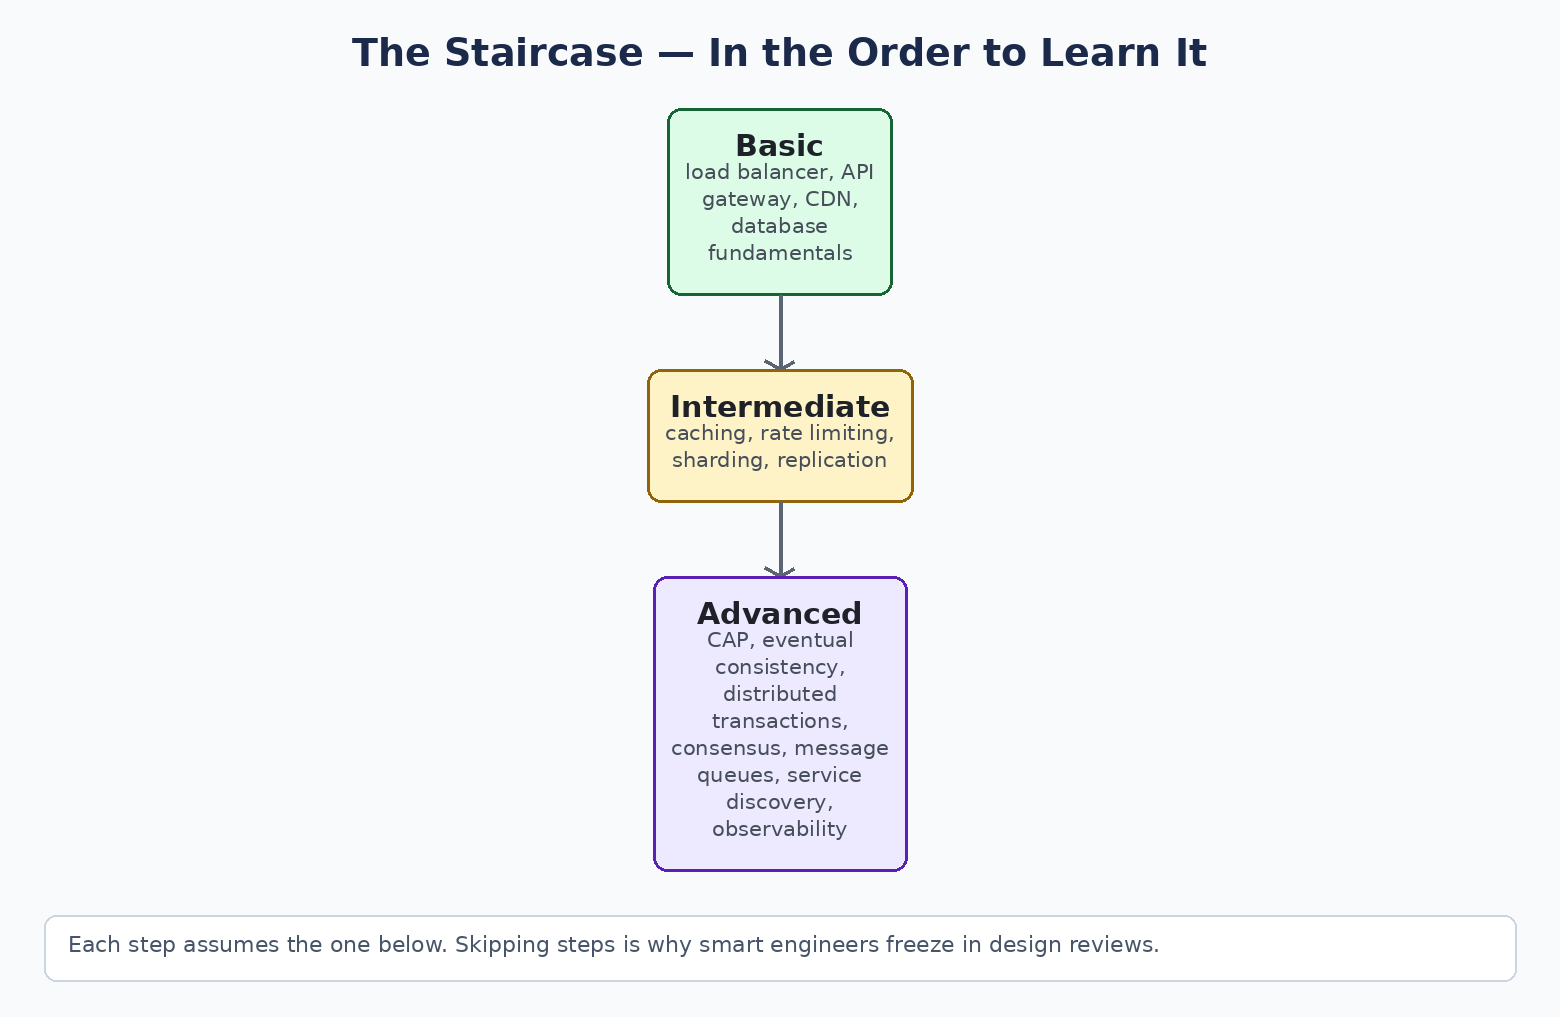
    System design feels overwhelming for one reason: people try to learn it from the top step. Consensus algorithms before load balancers. Distributed transactions before databases. The knowledge is a staircase, not a pile — each step assumes the one below it, and climbing in order turns a scary subject into a sequence of small, obvious ones.

    The system design staircase: basic, intermediate, advanced

    Step 1: Basic — how one system serves users

    Load Balancer. One front door that distributes incoming traffic across servers, so no single machine is the ceiling. (NGINX, AWS ELB.)

    API Gateway. The single entry point for client requests: routing, authentication, and rate limiting handled in one place instead of inside every service. (Kong, AWS API Gateway.)

    Content Delivery Network (CDN). Static assets copied to servers near the user, so a page in Texas does not wait on a disk in Virginia. (Cloudflare, Akamai.)

    Database Fundamentals. Where structured data lives — SQL (MySQL, PostgreSQL) and NoSQL (MongoDB) — and how it is queried. Everything above this step exists to protect or feed the database.

    Master these four and you can design a system that serves real users. Most internal tools never need more.

    Step 2: Intermediate — how a system grows

    Caching. Keep hot data in memory so the database stops answering the same question a million times a day. (Redis, Memcached.)

    Rate Limiting. Cap requests per user or app, so growth — or abuse — cannot take the system down with enthusiasm.

    Database Sharding. Split a dataset across machines, by user ID or region, when one database honestly cannot hold or serve it all.

    Replication. Copy data across servers for high availability and disaster recovery — the master–slave setups that keep reads fast and data alive.

    This step is where most production systems live. If Step 1 is “working,” Step 2 is “working at ten times the traffic.”

    Step 3: Advanced — how systems agree, survive, and stay honest

    CAP Theorem. During a network partition, choose consistency or availability. The trade-off that defines distributed systems.

    Eventual Consistency. The relaxation of CAP: all nodes will agree eventually, just not instantly. (DynamoDB and most planet-scale systems.)

    Distributed Transactions. Keeping an operation atomic across services and databases — coordination protocols like 2PC, and patterns like SAGA when 2PC does not fit.

    Consensus Algorithms. How distributed nodes agree on anything — leader, value, state — when some of them are lying dead. (Paxos, Raft; inside etcd and ZooKeeper.)

    Message Queues. Decoupling services with asynchronous communication, so a slow consumer never blocks a fast producer. (RabbitMQ, Kafka.)

    Service Discovery. In environments where services appear, disappear, and move, something must keep the phone book. (Consul, Eureka.)

    System Observability. Monitoring, logging, and tracing — knowing the system’s health from the outside before your users tell you from the inside. (Prometheus, Grafana, Jaeger.)

    The bottom line

    Basic serves users, intermediate survives growth, advanced survives failure and disagreement. Learn — and interview, and design — in that order, and you will never freeze in a design review again.

    Climbing the staircase? The free toolkits collect the reference posters for each step.

  • 12 Kafka Concepts That Explain Real-Time Data Engineering

    Every food order, cab ride, payment, and delivery tracking screen you have ever watched was powered by events moving between systems. Kafka is the backbone most of those systems chose. Twelve concepts explain nearly all of it — and they build on each other in order.

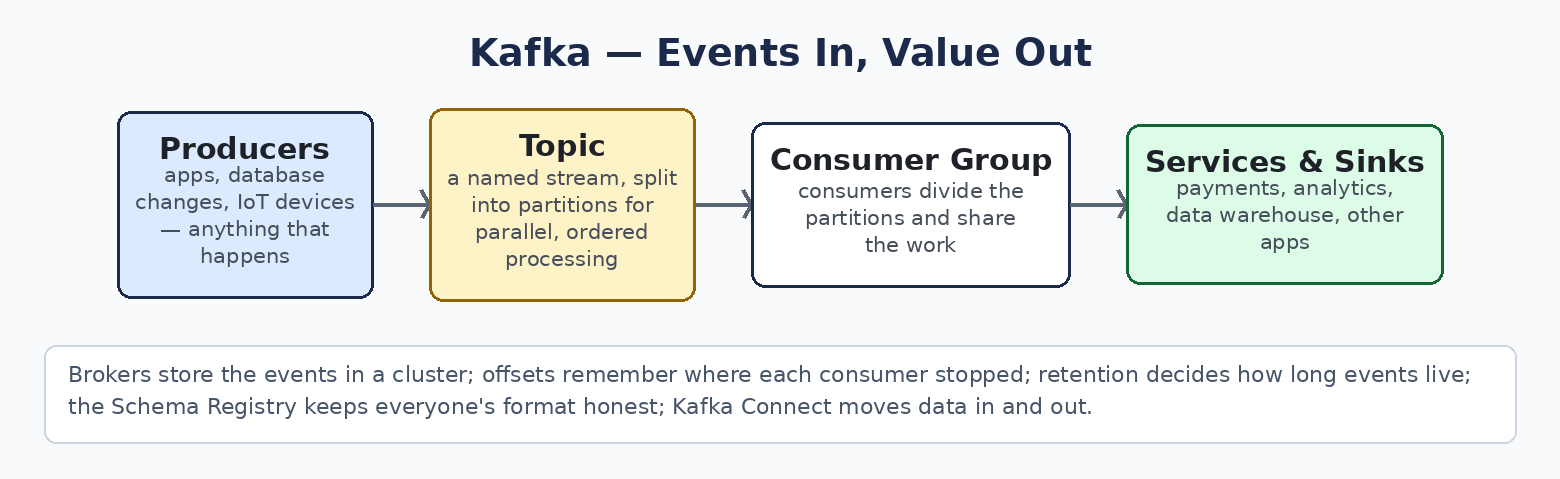
    Kafka flow: producers, topics, consumer groups, services

    1. Producer. Anything that creates events: an app, a database change, an IoT sensor. A producer’s whole job is to fire events into Kafka, continuously, and move on — it never waits for whoever will use them.

    2. Topic. A named stream of related events — orders, payments, clicks. Topics are how Kafka organizes the firehose into channels with meaning.

    3. Partition. Each topic is split into partitions — parallel lanes. Partitions are where Kafka’s scale comes from (many consumers can read different lanes at once) and where ordering lives: events are ordered within a partition, not across the whole topic.

    4. Consumer. A service that reads events from topics and does work with them — updates inventory, sends the notification, writes to the warehouse.

    5. Consumer Group. Consumers working as a team. Kafka divides the topic’s partitions among the group’s members, so adding consumers adds parallel processing — up to the number of partitions, which is why partition count is a design decision, not a detail.

    6. Broker. A Kafka server. It receives events from producers, stores them, and serves them to consumers.

    7. Cluster. Many brokers working as one system. The cluster is what gives Kafka its scale (spread the load) and its resilience (survive losing machines).

    8. Offset. A bookmark. Every event in a partition has a position number, and each consumer group remembers its offset — where it stopped reading. Crash, restart, redeploy: the consumer resumes from its offset instead of starting over or losing events.

    9. Replication. Partitions are copied across brokers. If the broker holding a partition dies, a replica takes over and no data is lost. Replication is the difference between “event streaming” and “event streaming you can run a bank on.”

    10. Retention. Kafka does not delete an event after it is read. It keeps events for a configured time (or size) — seven days, say — so a new consumer can replay history, and a broken one can catch up. This single property separates Kafka from ordinary message queues.

    11. Schema Registry. The contract office. Producers and consumers register the exact format of their events, so a producer cannot silently change a field and break fifty downstream consumers at 3 AM.

    12. Kafka Connect. Prebuilt bridges that move data between Kafka and the outside world — databases in, warehouses and SaaS apps out — without hand-written producer and consumer code for every source and sink.

    The one-sentence version

    Producers write events into partitioned topics stored across a replicated cluster of brokers; consumer groups read them in parallel, track their place with offsets, keep them as long as retention allows, and trust the Schema Registry and Connect to keep the whole ecosystem honest and connected.

    Remember that sentence and you understand Kafka well enough to design with it. Everything else is tuning.

    Streaming is one layer of the modern data stack — the free toolkits map the rest.

  • The Full System Design + AI Stack for 2026–27, Layer by Layer

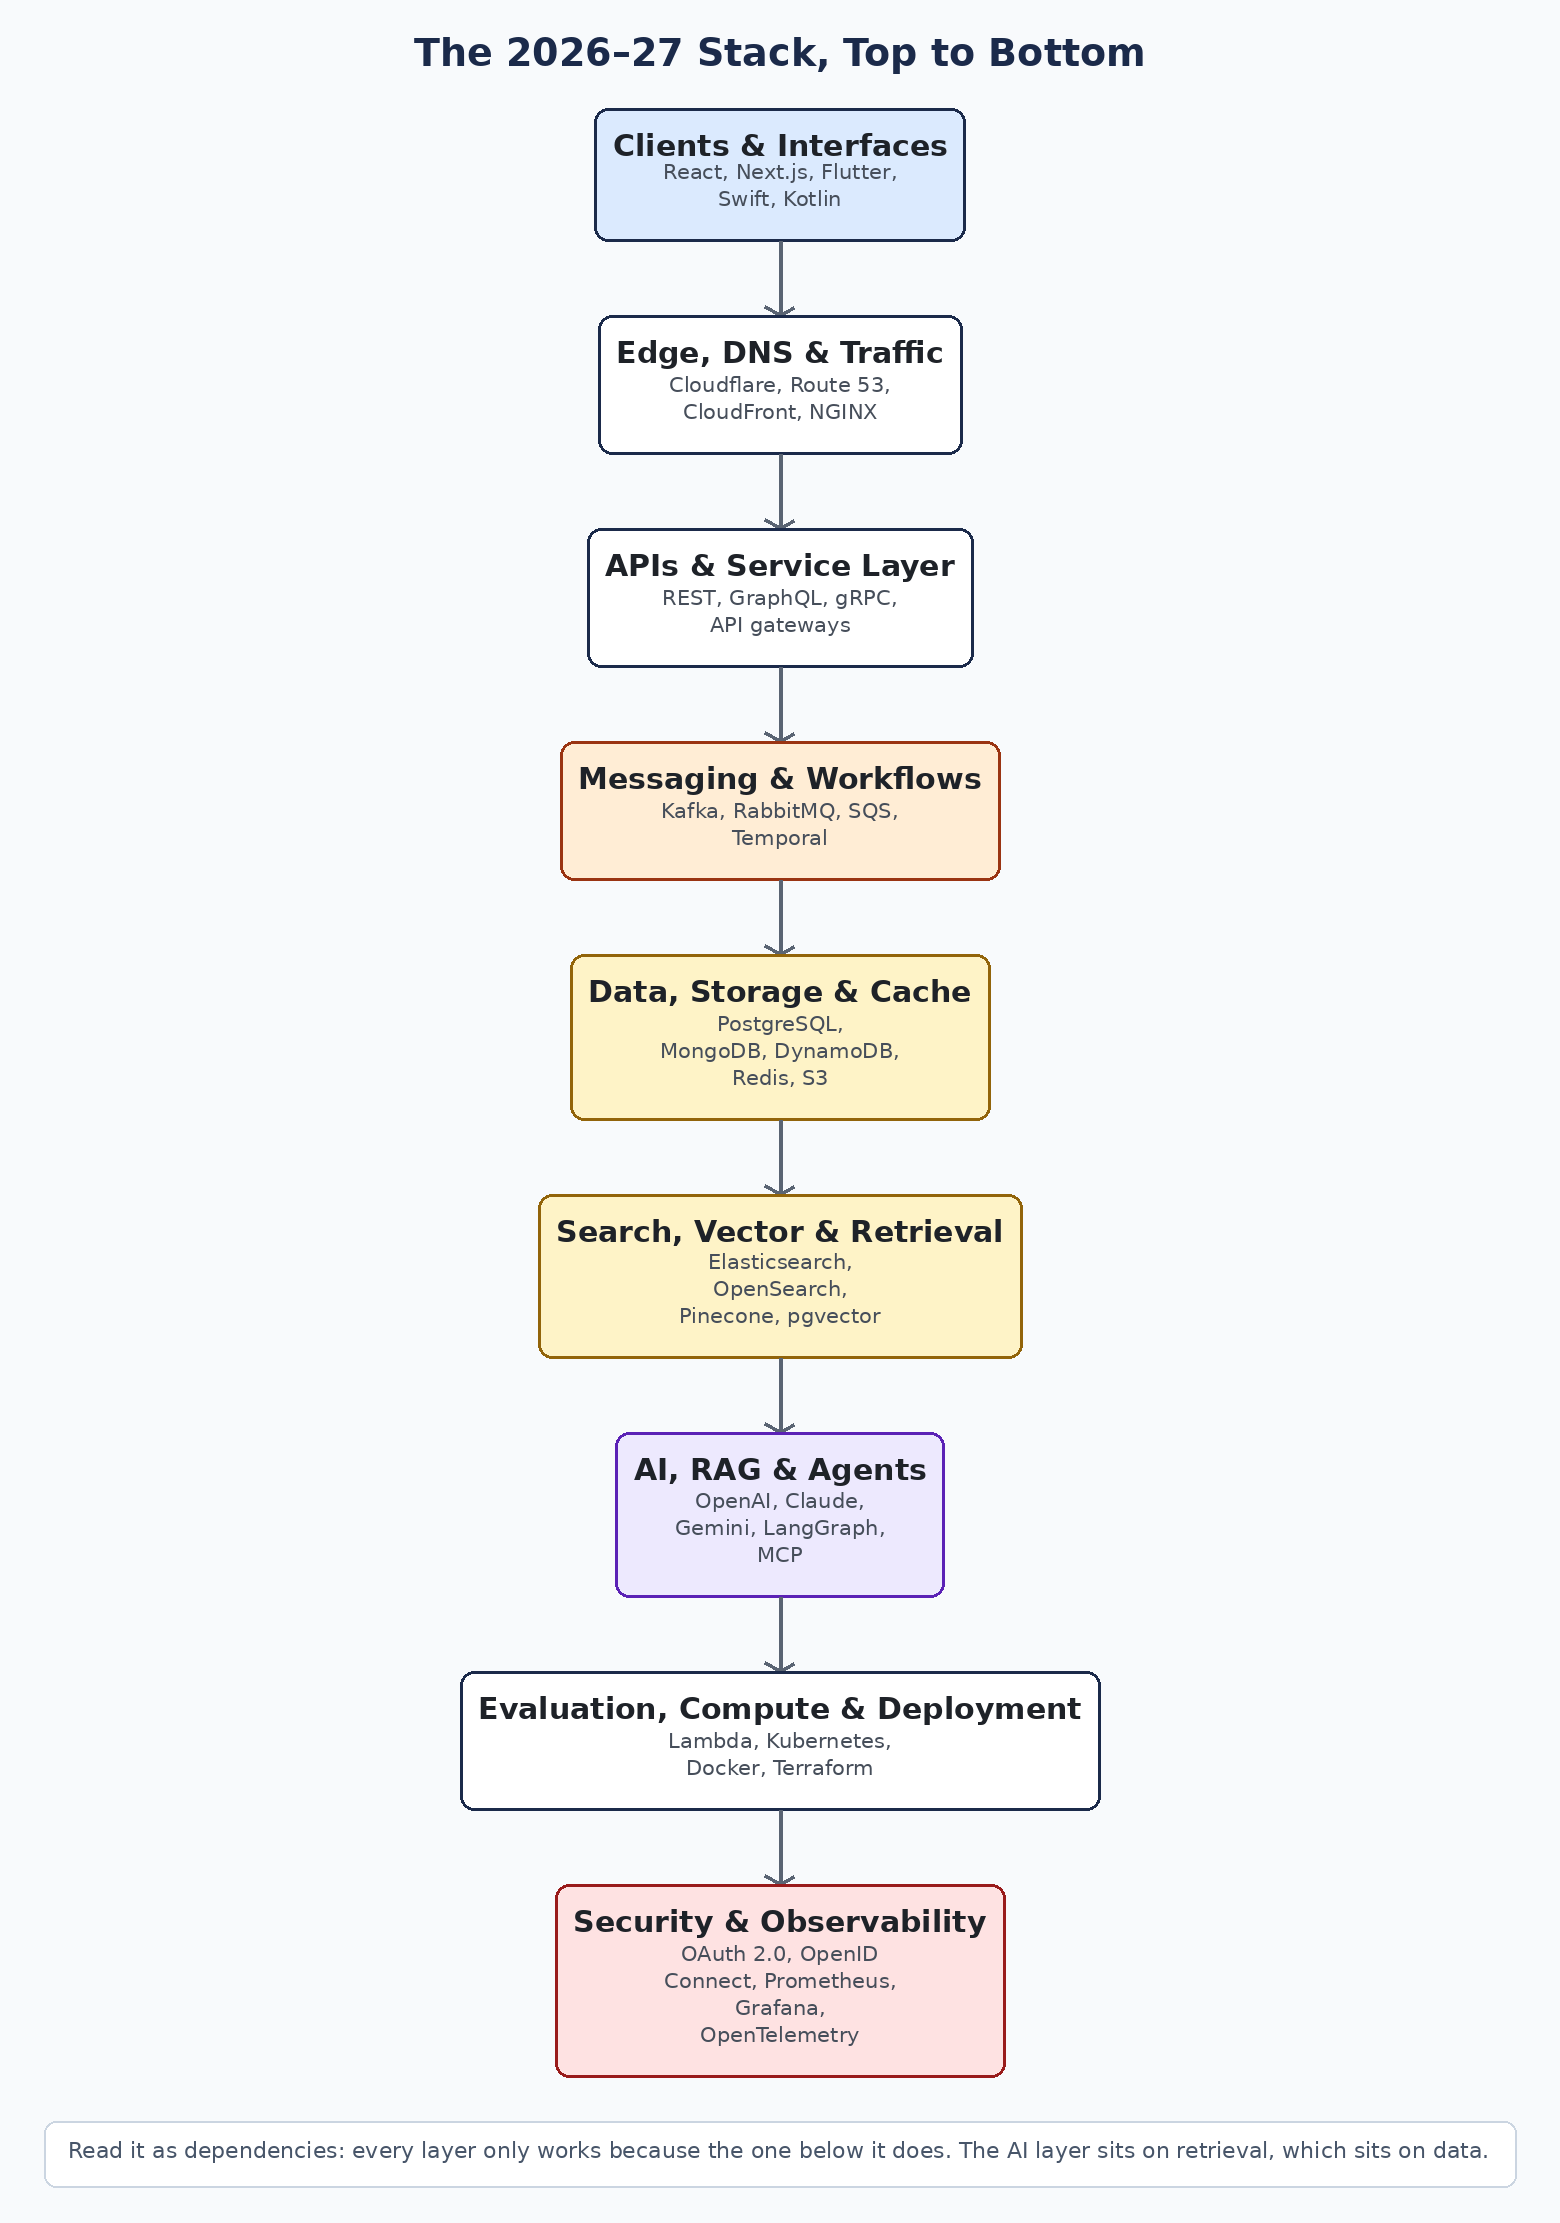
    Every modern system — and every AI product built on one — is a stack of nine layers. Tools change every year; the layers barely do. Learn the layers and you can walk into any architecture diagram, any vendor pitch, any design review, and know exactly where you are standing.

    The 2026-27 system design and AI stack, layer by layer

    1. Clients & Interfaces. What the user touches: web apps (React, Next.js), mobile (Flutter, Swift, Kotlin, React Native). This layer decides nothing about scale — but everything about perceived speed.

    2. Edge, DNS & Traffic. How requests find you and get close to the user: DNS (Route 53), CDNs and edge networks (Cloudflare, CloudFront), and the proxies (NGINX, HAProxy, Envoy) that terminate and route traffic. Geography is latency; this layer is where you cheat geography.

    3. APIs & Service Layer. The contracts everything speaks: REST, GraphQL, gRPC — fronted by API gateways (Kong, Apigee, AWS API Gateway) that own authentication, rate limiting, and routing once, for every service behind them.

    4. Messaging & Workflows. How services talk without waiting on each other: Kafka, RabbitMQ, SQS, NATS, Pulsar for events and queues; Temporal for long-running workflows that must survive failures. This is the layer that turns a fragile chain of calls into a resilient flow.

    5. Data, Storage & Cache. The ground everything stands on: relational (PostgreSQL, MySQL), document and NoSQL (MongoDB, DynamoDB), object storage (S3), and cache (Redis) for the reads that cannot afford a database trip. Choose by access pattern, not by habit.

    6. Search, Vector & Retrieval. Finding things by meaning, not just by key: Elasticsearch and OpenSearch for text search; Milvus, Pinecone, Weaviate, and pgvector for embeddings. This layer did not exist in most stacks five years ago; it is now where AI systems live or die, because retrieval quality is answer quality.

    7. AI, RAG & Agents. The models (OpenAI, Claude, Gemini) and the frameworks that wire them to your data and tools: LangGraph, LlamaIndex, and MCP — the protocol becoming the standard way agents connect to tools. Notice where this layer sits: seventh, not first. It is powerful precisely because the six layers beneath it are solid.

    8. Evaluation, Compute & Deployment. Where everything runs and how you know it works: Lambda and Cloud Run for serverless, Kubernetes and Docker for containers, Terraform and GitHub Actions for the pipeline. For AI systems this layer also carries evaluation — the checks that prove a model change helped instead of quietly hurting.

    9. Security & Observability. The layer that wraps all the others: OAuth 2.0 and OpenID Connect for identity, Vault for secrets, and Prometheus, Grafana, Datadog, and OpenTelemetry so you can see what the system is actually doing. If you cannot observe it, you do not operate it — you hope.

    How to use this map

    When a system misbehaves, locate the layer before reaching for a fix — most “AI problems” are retrieval problems (layer 6) or data problems (layer 5) wearing a model costume. When a vendor pitches you, ask which layer they replace and which layers they assume you already have. And when you design something new, walk the stack top to bottom and make one deliberate choice per layer.

    The bottom line

    Products are built from tools, but architectures are built from layers. Master the nine layers and the tool names — which will keep changing — become the easy part.

    The free toolkits include the AI Engineering Iceberg Poster — the same idea, drawn for the AI stack specifically.

  • Monolith vs Microservices: The Honest Comparison

    This is the most argued decision in software architecture, and most teams make it for the wrong reason — fashion, a conference talk, or a resume. The honest version is simpler: a monolith is one application that deploys together; microservices are many small applications that deploy independently. Everything else follows from that.

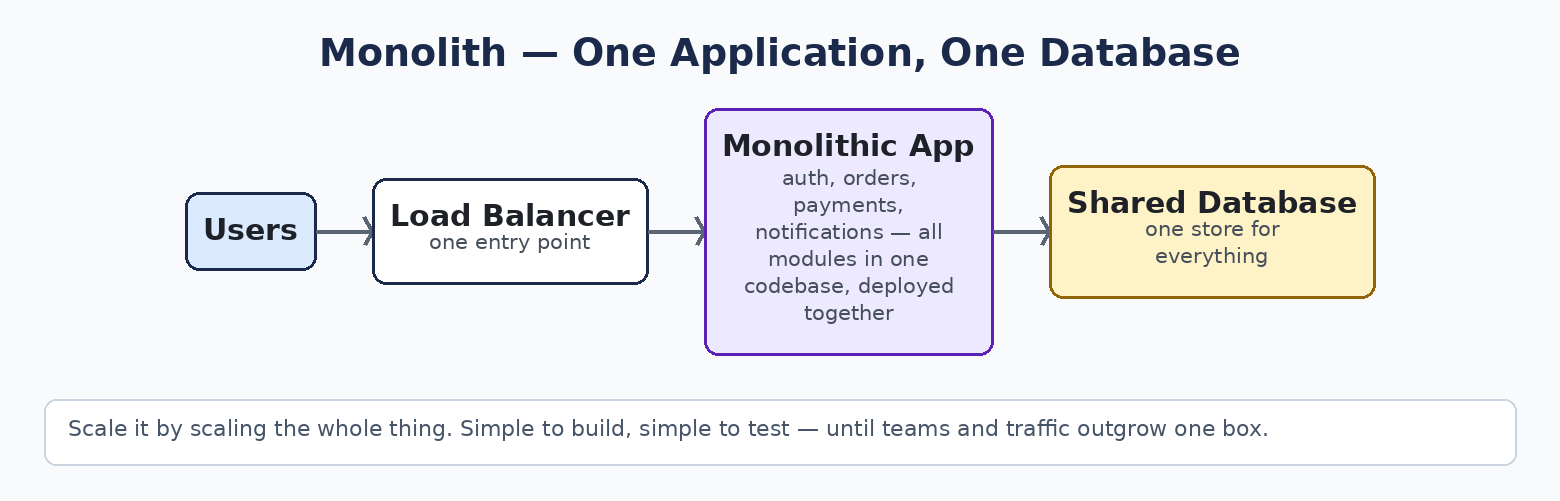
    Monolith request flow
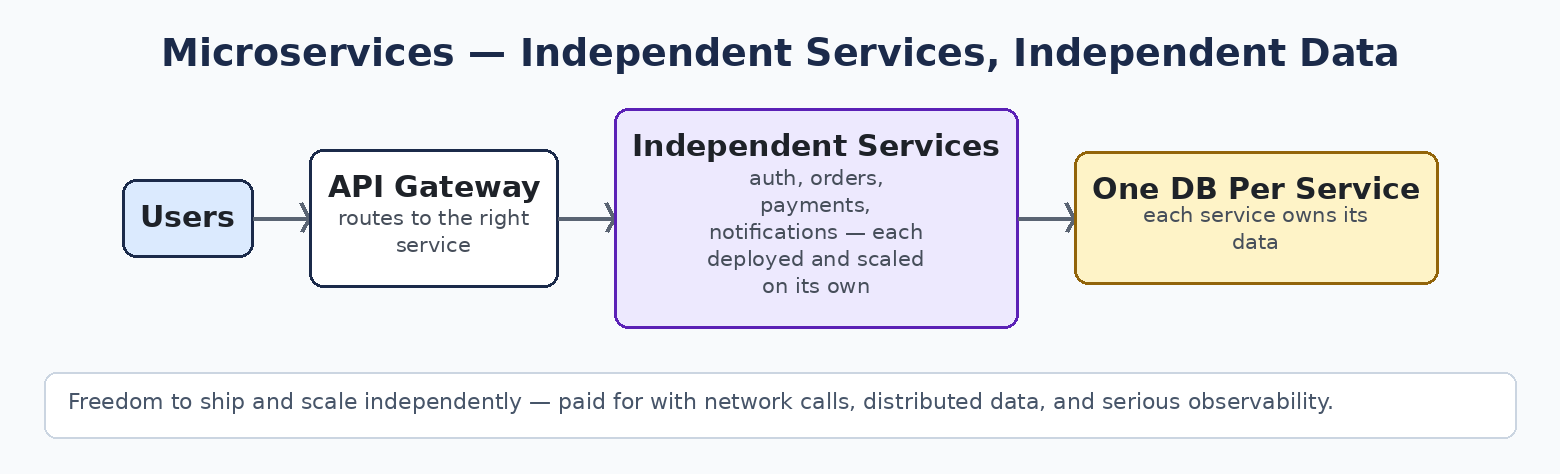
    Microservices request flow

    The two shapes

    Monolith. All modules — auth, orders, payments, notifications — live in one codebase, deploy as one unit, and usually share one database. A request travels inside a single process: function calls, not network calls.

    Microservices. The application is split by business capability. Each service owns one job, its own codebase, its own deployment pipeline, and its own database. Services talk through APIs and events.

    Side by side

    FeatureMonolithMicroservices
    CodebaseOneOne per service
    DeploymentEverything togetherEach service independently
    ScalingScale the whole appScale only the hot service
    CouplingTight — modules touch directlyLoose — contracts between services
    DataUsually one shared databaseDecentralized, per service
    Fault isolationOne failure can take the app downFailures can be contained
    Development speedFast earlyFaster for many large teams
    TestingSimpler end-to-endComplex integration testing
    OperationsEasy to runDemands automation + observability
    Best forSmall/medium apps, early productsLarge, complex platforms

    When each one wins

    Choose a monolith when the team is small, the domain is still being discovered, and speed of change matters more than independent scale. Most products should start here: you can refactor a working monolith; you cannot refactor a distributed system you did not need into existence.

    Choose microservices when the pain is real and named: teams stepping on each other’s releases, one module needing 50× the scale of the rest, or independent deployment becoming a business requirement. Microservices trade code complexity for organizational scalability — that is the actual product you are buying.

    The analogy that settles it

    A monolith is a department store: everything under one roof, one management, easy to run — and a fire anywhere can close the whole store. Microservices are a shopping complex: specialized stores, each opening, closing, and expanding on its own — and now somebody has to run the mall: security, utilities, parking, signs. Neither is “better.” They are answers to different sizes of problem.

    The bottom line

    Start simple. Earn the complexity. Move to microservices when scale, team autonomy, and independent deployment become real needs with names and numbers — not when a blog post says monoliths are dead. The best architecture is the one your team can actually operate at 2 AM.

    More architecture decisions, made the same honest way: the free toolkits and posters collect them.