Every enterprise AI program hits the same architectural moment. The model is selected, the proof of concept impressed the room, and then somebody asks the production question: how do we serve this — at our volume, our latency targets, our cost ceiling?
That question is an architecture decision, and it deserves to be treated like one. The serving engine you choose determines your GPU economics (how many users one accelerator can carry), your latency profile (how fast the first token arrives under load, not in a demo), your scaling ceiling, and your operational burden for years. Choose on fashion and you will re-platform within two quarters. Choose on workload shape and the decision holds.
Three engines dominate the open-source serving conversation: Ollama, vLLM, and SGLang. They are usually compared as competitors. From an architect’s chair, they are better understood as three design centers — three different answers to three different traffic shapes:
- Ollama is designed around a person — one developer, one machine, minimal surface area.
- vLLM is designed around a crowd — high concurrency, mostly unique prompts, maximum throughput per GPU.
- SGLang is designed around a conversation — agents and multi-turn systems whose requests share long, growing prefixes that should never be computed twice.
This deep dive works the way an architecture review should: the mechanics first, then each engine on its merits and limits, then the capacity math, the scaling patterns, the failure modes — and only then the recommendation.
The mechanics that decide everything
Serving economics are governed by a handful of mechanisms. Every claim in this article reduces to one of them.
Prefill and decode. Each request has two phases. Prefill processes the prompt — parallel, compute-heavy, done once. Decode generates the answer one token at a time, each step dependent on the last — sequential and memory-bandwidth-bound. Prefill cost scales with prompt length; decode cost scales with answer length and with how much state the engine must re-read at every step. Most serving optimization is an attack on one of these two phases.
The KV cache is the real capacity constraint. During generation, the model stores the attention keys and values for every token it has processed, so nothing is recomputed. This cache grows linearly with context length and with concurrent requests. In production, the KV cache — not the model weights — is usually what exhausts GPU memory first. How an engine allocates, shares, and evicts this cache is the single strongest predictor of how many users it can serve per GPU.
Batching, and why “continuous” changed the field. GPUs are throughput machines: processing 32 sequences together costs little more than processing one. Static batching assembles a fixed group and runs it to completion — one long generation stalls the entire group. Continuous batching (iteration-level scheduling) admits and retires requests at every token step: a finished request releases its slot instantly, a waiting one takes it. This is the mechanism behind the modern engines’ throughput advantage, and it is non-negotiable for multi-user serving.
Latency vs. throughput is a trade you make explicitly. The user-facing metrics are time-to-first-token (TTFT) and per-token latency under load; the business-facing metric is aggregate tokens per second per GPU, which is cost. Larger batches raise throughput and can raise individual latency. An architecture that does not state which side of this trade it is optimizing — interactive chat or overnight batch — is not finished.
Quantization moves the memory budget. Storing weights at 4-bit instead of 16-bit shrinks a model roughly four-fold, at a small quality cost. GGUF is the quantized format the local ecosystem standardized on. Quantization matters architecturally because every gigabyte not spent on weights is a gigabyte available for KV cache — which is to say, for users.
Prefix reuse is free throughput, if your traffic has prefixes. Requests that share a beginning — a system prompt, tool definitions, a conversation’s history — can reuse the KV cache computed for that beginning instead of recomputing it. The architectural question is never whether an engine caches prefixes; it is how granular the sharing is (whole blocks? branching trees?) and whether scheduling and routing cooperate to keep the cache warm.
Constrained decoding turns output contracts into guarantees. Forcing generation to obey a JSON schema, regex, or grammar — by masking invalid tokens during decode — converts “the model usually returns valid JSON” into “the output is valid by construction.” For agent pipelines and tool calling, this is the difference between a system and a hope.
1. Ollama — the developer-machine engine
How it works. Ollama packages the llama.cpp inference engine behind a one-command experience: pull a quantized GGUF model, run it, call it over a local API (its own REST interface, plus an OpenAI-compatible endpoint). Requests to a model are queued and processed one at a time by default (OLLAMA_NUM_PARALLEL, default 1), with up to 512 requests waiting before the server starts returning errors. Models load on demand and unload after roughly five idle minutes. Everything runs locally and offline; hosted cloud models exist as an optional extra.
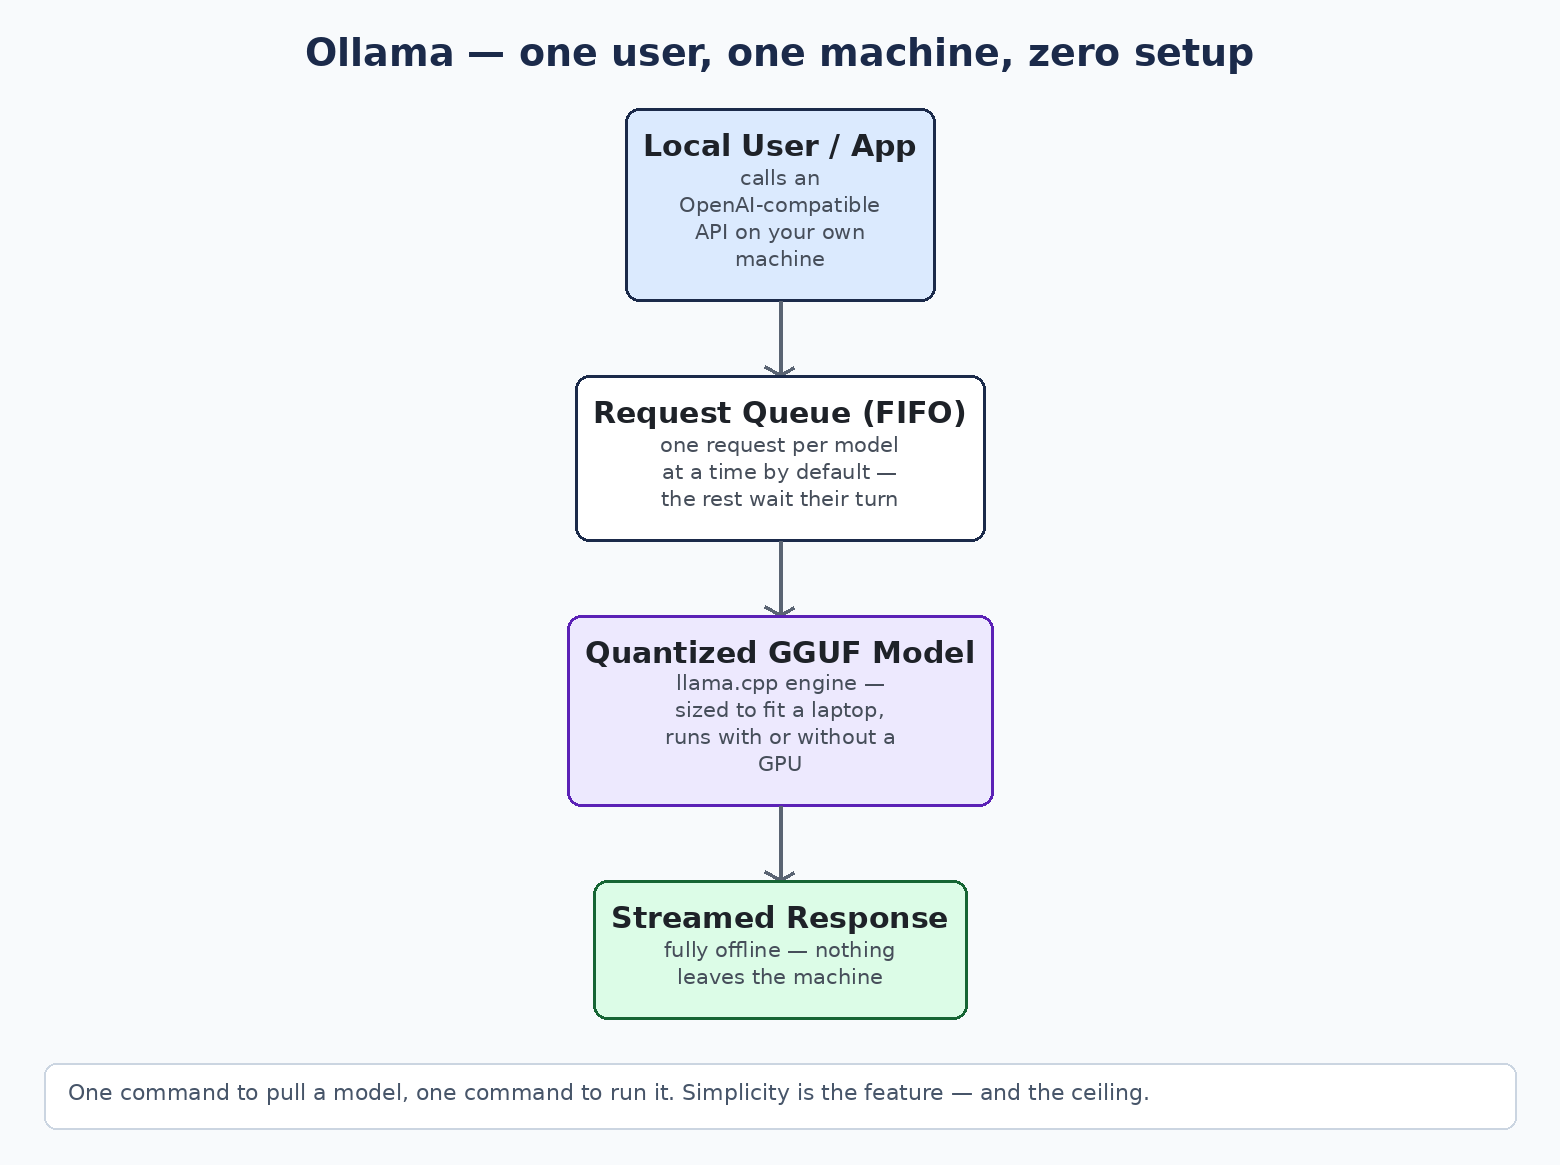
Where it earns its place. Developer workstations, proofs of concept, and genuinely small internal tools. Its architectural virtue is a tiny operational surface: no cluster, no tuning, no GPU fleet — a model running in minutes on a laptop, including machines with no discrete GPU. For data-residency-sensitive experimentation, “nothing leaves this machine” is a complete architecture, and Ollama delivers it with the least ceremony in the field. A large share of enterprise AI work starts here, and low-concurrency internal tools legitimately stay here.
Where it breaks. The design center is a single user. Raise the parallel setting and each slot multiplies reserved context memory; there is no continuous batching, so under real concurrency the queue — not the GPU — becomes the bottleneck, and latency grows linearly with arrivals while the hardware idles. There is no built-in authentication (it assumes a trusted local network), no multi-GPU serving story, and no meaningful observability surface for production SLOs. None of this is a defect; it is a boundary. The failure mode is ignoring the boundary — promoting a developer tool into a serving tier because it was already installed.
The architect’s verdict. Standardize on Ollama for the inner loop: development, evaluation, demos, and isolated single-user tools. Write the exit into the design from day one — code against the OpenAI-compatible endpoint, so promoting the workload to a production engine is a deployment change, not a rewrite.
2. vLLM — the production throughput engine
How it works. vLLM, out of UC Berkeley, is built on one diagnosis: legacy serving wasted most of the KV cache. Older systems reserved each request a contiguous slab of GPU memory sized for its maximum possible generation, and the vLLM paper measured that only a small fraction of the reservation ever held live data. PagedAttention applies the operating-system answer — paging. The KV cache is divided into small fixed-size blocks, allocated wherever memory is free, with a block table mapping each request’s logical sequence to physical blocks. Waste collapses to the tail of the final block — under 4% in the paper’s measurements — and the recovered memory converts directly into larger batches. Layered on top: continuous batching at the token step, prefix caching enabled by default in the current V1 engine, tensor and pipeline parallelism for models that exceed one GPU, and the broadest model and accelerator support in the open ecosystem, behind an OpenAI-compatible API.
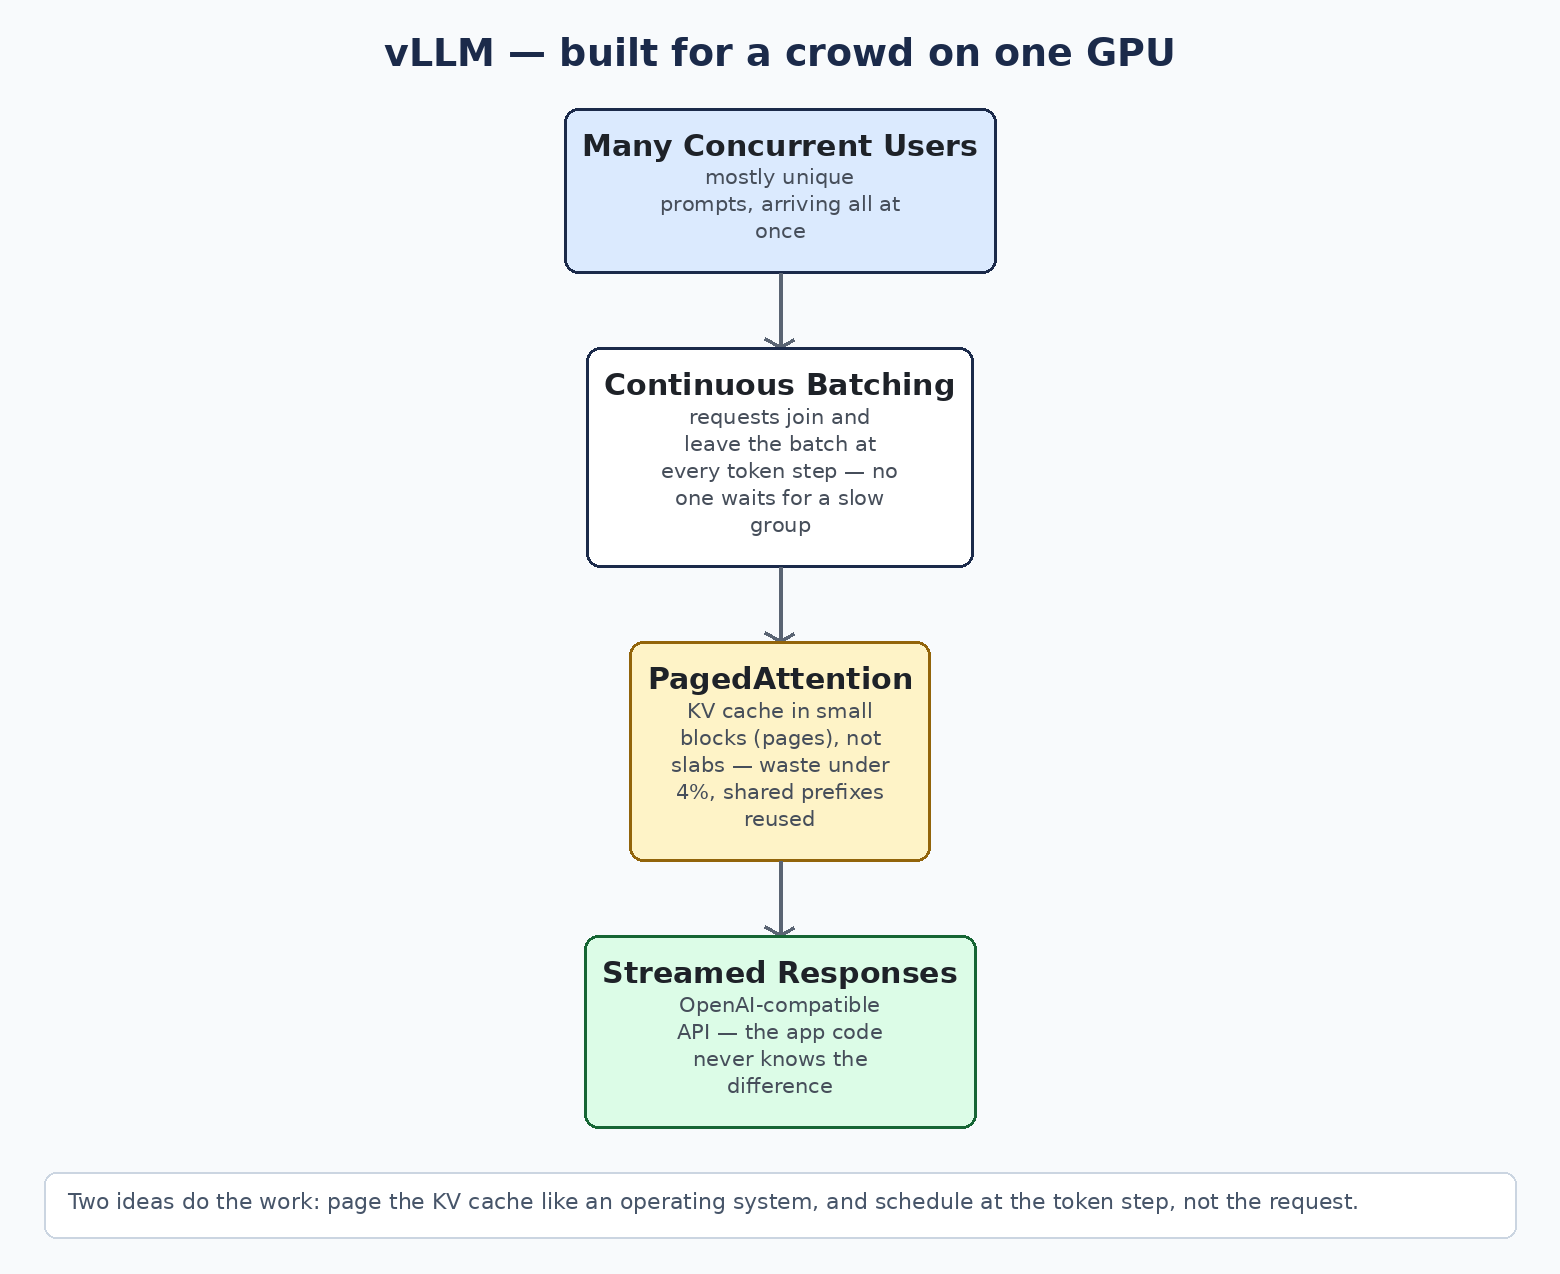
Where it earns its place. The default production serving tier. Public and internal API platforms with many concurrent users and mostly unique prompts; enterprise chat and RAG front doors; and batch estates — document processing, enrichment, evaluation — where overnight throughput per dollar is the governing metric. When a capacity plan says “we must carry N concurrent sessions on M GPUs,” vLLM is the engine that makes the arithmetic work, and it is the baseline against which every alternative must benchmark.
Where it breaks. It is data-center infrastructure, with a data-center footprint: it assumes real GPUs (it is not a workstation tool), and by default it claims ~90% of GPU memory, which collides with shared-card environments. The tuning surface is real — memory utilization, max concurrent sequences, block size, chunked-prefill behavior — and rewards teams that load-test over teams that guess. Its prefix caching, while solid, is block-granular and designed for breadth; workloads whose traffic is dominated by long shared prefixes are precisely the shape the next engine was designed around. Operationally, you are adopting a fast-moving platform: version discipline and upgrade testing belong in the runbook.
The architect’s verdict. Make vLLM the reference architecture for shared, multi-user LLM serving unless the workload’s shape argues otherwise. Budget the engineering honestly — load testing, tuning, GPU capacity management — because the engine’s economics only materialize when it is operated as infrastructure, not installed as a package.
3. SGLang — the engine for agent and conversation traffic
How it works. SGLang, from the LMSYS team, starts from an observation about production agent traffic: requests in these systems are not independent. An agent’s fifteenth tool call carries the same system prompt, the same tool definitions, and the same accumulated history as its fourteenth — plus one delta. RadixAttention manages the KV cache as a radix tree keyed by token prefixes: an incoming request walks the tree, reuses every matching cached prefix — including branching, multi-level sharing across sessions that diverged from a common trunk — and computes only the new suffix. Unused branches are evicted LRU-style, so the cache behaves like a cache, not a leak. The scheduler is cache-aware: it orders work so requests sharing a prefix run while their shared branch is resident, and in multi-worker deployments its router directs each request to the worker already holding that prefix. Its constrained decoding compiles the output grammar into a compressed finite-state machine, allowing the decoder to advance through forced token stretches in jumps — structured output that is both guaranteed and fast. Continuous batching and the rest of the modern toolkit are present, as they now are everywhere.
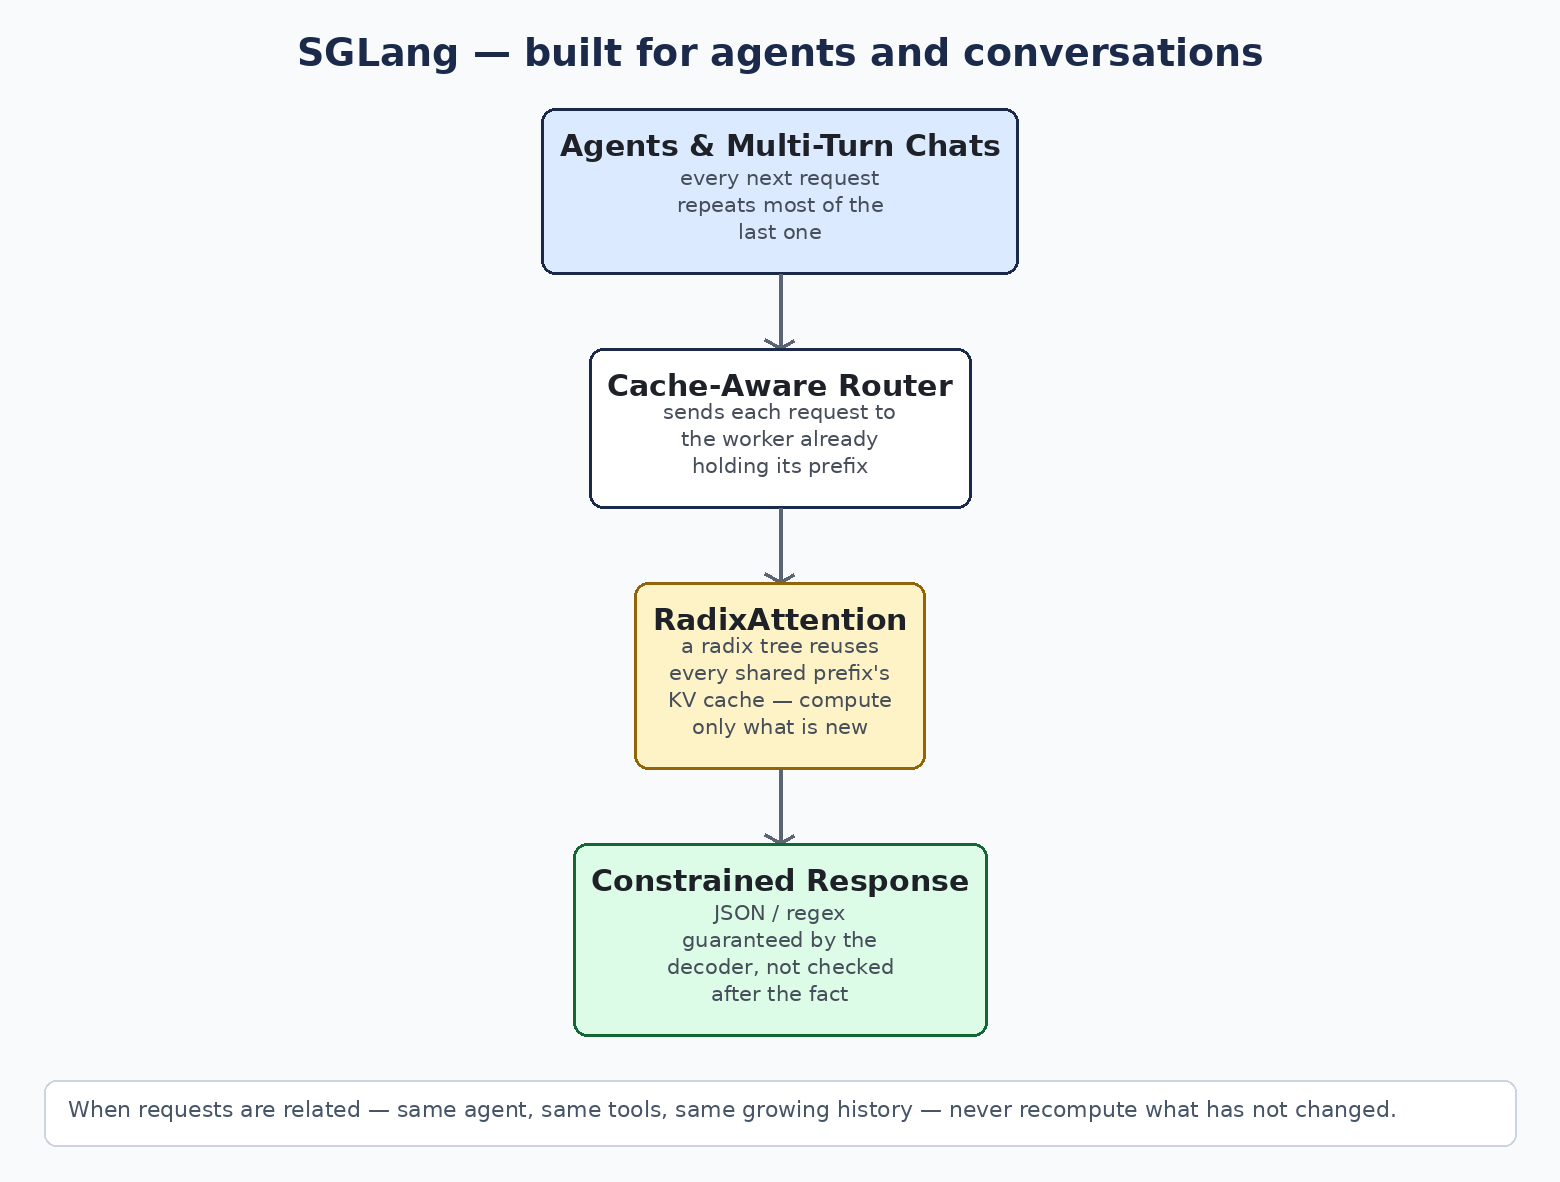
Where it earns its place. Agent platforms and tool-calling loops, where each step resends a growing context and naive serving re-bills you for your own history at every step. Multi-turn chat at scale, where a conversation’s history is literally a prefix of its next request. Few-shot and self-consistency patterns, which are prefix-sharing by construction. RAG serving with long, stable system prompts and templates. In these shapes, prefix reuse is not a micro-optimization: it compounds with concurrency (more sessions share more of the tree) and flattens the cost curve that otherwise grows with conversation length.
Where it breaks. Remove the shared prefixes and you remove the thesis: on unique, unrelated prompts, SGLang performs comparably to vLLM, and you have adopted a specialist to do a generalist’s job. Its ecosystem — documentation depth, community answers at 2 AM, day-one support for exotic new models — is smaller than vLLM’s, which is a real operational cost that belongs in the decision record. Cache-awareness also introduces a systems subtlety: routing and scheduling now have state (where prefixes live), which complicates load balancing and failover design compared to stateless round-robin over identical workers.
The architect’s verdict. Where agent and multi-turn traffic is a first-class workload — not an experiment — SGLang is the architecturally correct answer, because it is the only one of the three whose core data structure matches the traffic’s shape. Pilot it against your real prompt distribution; the prefix hit-rate in your own telemetry is the number that justifies it.
Capacity planning: the math that sizes the decision
Engine selection is inseparable from sizing. The governing equation is simple to state:
GPU memory = model weights + KV cache + runtime overhead, and KV cache ≈ per-token cache size × context length × concurrent sequences.
Three consequences drive most real designs:
- Concurrency is bought with cache. A modest model serving fifty concurrent users at long context can require more memory for KV cache than for its weights. This is why PagedAttention’s waste elimination and RadixAttention’s sharing are economic features, not academic ones — every recovered gigabyte is headroom for sessions.
- Quantization is a capacity lever, not just a quality trade. Halving weight precision frees memory that converts directly into concurrent sessions or longer contexts. Evaluate quantized variants against your quality bar explicitly; for many enterprise workloads the 4-bit/8-bit quality delta is smaller than the concurrency delta is valuable.
- Prefix hit-rate is a capacity input. In agent estates, a high radix-cache hit rate reduces effective prefill — often the dominant compute — by the shared fraction. Two deployments with identical GPUs can differ several-fold in carried sessions purely on how much of each prompt was already cached. Measure your prompt-overlap distribution before you size anything.
A defensible capacity plan names: target concurrent sessions, p95 context length, target TTFT and per-token latency at that concurrency, and the resulting GPU count per engine. If a vendor or a blog gives you tokens-per-second without the concurrency and context it was measured at, it has given you marketing, not engineering.
Scaling patterns
Single node → multi-GPU. When a model exceeds one GPU, tensor parallelism shards it across devices; this is a serving-tier concern (vLLM and SGLang), never a workstation one. Treat interconnect bandwidth as part of the design — tensor parallelism is chatty.
Single replica → fleet. Scale-out adds a routing tier, and here the engines diverge architecturally. Stateless round-robin is simple and works acceptably for vLLM, though per-replica prefix caches mean shared prefixes get recomputed across the fleet. For SGLang-class workloads, cache-aware routing — directing a session to the replica holding its prefix — is the difference between the design working and the design merely running. Stateful routing buys hit-rate with failover complexity; make that trade consciously.
The gateway is not optional in production. None of these engines is a complete serving platform. The reference pattern wraps the engine tier with authentication and authorization, per-consumer rate limiting and quotas, request logging for audit, and metrics that matter: TTFT and latency percentiles, queue depth, KV-cache utilization, and prefix-cache hit rate. Ollama in particular ships no authentication — anything beyond a workstation must sit behind this tier.
Failure modes worth designing for
- Cache exhaustion under load spike. Long contexts × a concurrency spike exhausts KV memory; engines queue or preempt. Design the degradation: bounded context windows, admission control, and honest 429/503 behavior beat silent latency collapse.
- Prefix-cache thrash. If working-set prefixes exceed cache capacity, hit rates crater and latency regresses toward the no-cache case — a cliff, not a slope. Size the cache to the working set, and alert on hit rate, not just latency.
- Queue saturation on the wrong engine. Ollama’s default — one in-flight request per model, queue of 512, then refusals — is a fine workstation contract and a production outage. This failure mode is a selection error, not a product defect.
- Cold starts. Multi-gigabyte model loads and engine warm-up are minutes, not milliseconds. Autoscaling policies, pre-warmed replicas, and scale-to-zero decisions must be made against that reality.
- Silent quality drift via quantization mismatch. A workload validated at full precision and deployed at 4-bit (the Ollama default) is a different system than the one you tested. Pin precision in the deployment record.
The part most comparisons get wrong
Feature matrices say these engines have converged, and at the checklist level they have: continuous batching, prefix caching, structured outputs, speculative decoding, and quantization are table stakes across the serious engines. Architects should be suspicious of checklist equivalence. What differs is design center, defaults, and the data structure at the core — a FIFO queue tuned for one user, a paged cache tuned for crowd throughput, a radix tree tuned for reuse across related requests. Benchmarks alternate winners between vLLM and SGLang because benchmarks have shapes: each engine wins the workload it was designed around. The professional question is never “which engine is fastest?” It is “what does my traffic actually look like — measured, not assumed — and which design center matches it?”
The second-order point is reversibility. All three engines expose OpenAI-compatible APIs, so the application layer can be insulated from the choice. Prototype on Ollama, launch the shared tier on vLLM, carve the agent estate onto SGLang — each step is a deployment migration, not an application rewrite. An engine decision with a tested exit is a low-risk decision; insist on the exit.
The decision guide
| Your situation | Pick | Why |
|---|---|---|
| Developer inner loop: build, evaluate, demo | Ollama | Minimal operational surface; a model running in minutes, offline, on the machine in front of you |
| Data-residency-bound experimentation; single user or tiny team | Ollama | Local-first by architecture; nothing leaves the machine |
| Shared production API: many concurrent users, mostly unique prompts | vLLM | PagedAttention + continuous batching = the most carried sessions per GPU for crowd-shaped traffic |
| Batch estates: bulk enrichment, processing, evaluation | vLLM | Aggregate throughput is the governing metric; the offline batch path is built for it |
| Enterprise chat / RAG front door with a mixed audience | vLLM (default) | Broadest model and hardware support; prefix caching on by default in V1 |
| Agent platforms, tool-calling loops, multi-turn systems at scale | SGLang | RadixAttention reuses the growing shared context instead of recomputing it every step |
| Hard structured-output contracts inside agent pipelines | SGLang | Compressed-FSM constrained decoding: guaranteed shape, without token-by-token decode penalties |
| Mixed estate: workstations, a shared tier, an agent platform | All three, layered | One OpenAI-compatible interface; each workload on the engine shaped for it |
Record it like an architecture decision
Context. We must serve LLMs under production concurrency, latency, and cost constraints, across three distinct traffic shapes: developer experimentation, a shared multi-user tier, and agent workloads with heavy prefix overlap.
Decision. Ollama is the standard for developer workstations and single-user tools. vLLM is the reference engine for the shared production tier and batch estates. SGLang is the engine for the agent and multi-turn estate. All application code targets the OpenAI-compatible API surface; no application may depend on engine-specific behavior without an explicit exception.
Consequences. We accept operating two production engines (vLLM, SGLang) in exchange for each workload running on its matching design center. We accept cache-aware routing complexity in the agent estate as the price of prefix reuse. Engine migrations between tiers are planned deployment exercises, rehearsed against load tests built from production prompt distributions — because the only benchmark that governs this decision is our own traffic, measured.
The bottom line
Ollama, vLLM, and SGLang are not three rungs of a maturity ladder; they are three shapes of answer. One person iterating: Ollama — and keep the exit clean. A crowd to carry: vLLM — operated as infrastructure, sized by the cache math. Agents and conversations that repeat themselves: SGLang — where the radix tree turns your traffic’s sameness into your margin.
The architects who get this decision right share one habit: they measure the traffic first — its concurrency, its context lengths, its prefix overlap — and let the workload, not the benchmark blog, pick the engine.
Designing a production LLM platform, or reviewing one? The free AI Engineering Iceberg Poster and architecture toolkits cover the systems layer beneath the model — the part that decides whether the platform survives contact with real traffic.


Thanks for the comment, will get back to you soon… Jugal Shah